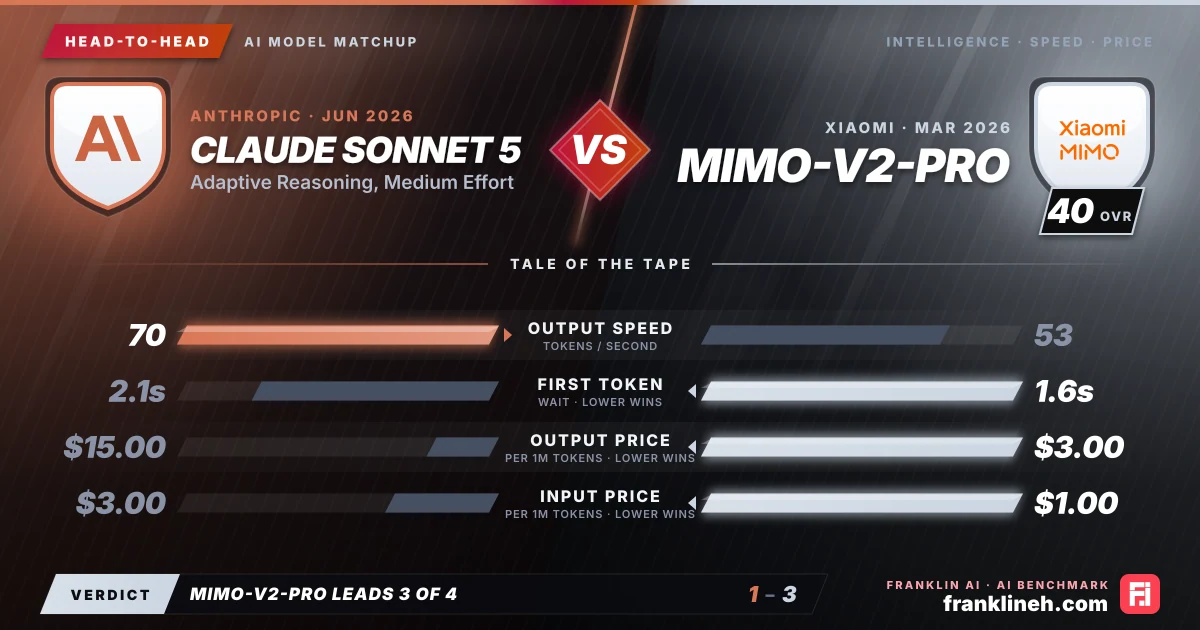
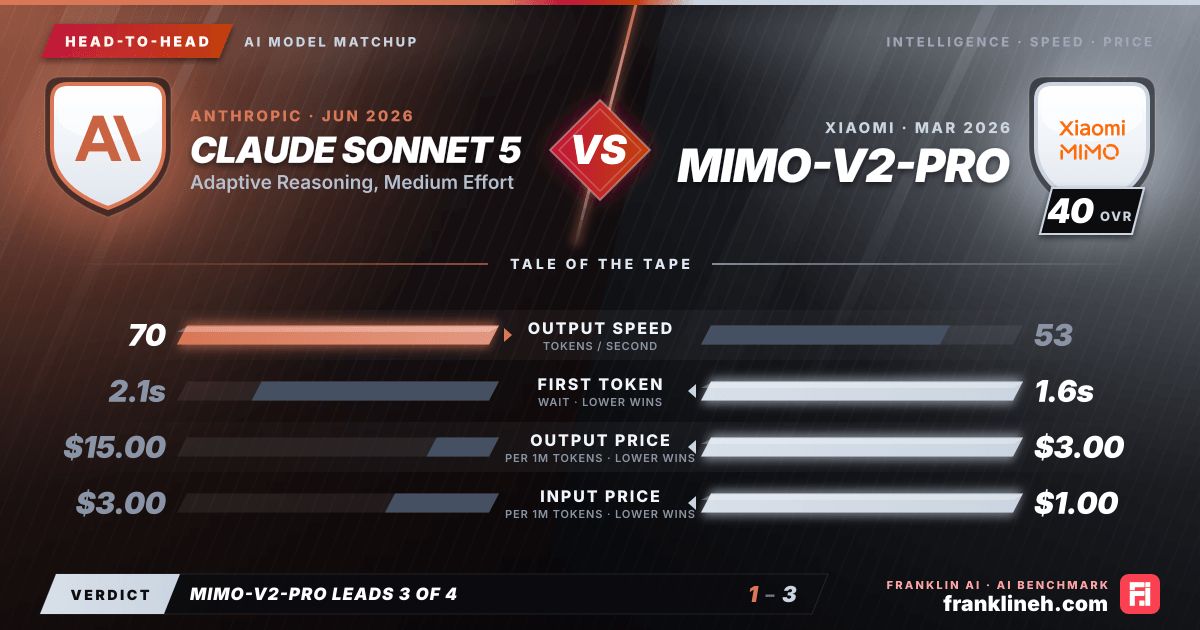
Claude Sonnet 5 vs MiMo-V2-Pro: head-to-head AI benchmark comparison. MiMo-V2-Pro leads on time to first token, output price and input price; Claude Sonnet 5 leads on output speed.
Claude Sonnet 5 and MiMo-V2-Pro offer distinct approaches to AI performance. While MiMo-V2-Pro provides transparent benchmark data and cost-efficiency, Claude Sonnet 5 represents Anthropic’s latest iteration in adaptive reasoning, catering to users within the broader Anthropic ecosystem.
Pick it for Claude Sonnet 5 · Adaptive Reasoning, Medium Effort
Adaptive reasoning tasks
Anthropic ecosystem integration
High-speed output requirements
Pick it for MiMo-V2-Pro
Cost-sensitive applications
Scientific and coding research
Verified benchmark performance
By the numbers
These figures describe the two model configurations shown here. A dash means the source snapshot had no usable figure for that metric. Scores, speed and API pricing may change as providers update models.
Claude Sonnet 5 (released June 30, 2026) and MiMo-V2-Pro (released March 18, 2026) represent two different strategic directions in the current AI landscape. Anthropic’s Sonnet 5 focuses on adaptive reasoning and medium-effort tasks, while Xiaomi’s MiMo-V2-Pro prioritizes transparency through extensive benchmark reporting and aggressive pricing.
Benchmark Read
MiMo-V2-Pro provides a comprehensive look at its capabilities, boasting an Intelligence Index of 40.3. Its performance across specialized benchmarks is as follows:
GPQA: 0.87
HLE: 0.283
SciCode: 0.425
IFBench: 0.688
LCR: 0.607
TerminalBench Hard: 0.409
TAU2: 0.950
In contrast, Claude Sonnet 5 currently has no public benchmark rows available, making direct quantitative comparison against MiMo-V2-Pro impossible at this time.
Cost and Speed
Cost efficiency is a significant differentiator between these two models:
Claude Sonnet 5: Priced at $3.00/1M input and $15.00/1M output, with a blended rate of $6.00/1M. It delivers an output speed of 69.618 tok/s with a time to first token of 2.069s.
MiMo-V2-Pro: Priced at $1.00/1M input and $3.00/1M output, with a blended rate of $1.50/1M. It delivers an output speed of 53.303 tok/s with a faster time to first token of 1.574s.
While Sonnet 5 is faster in raw output speed, MiMo-V2-Pro is significantly more affordable and offers a quicker initial response time.
Best Fit
MiMo-V2-Pro is best suited for developers and researchers who rely on benchmark validation and cost-sensitive scaling. Claude Sonnet 5 is best suited for users already embedded in the Anthropic ecosystem who require adaptive reasoning for medium-effort tasks.
FAQ
Is MiMo-V2-Pro better than Claude Sonnet 5 Adaptive Reasoning?
Not across the board: MiMo-V2-Pro is 75% cheaper on blended price; Claude Sonnet 5 Adaptive Reasoning streams output 1.3 times as fast; and MiMo-V2-Pro reaches its first token sooner.
Who makes Claude Sonnet 5 Adaptive Reasoning and MiMo-V2-Pro?
Claude Sonnet 5 Adaptive Reasoning is made by Anthropic and MiMo-V2-Pro by Xiaomi. Claude Sonnet 5 Adaptive Reasoning was released on June 30, 2026 and MiMo-V2-Pro on March 18, 2026.
Which is cheaper, Claude Sonnet 5 Adaptive Reasoning or MiMo-V2-Pro?
MiMo-V2-Pro is cheaper on a blended basis. Claude Sonnet 5 Adaptive Reasoning lists $3.00 per million input tokens and $15.00 per million output tokens; MiMo-V2-Pro lists $1.00 and $3.00. For 1 million input and 200,000 output tokens that is $6.00 against $1.60.
When were Claude Sonnet 5 Adaptive Reasoning and MiMo-V2-Pro released?
Claude Sonnet 5 Adaptive Reasoning is newer. It was released on June 30, 2026, about 3 months after MiMo-V2-Pro (March 18, 2026).
Does Claude Sonnet 5 Adaptive Reasoning respond faster than MiMo-V2-Pro?
Claude Sonnet 5 Adaptive Reasoning generates output faster, at 70 tokens per second against 53 tokens per second. MiMo-V2-Pro reaches its first token sooner (1.6 seconds against 2.1 seconds). Counting the first-token wait, MiMo-V2-Pro finishes short replies first and Claude Sonnet 5 Adaptive Reasoning pulls ahead beyond about 100 tokens.
Final whistle
Choose MiMo-V2-Pro if you require a cost-effective model with verified performance metrics across scientific and coding benchmarks. It is ideal for developers needing predictable speed and data-backed results. Opt for Claude Sonnet 5 if your workflow is already integrated with Anthropic’s specialized tools, such as Claude Science, or if you require the specific adaptive reasoning capabilities offered by their latest 2026 architecture.
Where the numbers come from
The scores, speed and prices in this comparison come from independent third-party model evaluations that Franklin AI syncs each day, and the article was written from a snapshot of them. For the latest results, open the Claude Sonnet 5 (Adaptive Reasoning, Medium Effort) and MiMo-V2-Pro pages. The AI Benchmark methodology explains how that data is collected and shown.

Comments (0)
to join the discussion
No comments yet
Be the first to share your thoughts!