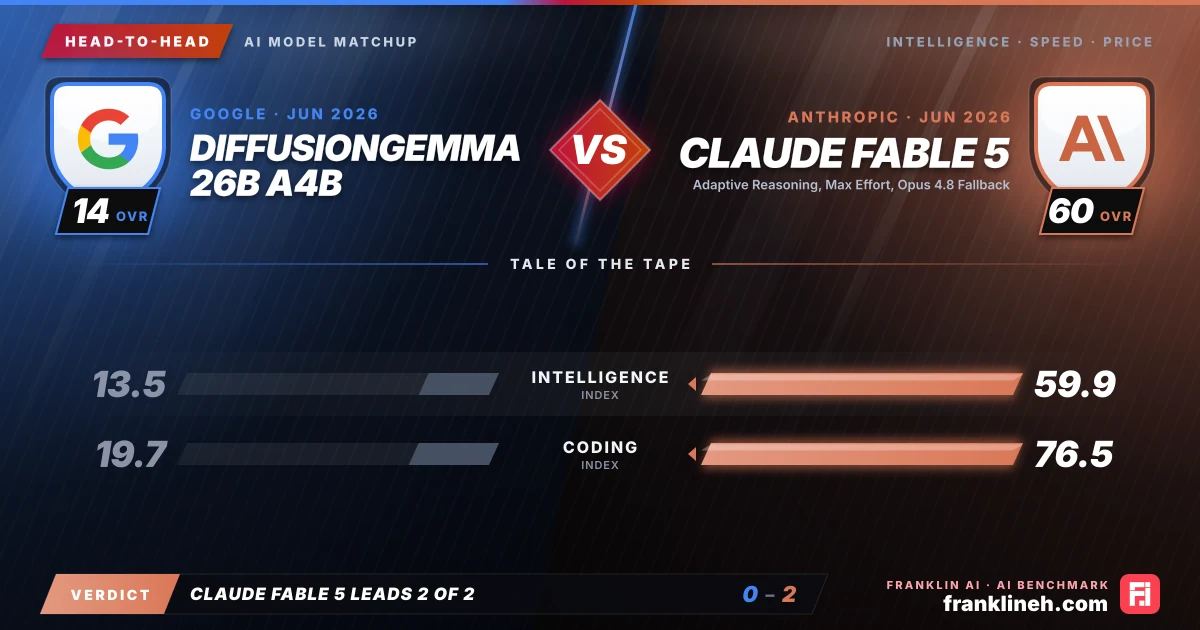
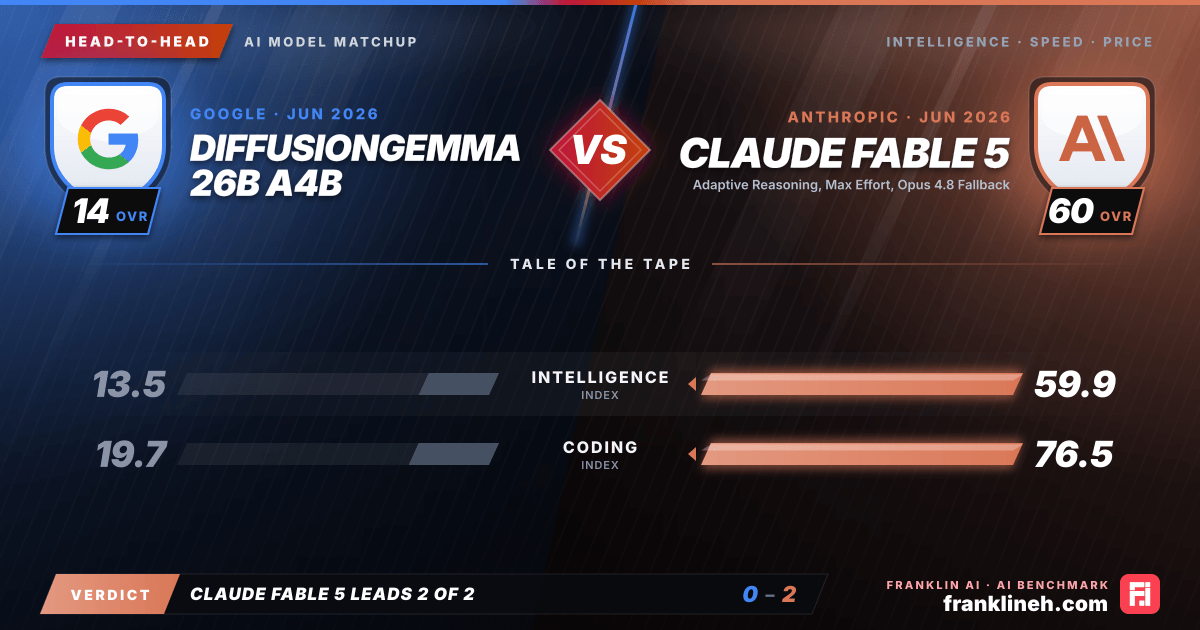
Head-to-head AI model comparison graphic: DiffusionGemma 26B A4B (Google) vs Claude Fable 5 (Anthropic). Intelligence index 13.5 vs 59.9; coding index 19.7 vs 76.5. franklineh.com
DiffusionGemma 26B A4B vs Claude Fable 5: head-to-head AI benchmark comparison. Claude Fable 5 leads on intelligence index and coding index.
Head to headUpdated

DiffusionGemma 26B A4B vs Claude Fable 5

Claude Fable 5 significantly outperforms DiffusionGemma 26B A4B across all intelligence and coding metrics, though it comes with a premium price tag compared to the free-to-use Google model.

Pick it for DiffusionGemma 26B A4B

  • Zero-cost project requirements
  • General-purpose light tasks
  • Budget-constrained development

Pick it for Claude Fable 5 · Adaptive Reasoning, Max Effort, Opus 4.8 Fallback

  • Complex coding and debugging
  • High-stakes reasoning tasks
  • Enterprise-grade applications

By the numbers

These figures describe the two model configurations shown here. A dash means the source snapshot had no usable figure for that metric. Scores, speed and API pricing may change as providers update models.

MetricDiffusionGemma 26B A4BClaude Fable 5 (Adaptive Reasoning, Max Effort, Opus 4.8 Fallback)
Intelligence Index13.559.9
Coding Index19.776.5
Input price (per 1M tokens)–$10.00
Output price (per 1M tokens)–$50.00
Release date2026-06-102026-06-09

Quick Take

Released just one day apart in June 2026, these two models represent vastly different approaches to AI deployment. Google’s DiffusionGemma 26B A4B offers a zero-cost entry point, while Anthropic’s Claude Fable 5 positions itself as a high-performance, premium-tier engine designed for intensive reasoning and complex coding tasks.

Benchmark Read

Claude Fable 5 demonstrates a substantial lead in technical capability. With an Intelligence index of 59.9 and a Coding index of 76.5, it significantly outpaces DiffusionGemma 26B A4B, which holds indices of 13.5 and 19.7, respectively.

Performance across specific benchmarks confirms this gap:

  • GPQA: 0.926 (Fable 5) vs 0.669 (Gemma)
  • HLE: 0.533 (Fable 5) vs 0.102 (Gemma)
  • SciCode: 0.602 (Fable 5) vs 0.343 (Gemma)
  • IFBench: 0.635 (Fable 5) vs 0.595 (Gemma)
  • LCR: 0.700 (Fable 5) vs 0.143 (Gemma)

Additionally, Claude Fable 5 shows strong results in specialized testing, achieving 0.629 on TerminalBench Hard and 0.985 on TAU2. Math index data remains unknown for both models.

Cost and Speed

DiffusionGemma 26B A4B is entirely free, with input and output costs listed at $0.00 per million tokens. Conversely, Claude Fable 5 utilizes a premium pricing structure: $10.00/1M for input and $50.00/1M for output, resulting in a blended cost of $20.00/1M. Neither model has publicly disclosed output speed or time-to-first-token metrics.

Best Fit

Claude Fable 5 is best suited for enterprise-grade applications, complex software development, and research environments where accuracy and reasoning depth are paramount. DiffusionGemma 26B A4B is ideal for developers, hobbyists, or budget-constrained projects that require a functional model without the overhead of usage fees.

Common questions about Claude Fable 5 Adaptive Reasoning and DiffusionGemma 26B A4B

Is DiffusionGemma 26B A4B better than Claude Fable 5 Adaptive Reasoning?

Claude Fable 5 Adaptive Reasoning comes out ahead on every measure the data separates: Claude Fable 5 Adaptive Reasoning scores higher on the intelligence index, 59.9 to 13.5.

When were Claude Fable 5 Adaptive Reasoning and DiffusionGemma 26B A4B released?

DiffusionGemma 26B A4B is newer. It was released on June 10, 2026, one day after Claude Fable 5 Adaptive Reasoning (June 9, 2026).

Are Claude Fable 5 Adaptive Reasoning and DiffusionGemma 26B A4B from the same company?

Claude Fable 5 Adaptive Reasoning is made by Anthropic and DiffusionGemma 26B A4B by Google. Claude Fable 5 Adaptive Reasoning was released on June 9, 2026 and DiffusionGemma 26B A4B on June 10, 2026.

Is Claude Fable 5 Adaptive Reasoning or DiffusionGemma 26B A4B better at coding?

Claude Fable 5 Adaptive Reasoning has the higher coding index, 76.5 against 19.7.

Final whistle

For users prioritizing raw reasoning power, coding proficiency, and complex task execution, Claude Fable 5 is the clear choice despite the cost. DiffusionGemma 26B A4B is a viable, cost-effective alternative for users who require a zero-cost solution and have less demanding requirements regarding model intelligence and benchmark performance.

Where the numbers come from

The scores, speed and prices in this comparison come from independent third-party model evaluations that Franklin AI syncs each day, and the article was written from a snapshot of them. For the latest results, open the DiffusionGemma 26B A4B and Claude Fable 5 (Adaptive Reasoning, Max Effort, Opus 4.8 Fallback) pages. The AI Benchmark methodology explains how that data is collected and shown.

Comments (0)

No comments yet

Be the first to share your thoughts!