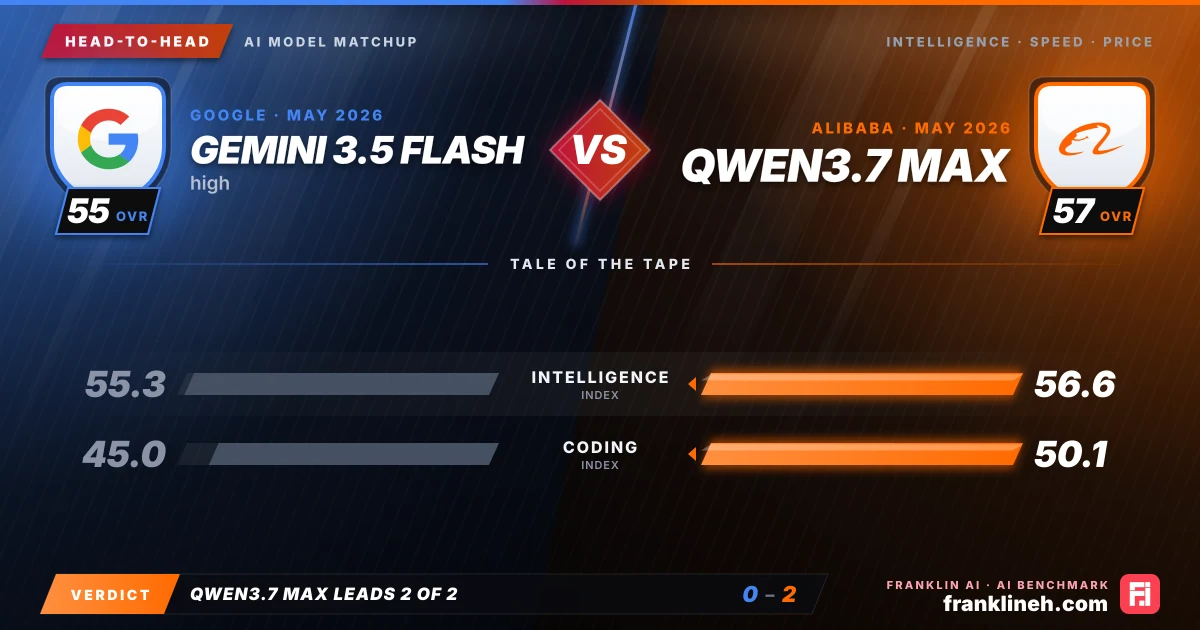
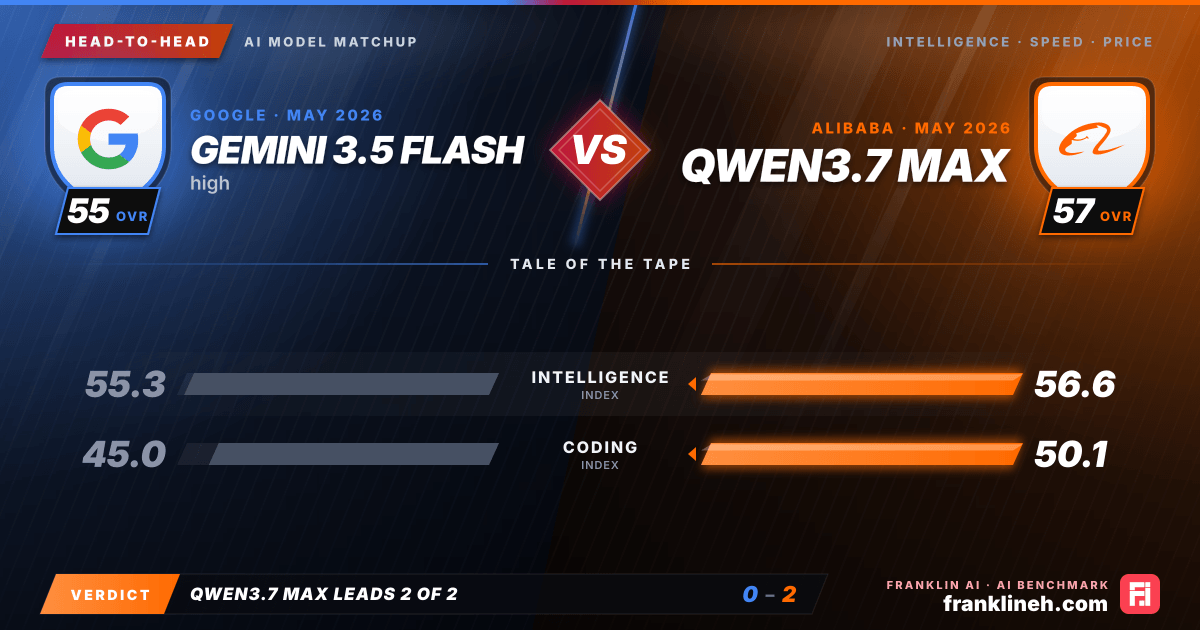
Head-to-head AI model comparison graphic: Gemini 3.5 Flash (Google) vs Qwen3.7 Max (Alibaba). Intelligence index 55.3 vs 56.6; coding index 45.0 vs 50.1. franklineh.com
Gemini 3.5 Flash vs Qwen3.7 Max: head-to-head AI benchmark comparison. Qwen3.7 Max leads on intelligence index and coding index.
Head to headUpdated

Gemini 3.5 Flash (high) vs Qwen3.7 Max

Released on May 19, 2026, these models represent the latest in AI innovation. While Gemini 3.5 Flash (high) offers transparent performance metrics and speed, Qwen3.7 Max leads in intelligence and coding benchmarks with a unique zero-cost pricing model.

Pick it for Gemini 3.5 Flash · High

  • High-speed production workflows
  • Applications requiring verified latency
  • Integration with Google's agentic ecosystem

Pick it for Qwen3.7 Max

  • Cost-sensitive coding projects
  • Tasks requiring maximum intelligence
  • Complex logic and terminal operations

By the numbers

These figures describe the two model configurations shown here. A dash means the source snapshot had no usable figure for that metric. Scores, speed and API pricing may change as providers update models.

MetricGemini 3.5 Flash (high)Qwen3.7 Max
Intelligence Index55.356.6
Coding Index45.050.1
Input price (per 1M tokens)$1.50–
Output price (per 1M tokens)$9.00–
Output speed (tokens/s)233–
Time to first token9.7s–
Release date2026-05-192026-05-19

Quick Take

Gemini 3.5 Flash (high) and Qwen3.7 Max both launched on May 19, 2026, marking a competitive day for AI development. Gemini 3.5 Flash (high) focuses on high-speed, measurable performance, while Qwen3.7 Max positions itself as a high-intelligence, cost-free alternative for developers.

Benchmark Read

Qwen3.7 Max holds a slight edge in the overall Intelligence index (56.6 vs 55.3) and a notable lead in the Coding index (50.1 vs 45). In specific benchmarks, Qwen3.7 Max outperforms Gemini in IFBench (0.805 vs 0.763) and TerminalBench Hard (0.507 vs 0.409). Conversely, Gemini 3.5 Flash (high) shows superior performance in HLE (0.41 vs 0.381), SciCode (0.531 vs 0.488), and TAU2 (0.953 vs 0.947). Both models show near-identical results in GPQA and LCR.

Cost and Speed

Gemini 3.5 Flash (high) features a clear pricing structure: $1.50/1M input and $9.00/1M output, resulting in a $3.38/1M blended rate. It also provides specific performance data, including an output speed of 233.027 tokens per second and a time to first token of 9.746 seconds. In contrast, Qwen3.7 Max is currently listed with no pricing (input/output/blended at $0.00/1M), though its specific output speed and latency metrics remain unknown.

Best Fit

Gemini 3.5 Flash (high) is best suited for production environments where latency and throughput are critical, as its performance metrics are fully documented. Qwen3.7 Max is an ideal candidate for developers looking for high-intelligence coding assistance without the financial burden of token-based pricing, provided they can accommodate the lack of published speed metrics.

Frequently asked questions

Is Gemini 3.5 Flash high better than Qwen3.7 Max?

Qwen3.7 Max leads on every measure the catalogue separates: Qwen3.7 Max scores higher on the intelligence index, 56.6 to 55.3.

Who makes Gemini 3.5 Flash high and Qwen3.7 Max?

Gemini 3.5 Flash high is made by Google and Qwen3.7 Max by Alibaba. Gemini 3.5 Flash high was released on May 19, 2026 and Qwen3.7 Max on May 19, 2026.

Which is better for coding, Gemini 3.5 Flash high or Qwen3.7 Max?

Qwen3.7 Max has the higher coding index, 50.1 against 45.0.

Final whistle

Choose Qwen3.7 Max if your priority is maximum coding capability and intelligence at zero cost. However, if your workflow requires predictable latency and verified output speeds, Gemini 3.5 Flash (high) is the superior choice. Gemini provides a transparent performance profile, whereas Qwen3.7 Max offers high-tier benchmark results without the overhead of input or output fees.

Where the numbers come from

The scores, speed and prices in this comparison come from independent third-party model evaluations that Franklin AI syncs each day, and the article was written from a snapshot of them. For the latest results, open the Gemini 3.5 Flash (high) and Qwen3.7 Max pages. The AI Benchmark methodology explains how that data is collected and shown.

Comments (0)

No comments yet

Be the first to share your thoughts!