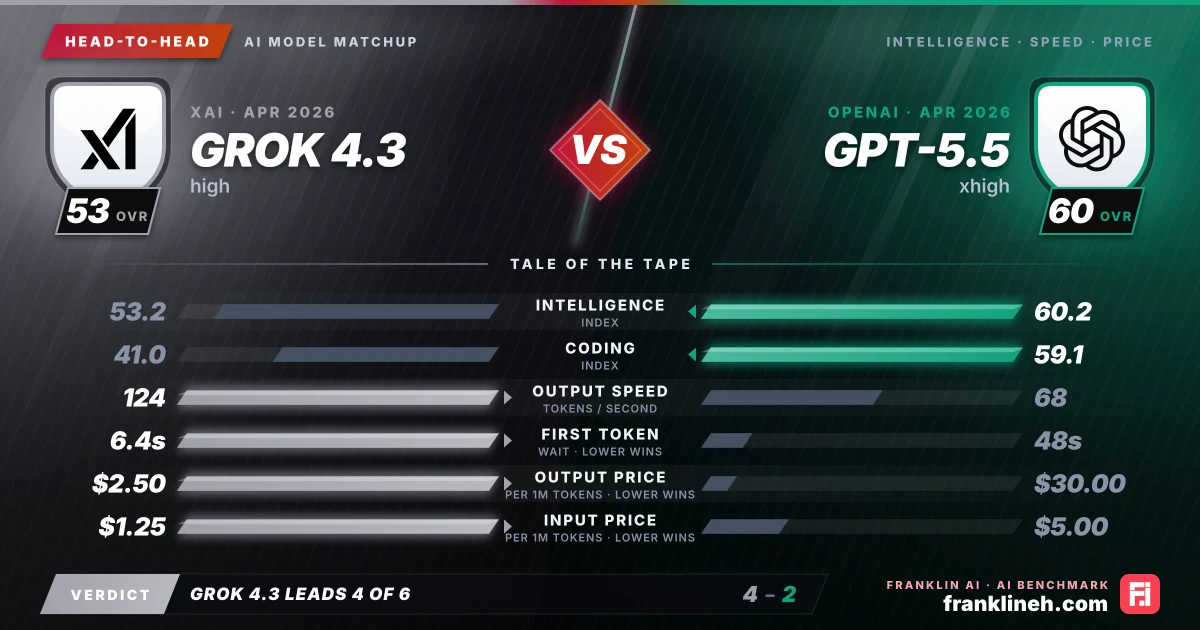
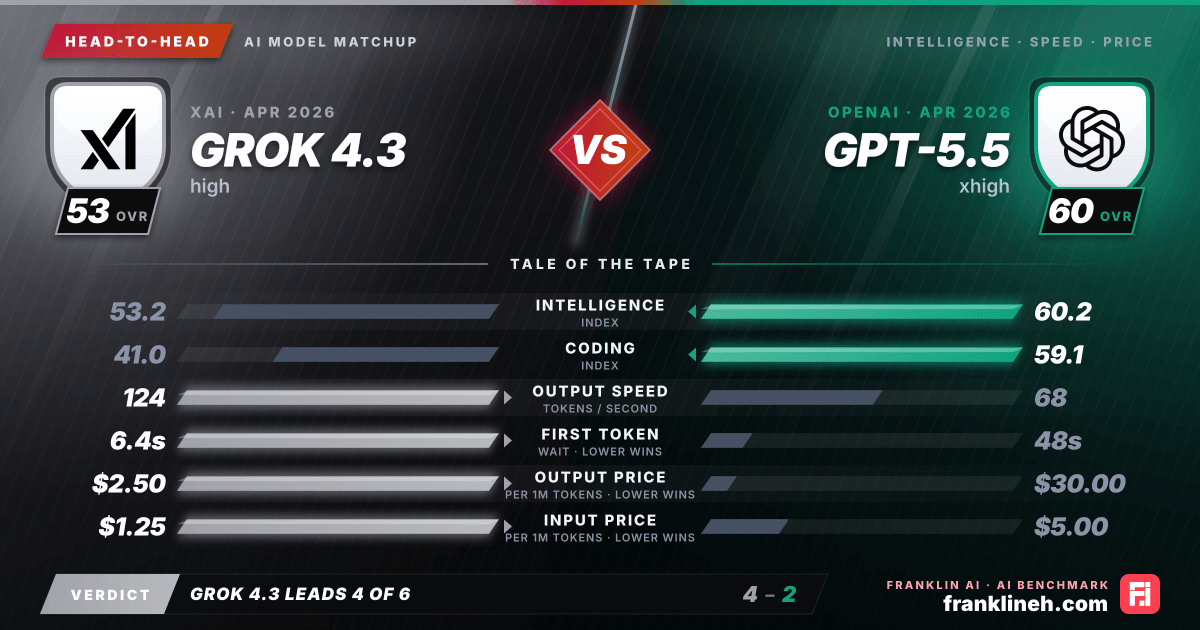
Head-to-head AI model comparison graphic: Grok 4.3 (xAI) vs GPT-5.5 (OpenAI). Intelligence index 53.2 vs 60.2; coding index 41.0 vs 59.1; output speed 124 vs 68 tokens per second; time to first token 6.4s vs 48s; output price $2.50 vs $30.00 per million tokens; input price $1.25 vs $5.00 per million tokens. franklineh.com
Grok 4.3 vs GPT-5.5: head-to-head AI benchmark comparison. Grok 4.3 leads on output speed, time to first token, output price and input price; GPT-5.5 leads on intelligence index and coding index.
Head to headUpdated

Grok 4.3 vs. GPT-5.5: Evaluating Performance and Efficiency

This comparison evaluates xAI’s Grok 4.3 and OpenAI’s GPT-5.5, analyzing their respective intelligence, coding capabilities, speed, and cost structures to help users determine the optimal model for their specific technical and operational requirements.

Pick it for Grok 4.3 · High

  • Latency-sensitive chat, support, and interactive product flows
  • Longer responses where sustained output speed matters
  • Higher-volume workloads where blended token cost matters

Pick it for GPT-5.5 · Xhigh

  • Workloads that benefit from the stronger overall intelligence score
  • Coding and agentic tasks where the benchmark edge matters
  • Teams already standardized on OpenAI

By the numbers

These figures describe the two model configurations shown here. A dash means the source snapshot had no usable figure for that metric. Scores, speed and API pricing may change as providers update models.

MetricGrok 4.3 (high)GPT-5.5 (xhigh)
Intelligence Index53.260.2
Coding Index41.059.1
Input price (per 1M tokens)$1.25$5.00
Output price (per 1M tokens)$2.50$30.00
Output speed (tokens/s)12468
Time to first token6.4s48s
Release date2026-04-302026-04-23

What the benchmarks show

When comparing the intelligence and technical proficiency of these two models, GPT-5.5 (xhigh) consistently outperforms Grok 4.3 (high) across most standardized metrics. GPT-5.5 holds an Intelligence Index of 60.2 compared to Grok 4.3’s 53.2, and it demonstrates a more significant lead in coding proficiency with a score of 59.1 against Grok’s 41. This trend continues in specialized benchmarks; GPT-5.5 achieves higher scores in GPQA (0.935 vs. 0.901), HLE (0.443 vs. 0.35), SciCode (0.561 vs. 0.473), LCR (0.743 vs. 0.643), and TerminalBench Hard (0.606 vs. 0.379).

However, the performance gap is not universal. Grok 4.3 exhibits a stronger performance in instruction following, scoring 0.813 on IFBench compared to GPT-5.5’s 0.759. Furthermore, Grok 4.3 shows a slight edge in the TAU2 benchmark with a score of 0.977, compared to GPT-5.5’s 0.939. These results suggest that while GPT-5.5 is the more capable model for complex reasoning and software development, Grok 4.3 remains highly competitive in tasks requiring strict adherence to instructions and specific procedural execution.

Speed and cost

The operational profiles of these two models are starkly different, presenting a clear trade-off between performance and resource consumption. Grok 4.3 is optimized for speed, delivering an output rate of 123.966 tokens per second with a time-to-first-token of 6.374 seconds. In contrast, GPT-5.5 is significantly slower, producing 68.227 tokens per second and requiring 47.763 seconds to generate the first token. For real-time applications or interactive interfaces, the responsiveness of Grok 4.3 provides a distinct advantage.

Financial considerations further widen the gap. GPT-5.5 is priced at a blended rate of $11.25 per million tokens, with output costs reaching $30.00 per million. Grok 4.3 is substantially more economical, featuring a blended rate of $1.56 per million tokens and an output cost of $2.50 per million. The cost of utilizing GPT-5.5 is nearly seven times higher than that of Grok 4.3, which will be a decisive factor for teams managing high-volume data processing or large-scale automated workflows.

Which model fits which workflow

Selecting the appropriate model requires aligning these performance metrics with your specific workflow needs. GPT-5.5 is best suited for high-complexity tasks where the cost of error is high and the need for deep reasoning or advanced coding is constant. Its superior scores in coding and logic make it an ideal candidate for backend development, complex data analysis, and research-heavy applications where the latency penalty is acceptable in exchange for higher accuracy.

Grok 4.3 is better positioned for high-throughput environments where latency and budget are primary constraints. Its ability to follow instructions effectively, combined with its rapid response time and low cost, makes it a strong candidate for customer-facing chatbots, automated content generation, and high-frequency API interactions. While it may not match GPT-5.5 in raw intelligence, its efficiency allows for broader deployment across a larger volume of tasks without incurring prohibitive costs.

Frequently asked questions

Is GPT-5.5 xhigh better than Grok 4.3 high?

It depends on what you need: GPT-5.5 xhigh scores higher on the intelligence index, 60.2 to 53.2; Grok 4.3 high is 86% cheaper on blended price; and Grok 4.3 high streams output 1.8 times as fast.

Which is cheaper, GPT-5.5 xhigh or Grok 4.3 high?

Grok 4.3 high is cheaper on a blended basis. GPT-5.5 xhigh lists $5.00 per million input tokens and $30.00 per million output tokens; Grok 4.3 high lists $1.25 and $2.50. For 1 million input and 200,000 output tokens that is $11.00 against $1.75.

Which model has lower latency?

Grok 4.3 high generates output faster, at 124 tokens per second against 68 tokens per second. Grok 4.3 high reaches its first token sooner (6.4 seconds against 48 seconds).

Who makes GPT-5.5 xhigh and Grok 4.3 high?

GPT-5.5 xhigh is made by OpenAI and Grok 4.3 high by xAI. GPT-5.5 xhigh was released on April 23, 2026 and Grok 4.3 high on April 30, 2026.

Is GPT-5.5 xhigh or Grok 4.3 high better at coding?

GPT-5.5 xhigh has the higher coding index, 59.1 against 41.0.

Final whistle

The choice between these models depends on the priority of raw intelligence versus operational efficiency. GPT-5.5 offers superior reasoning and coding performance, making it the choice for complex, high-stakes tasks where accuracy is paramount. Conversely, Grok 4.3 provides a significantly more responsive and cost-effective solution for high-volume applications. While GPT-5.5 leads in most technical benchmarks, its higher latency and cost profile necessitate a strategic approach to integration based on your specific project constraints.

Where the numbers come from

The scores, speed and prices in this comparison come from independent third-party model evaluations that Franklin AI syncs each day, and the article was written from a snapshot of them. For the latest results, open the Grok 4.3 (high) and GPT-5.5 (xhigh) pages. The AI Benchmark methodology explains how that data is collected and shown.

Comments (0)

No comments yet

Be the first to share your thoughts!