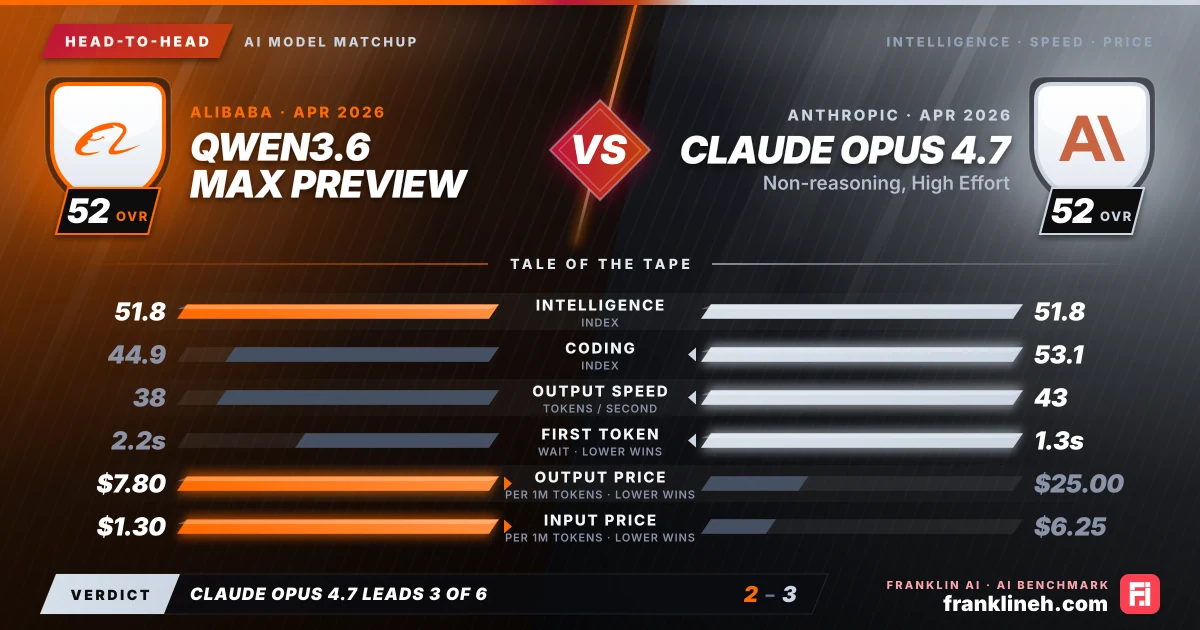
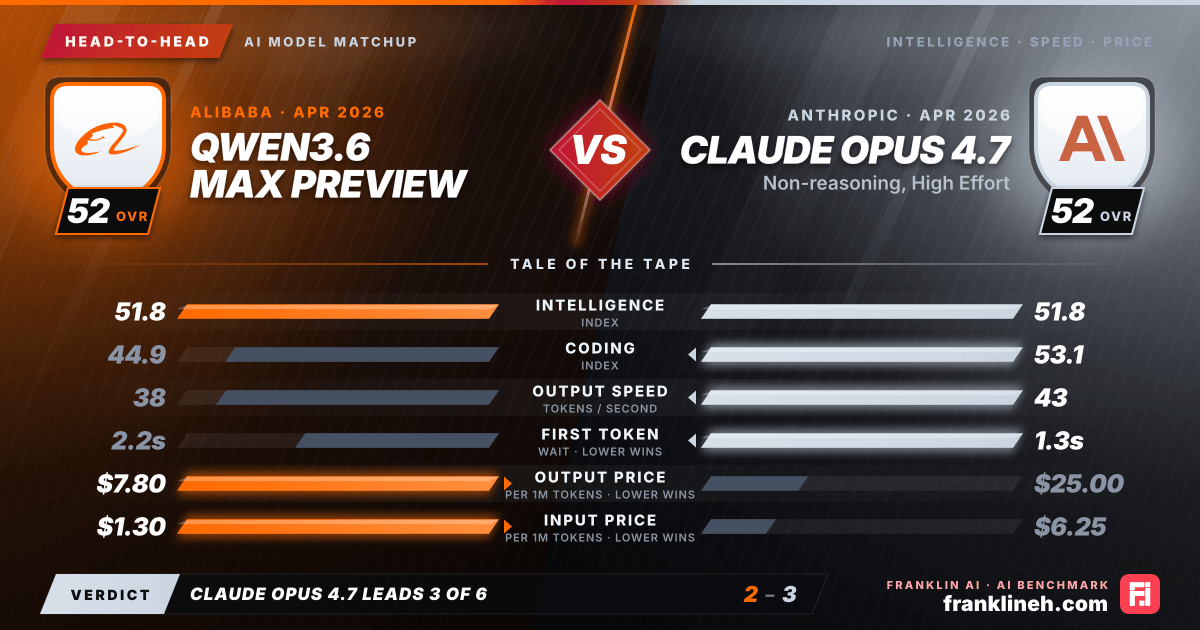
Head-to-head AI model comparison graphic: Qwen3.6 Max Preview (Alibaba) vs Claude Opus 4.7 (Anthropic). Intelligence index 51.8 vs 51.8; coding index 44.9 vs 53.1; output speed 38 vs 43 tokens per second; time to first token 2.2s vs 1.3s; output price $7.80 vs $25.00 per million tokens; input price $1.30 vs $6.25 per million tokens. franklineh.com
Qwen3.6 Max Preview vs Claude Opus 4.7: head-to-head AI benchmark comparison. Claude Opus 4.7 leads on coding index, output speed and time to first token; Qwen3.6 Max Preview leads on output price and input price; level on intelligence index.
Head to headUpdated

Qwen3.6 Max Preview vs. Claude Opus 4.7: A Comparative Analysis

This analysis compares the Qwen3.6 Max Preview and Claude Opus 4.7, evaluating their distinct performance profiles in coding, instruction following, and cost-efficiency to help users determine the optimal model for their specific technical requirements.

Pick it for Qwen3.6 Max Preview

  • Higher-volume workloads where blended token cost matters
  • Teams already standardized on Alibaba
  • Use cases where its strongest benchmark rows map to the workload

Pick it for Claude Opus 4.7 · Non-reasoning, High Effort

  • Coding and agentic tasks where the benchmark edge matters
  • Latency-sensitive chat, support, and interactive product flows
  • Longer responses where sustained output speed matters

By the numbers

These figures describe the two model configurations shown here. A dash means the source snapshot had no usable figure for that metric. Scores, speed and API pricing may change as providers update models.

MetricQwen3.6 Max PreviewClaude Opus 4.7 (Non-reasoning, High Effort)
Intelligence Index51.851.8
Coding Index44.953.1
Input price (per 1M tokens)$1.30$6.25
Output price (per 1M tokens)$7.80$25.00
Output speed (tokens/s)3843
Time to first token2.2s1.3s
Release date2026-04-202026-04-16

What the benchmarks show

When evaluating the Qwen3.6 Max Preview and Claude Opus 4.7, both models demonstrate identical overall intelligence scores of 51.8, yet they diverge significantly in specialized domains. Claude Opus 4.7 holds a clear advantage in coding-heavy tasks, boasting a coding index of 53.1 compared to Qwen’s 44.9. This is further evidenced by Claude’s superior performance on TerminalBench Hard (0.545 vs. 0.439) and SciCode (0.501 vs. 0.469), suggesting that Claude is better suited for complex software engineering and scientific reasoning tasks.

Conversely, Qwen3.6 Max Preview excels in instruction following and logical consistency. Its IFBench score of 0.766 significantly outperforms Claude’s 0.436, indicating that Qwen is more reliable when following strict formatting or multi-step prompt constraints. While both models perform similarly on the GPQA benchmark, Qwen shows a notable lead in the TAU2 benchmark (0.959 vs. 0.740), reinforcing its strength in tasks requiring structured, multi-turn logical reasoning.

Speed and cost

Cost-efficiency is a major differentiator between these two models. Qwen3.6 Max Preview is substantially more affordable, with a blended cost of $2.92 per million tokens, compared to Claude Opus 4.7’s $10.94 per million tokens. This represents a significant variance for high-volume users, as Qwen’s input and output pricing are both considerably lower than Anthropic’s offering.

In terms of latency, Claude Opus 4.7 provides a more responsive experience. It achieves a time to first token of 1.338 seconds and an output speed of 43.414 tokens per second. Qwen3.6 Max Preview is slightly slower, with a time to first token of 2.154 seconds and an output speed of 37.954 tokens per second. For applications where real-time interaction is critical, Claude’s faster throughput may justify its higher price point.

Which model fits which workflow

Selecting the right model requires balancing the need for coding precision against the need for instruction adherence and budget constraints. Claude Opus 4.7 is the preferred choice for developers working in complex coding environments or those who require rapid, high-speed responses for interactive applications. Its higher coding index and superior performance on terminal-based benchmarks make it a robust tool for technical workflows where precision in syntax and logic is paramount.

Qwen3.6 Max Preview is best positioned for workflows that prioritize strict adherence to complex instructions and cost-effectiveness. Because it excels in the IFBench and TAU2 benchmarks, it is an ideal candidate for automated data processing, content generation with rigid formatting requirements, or any task where the model must strictly follow a series of constraints without deviation. The lower cost per million tokens makes it a sustainable choice for large-scale deployments where budget optimization is a primary concern.

Decision takeaway

Ultimately, neither model is objectively superior across all metrics. The decision should be driven by the specific demands of your project. If your workflow is defined by heavy coding and a need for low-latency responses, the performance premium of Claude Opus 4.7 is likely worth the investment. However, if your requirements lean toward complex instruction following and you are sensitive to operational costs, Qwen3.6 Max Preview provides a highly capable and economical alternative.

FAQ

Is Claude Opus 4.7 Non-reasoning better than Qwen3.6 Max Preview?

Neither wins everywhere: they are level on the intelligence index (51.8 and 51.8); Qwen3.6 Max Preview is 73% cheaper on blended price; and Claude Opus 4.7 Non-reasoning streams output 1.1 times as fast.

Which is faster, Claude Opus 4.7 Non-reasoning or Qwen3.6 Max Preview?

Claude Opus 4.7 Non-reasoning generates output faster, at 43 tokens per second against 38 tokens per second. Claude Opus 4.7 Non-reasoning reaches its first token sooner (1.3 seconds against 2.2 seconds).

When were Claude Opus 4.7 Non-reasoning and Qwen3.6 Max Preview released?

Qwen3.6 Max Preview is newer. It was released on April 20, 2026, 4 days after Claude Opus 4.7 Non-reasoning (April 16, 2026).

Is Claude Opus 4.7 Non-reasoning or Qwen3.6 Max Preview better at coding?

Claude Opus 4.7 Non-reasoning has the higher coding index, 53.1 against 44.9.

Which is cheaper, Claude Opus 4.7 Non-reasoning or Qwen3.6 Max Preview?

Qwen3.6 Max Preview is cheaper on a blended basis. Claude Opus 4.7 Non-reasoning lists $6.25 per million input tokens and $25.00 per million output tokens; Qwen3.6 Max Preview lists $1.30 and $7.80. For 1 million input and 200,000 output tokens that is $11.25 against $2.86.

Final whistle

The choice between these models depends on your priority: Qwen3.6 Max Preview offers superior instruction following and cost-efficiency for budget-conscious workflows, while Claude Opus 4.7 provides a significant edge in raw coding capability and faster response times. If your tasks involve complex terminal operations or heavy coding, Claude is the more performant choice; for general-purpose instruction adherence at a lower price point, Qwen is the more practical investment.

Where the numbers come from

The scores, speed and prices in this comparison come from independent third-party model evaluations that Franklin AI syncs each day, and the article was written from a snapshot of them. For the latest results, open the Qwen3.6 Max Preview and Claude Opus 4.7 (Non-reasoning, High Effort) pages. The AI Benchmark methodology explains how that data is collected and shown.

Comments (0)

No comments yet

Be the first to share your thoughts!