
Understanding the Model Landscape
Anthropic’s recent model releases have introduced two distinct approaches to high-level reasoning: Claude Fable 5 and Claude Opus 5. While both models utilize adaptive reasoning and max-effort configurations, they serve different roles within the developer ecosystem. Claude Opus 5 is the company’s flagship model, featuring a clear release date of July 24, 2026, and a comprehensive set of performance data. In contrast, Claude Fable 5 functions as a specialized variant, often associated with specific reasoning traces, though it lacks the public benchmark data and release history that define the Opus line.
What the Benchmarks Show
Performance data is currently limited to Claude Opus 5, which provides a concrete baseline for Anthropic’s current capabilities. Opus 5 records an intelligence index of 63.1 and a coding index of 78. Its performance across standardized evaluations is robust, with a GPQA score of 0.932, an HLE score of 0.549, and a SciCode score of 0.557. These figures suggest a model highly optimized for complex, multi-step problem solving and software engineering tasks.
Claude Fable 5 does not currently have publicly available benchmark rows. This lack of data makes it difficult to quantitatively compare its raw reasoning power against Opus 5. However, the emergence of community-developed models utilizing Fable 5 traces suggests that its value may lie in its specific reasoning architecture rather than raw benchmark dominance. Users should view Fable 5 as a specialized tool for experimental workflows, whereas Opus 5 is the proven, metrics-backed workhorse.
Speed and Cost Considerations
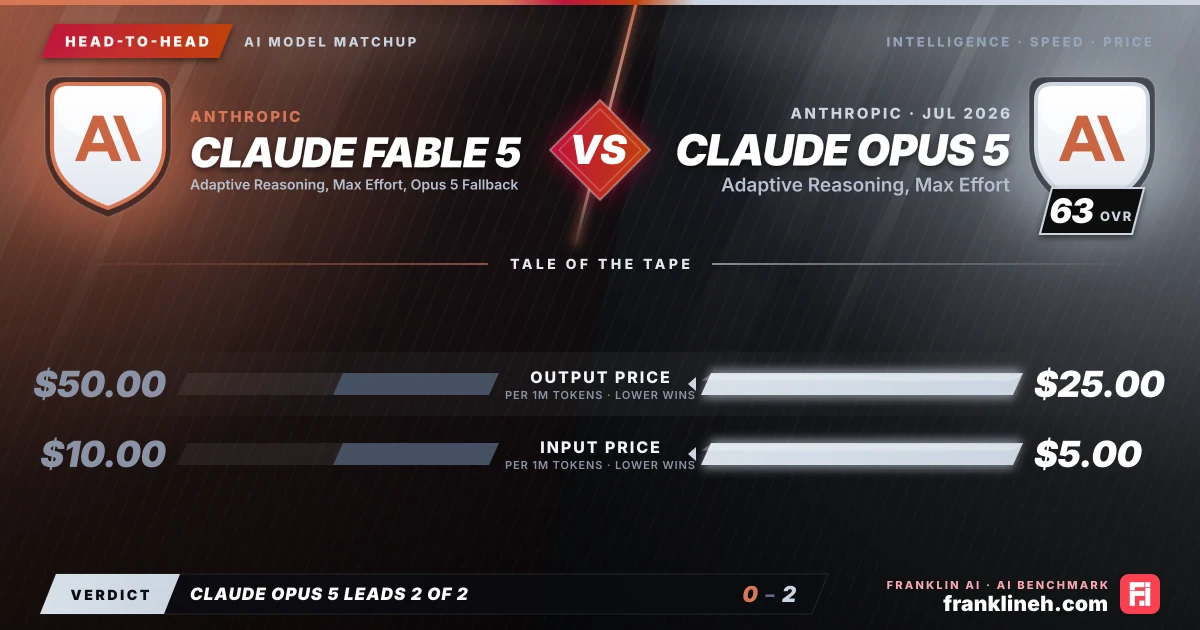
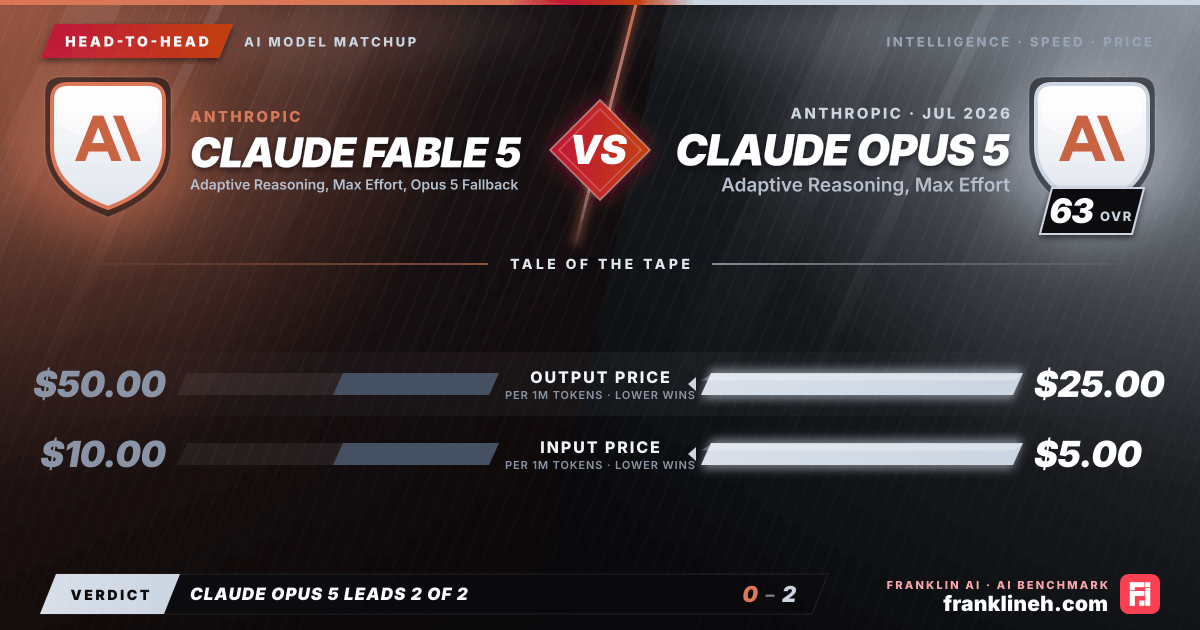
There is a significant disparity in the cost and operational transparency between the two models. Claude Opus 5 is priced at $5.00 per 1M input tokens and $25.00 per 1M output tokens, resulting in a blended cost of $10.00 per 1M tokens. It also offers predictable performance, with an output speed of 51.797 tokens per second and a time-to-first-token of 31.474 seconds.
Claude Fable 5 carries a higher price point, with input costs at $10.00 per 1M tokens and output costs at $50.00 per 1M tokens, doubling the blended cost to $20.00 per 1M tokens. Furthermore, critical performance metrics such as output speed and latency remain unknown for Fable 5. For teams operating under strict budget constraints or requiring predictable latency for user-facing applications, the higher cost and unknown performance profile of Fable 5 present a significant barrier to entry compared to the well-documented Opus 5.
Which Model Fits Which Workflow
Choosing between these models depends on your tolerance for operational uncertainty. Claude Opus 5 is designed for production environments where cost-efficiency and performance consistency are paramount. Its established benchmarks make it suitable for enterprise-grade coding and complex analytical tasks.
Claude Fable 5 is better suited for specialized research or development scenarios. Because it includes an Opus 5 fallback mechanism, it may be useful for workflows that require an adaptive reasoning layer that can revert to a more stable model if the primary reasoning path fails. While it is more expensive and less transparent, it provides a unique architectural option for developers building custom reasoning agents who need to leverage specific Fable 5 traces.
Comments (0)
to join the discussion
No comments yet
Be the first to share your thoughts!