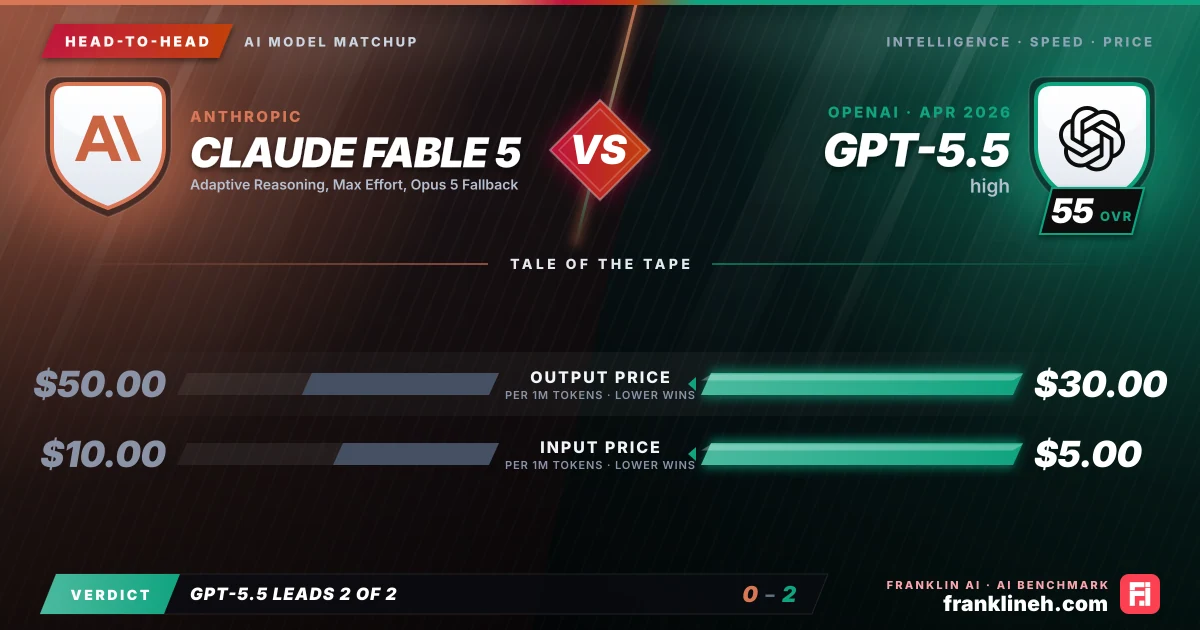
Head-to-head AI model comparison graphic: Claude Fable 5 (Anthropic) vs GPT-5.5 (OpenAI). Output price $50.00 vs $30.00 per million tokens; input price $10.00 vs $5.00 per million tokens. franklineh.com
Claude Fable 5 vs GPT-5.5: head-to-head AI benchmark comparison. GPT-5.5 leads on output price and input price.
Head to headUpdated

Claude Fable 5 vs. GPT-5.5: Comparative Analysis

This analysis compares the operational profiles of Anthropic’s Claude Fable 5 and OpenAI’s GPT-5.5. While GPT-5.5 offers a transparent performance baseline and cost-efficient pricing, Claude Fable 5 positions itself as a specialized reasoning engine, leaving users to weigh established metrics against proprietary adaptive capabilities.

Pick it for Claude Fable 5 · Adaptive Reasoning, Max Effort, Opus 5 Fallback

  • Teams already standardized on Anthropic
  • Use cases where its strongest benchmark rows map to the workload
  • Readers who want the best fit after checking the full table

Pick it for GPT-5.5 · High

  • Workloads that benefit from the stronger overall intelligence score
  • Coding and agentic tasks where the benchmark edge matters
  • Higher-volume workloads where blended token cost matters

By the numbers

These figures describe the two model configurations shown here. A dash means the source snapshot had no usable figure for that metric. Scores, speed and API pricing may change as providers update models.

MetricClaude Fable 5 (Adaptive Reasoning, Max Effort, Opus 5 Fallback)GPT-5.5 (high)
Intelligence Index–54.7
Coding Index–71.6
Input price (per 1M tokens)$10.00$5.00
Output price (per 1M tokens)$50.00$30.00
Release date–2026-04-23

Understanding the Benchmark Landscape

Evaluating these two models requires navigating a significant disparity in available data. OpenAI’s GPT-5.5 provides a comprehensive performance profile, boasting an intelligence index of 54.7 and a coding index of 71.6. Its benchmark performance is well-documented, with a GPQA score of 0.932, a SciCode score of 0.559, and an IFBench score of 0.716. These figures suggest a model highly optimized for complex, multi-step reasoning and technical execution.

In contrast, Claude Fable 5 operates with limited public benchmark data. While it lacks the raw index scores found in the GPT-5.5 documentation, its architecture is built around Adaptive Reasoning, Max Effort, and Opus 5 fallback capabilities. The utility of Claude Fable 5 is currently defined by its integration into specialized local thinking models, suggesting that its value lies in its reasoning trace quality rather than standardized test performance. Users must decide if they prefer the empirical reliability of GPT-5.5 or the specialized, adaptive logic inherent in the Fable 5 framework.

Speed and Cost Efficiency

Cost is a primary differentiator between these two frontier models. GPT-5.5 is positioned as the more economical choice for high-volume operations, with an input cost of $5.00 per million tokens and an output cost of $30.00 per million tokens, resulting in a blended cost of $11.25. This pricing structure makes it a viable candidate for enterprise-scale applications where token consumption is a significant factor in the bottom line.

Claude Fable 5 carries a higher price point, with input costs at $10.00 per million tokens and output costs reaching $50.00 per million tokens, totaling a blended cost of $20.00 per million tokens. While speed metrics for both models remain unknown, the cost difference suggests that Claude Fable 5 is intended for high-value, complex tasks where the cost-per-token is secondary to the quality of the reasoning output. Organizations must weigh the premium pricing of Fable 5 against the potential efficiency gains of GPT-5.5’s lower cost structure.

Aligning Models with Workflow Requirements

Choosing between these models depends heavily on the nature of the task. GPT-5.5 is a robust, general-purpose powerhouse. Its high coding index and strong performance across benchmarks like TerminalBench Hard (0.598) and TAU2 (0.929) make it an ideal candidate for software development, data analysis, and complex instruction following. It is a predictable, high-performing asset for teams that rely on consistent, measurable AI output.

Claude Fable 5, by contrast, is designed for nuanced reasoning. Its reliance on 'Max Effort' and 'Adaptive Reasoning' suggests it is better suited for tasks that require deep, iterative thought processes rather than rapid, standardized execution. Because it is already being utilized by the developer community for local thinking models, it is likely the superior choice for researchers or developers building custom reasoning agents who need access to the model's underlying trace logic, even if it comes at a higher operational cost.

Quick answers

Is GPT-5.5 high better than Claude Fable 5 Adaptive Reasoning?

GPT-5.5 high leads on every measure the catalogue separates: GPT-5.5 high is 44% cheaper on blended price.

Which is better for coding, Claude Fable 5 Adaptive Reasoning or GPT-5.5 high?

The catalogue has no coding index for Claude Fable 5 Adaptive Reasoning yet, so there is no direct coding comparison. A trial on your own code is the best guide.

Is GPT-5.5 high cheaper than Claude Fable 5 Adaptive Reasoning?

GPT-5.5 high is cheaper on a blended basis. Claude Fable 5 Adaptive Reasoning lists $10.00 per million input tokens and $50.00 per million output tokens; GPT-5.5 high lists $5.00 and $30.00. For 1 million input and 200,000 output tokens that is $20.00 against $11.00.

Are Claude Fable 5 Adaptive Reasoning and GPT-5.5 high from the same company?

Claude Fable 5 Adaptive Reasoning is made by Anthropic and GPT-5.5 high by OpenAI.

Final whistle

For users requiring verifiable performance data, GPT-5.5 is the clear choice, offering high coding proficiency and transparent pricing. Conversely, Claude Fable 5 is suited for developers prioritizing specialized reasoning and adaptive logic. If your workflow demands rigorous benchmark validation, OpenAI’s model provides the necessary empirical evidence, whereas Anthropic’s offering is best reserved for experimental or reasoning-heavy tasks where benchmark scores are secondary to the model's adaptive architecture.

Where the numbers come from

The scores, speed and prices in this comparison come from independent third-party model evaluations that Franklin AI syncs each day, and the article was written from a snapshot of them. For the latest results, open the Claude Fable 5 (Adaptive Reasoning, Max Effort, Opus 5 Fallback) and GPT-5.5 (high) pages. The AI Benchmark methodology explains how that data is collected and shown.

Comments (0)

No comments yet

Be the first to share your thoughts!