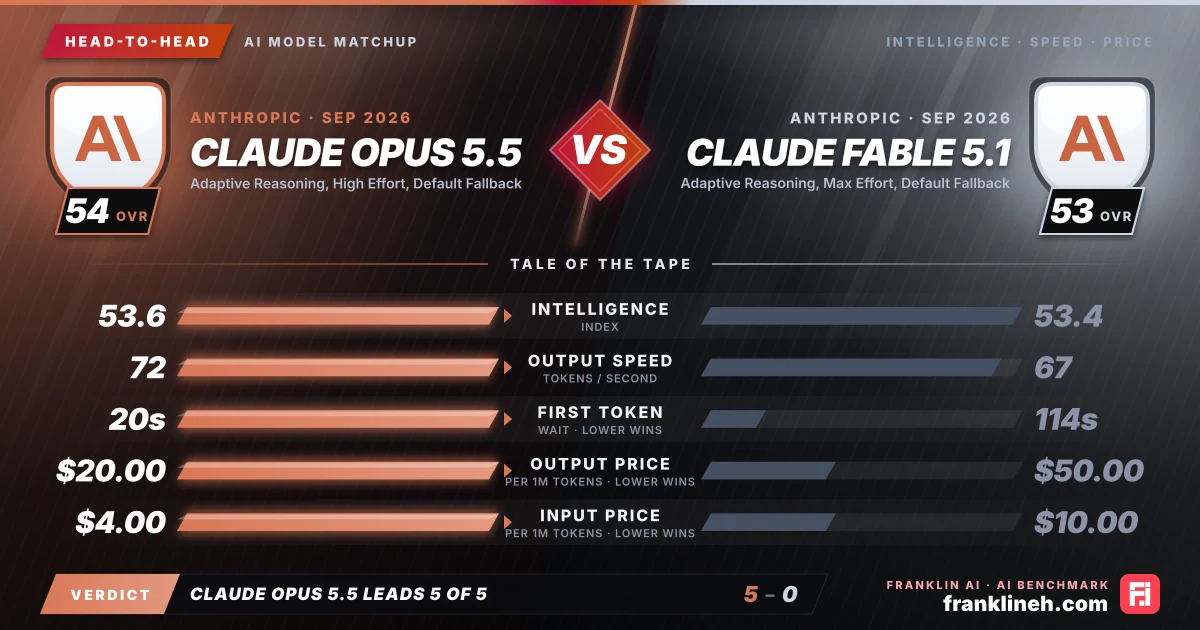
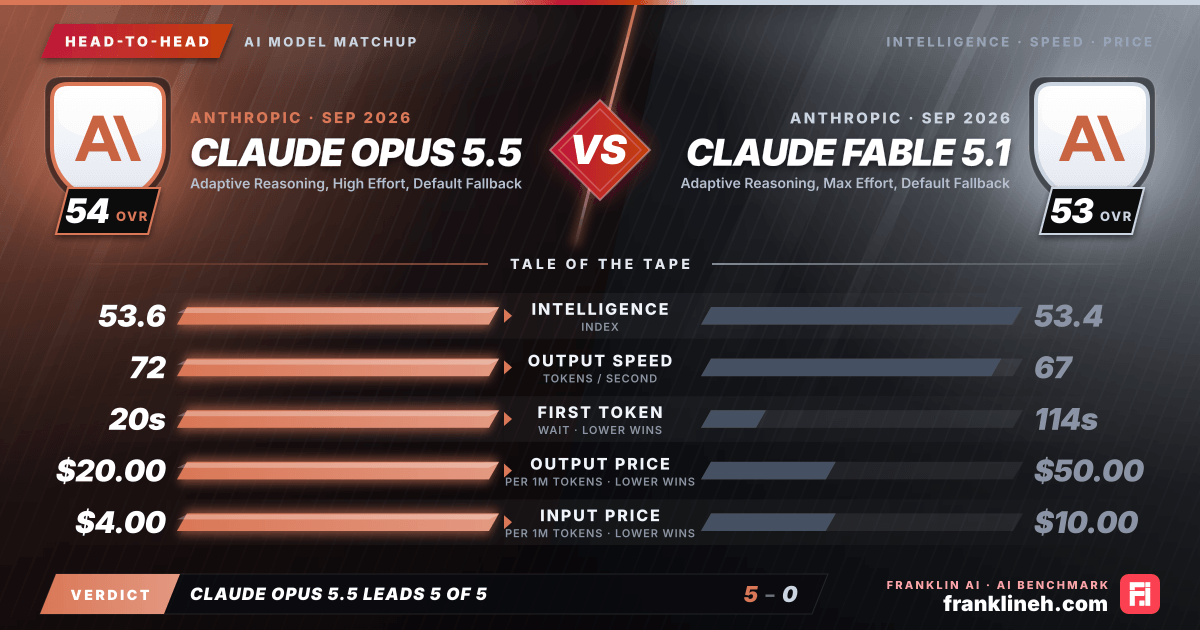
Head-to-head AI model comparison graphic: Claude Opus 5.5 (Anthropic) vs Claude Fable 5.1 (Anthropic). Intelligence index 53.6 vs 53.4; output speed 72 vs 67 tokens per second; time to first token 20s vs 114s; output price $20.00 vs $50.00 per million tokens; input price $4.00 vs $10.00 per million tokens. franklineh.com
Claude Opus 5.5 vs Claude Fable 5.1: head-to-head AI benchmark comparison. Claude Opus 5.5 leads on intelligence index, output speed, time to first token, output price and input price.
Head to headUpdated

Claude Opus 5.5 vs. Claude Fable 5.1: A Comparative Analysis

This analysis compares Anthropic’s Claude Opus 5.5 and Claude Fable 5.1, evaluating their performance, cost-efficiency, and benchmark capabilities to help users determine which model best suits their specific operational requirements.

Pick it for Claude Opus 5.5 · Adaptive Reasoning, High Effort, Default Fallback

  • Workloads that benefit from the stronger overall intelligence score
  • Latency-sensitive chat, support, and interactive product flows
  • Longer responses where sustained output speed matters

Pick it for Claude Fable 5.1 · Adaptive Reasoning, Max Effort, Default Fallback

  • Coding and agentic tasks where the benchmark edge matters
  • Teams already standardized on Anthropic
  • Use cases where its strongest benchmark rows map to the workload

By the numbers

These figures describe the two model configurations shown here. A dash means the source snapshot had no usable figure for that metric. Scores, speed and API pricing may change as providers update models.

MetricClaude Opus 5.5 (Adaptive Reasoning, High Effort, Default Fallback)Claude Fable 5.1 (Adaptive Reasoning, Max Effort, Default Fallback)
Intelligence Index53.653.4
Coding Index–81.6
Input price (per 1M tokens)$4.00$10.00
Output price (per 1M tokens)$20.00$50.00
Output speed (tokens/s)7267
Time to first token20s114s
Release date2026-09-172026-09-01

Understanding the Benchmark Landscape

When evaluating Claude Opus 5.5 and Claude Fable 5.1, the benchmark data reveals a nuanced trade-off between raw capability and model efficiency. Claude Fable 5.1 consistently outperforms Opus 5.5 across key metrics, including the HLE (0.591 vs 0.556), SciCode (0.631 vs 0.604), and LCR (0.853 vs 0.827) benchmarks. Furthermore, Fable 5.1 demonstrates a strong coding index of 81.6. While Opus 5.5 holds a slightly higher general intelligence index of 53.6 compared to Fable’s 53.4, the performance gap in specialized tasks suggests that Fable 5.1 is engineered for more intensive, high-effort reasoning requirements.

Speed and Cost Trade-offs

Operational efficiency is where the two models diverge most sharply. Claude Opus 5.5 is significantly more accessible from a latency perspective, boasting an output speed of 71.738 tokens per second and a time-to-first-token of 20.027 seconds. In contrast, Claude Fable 5.1 is notably slower, with an output speed of 66.762 tokens per second and a substantial time-to-first-token of 113.57 seconds. This latency difference makes Opus 5.5 better suited for interactive applications where responsiveness is critical.

Pricing further differentiates the two. Claude Opus 5.5 operates at a blended cost of $8.00 per million tokens, whereas Claude Fable 5.1 is priced at $20.00 per million tokens. Users must decide if the performance gains provided by Fable 5.1 justify a cost that is 2.5 times higher than that of Opus 5.5.

Aligning Models with Workflows

Selecting the right model requires an assessment of your specific workflow demands. Claude Fable 5.1 is optimized for 'Max Effort' scenarios. Its higher benchmark scores in coding and scientific reasoning suggest it is the superior tool for complex problem-solving, research-heavy tasks, or technical development where the cost of an error outweighs the cost of the compute. It is designed for depth rather than speed.

Claude Opus 5.5, utilizing 'Adaptive Reasoning' with a focus on 'High Effort' and 'Default Fallback,' is built for versatility and throughput. It serves as a more balanced option for general-purpose AI tasks, internal tooling, or high-volume content generation where the model needs to remain responsive without incurring the premium costs associated with Fable 5.1. Its faster time-to-first-token ensures that user-facing applications remain fluid, preventing the bottlenecks that might occur with the more intensive Fable model.

Decision Takeaway

Ultimately, the decision rests on the priority of your project. If your primary constraint is technical accuracy in complex coding or scientific domains, the performance metrics favor Claude Fable 5.1. However, for organizations prioritizing cost-effectiveness and rapid interaction, Claude Opus 5.5 provides a highly capable alternative that maintains strong performance indices while significantly reducing both financial and temporal overhead.

FAQ

Is Claude Opus 5.5 Adaptive Reasoning better than Claude Fable 5.1 Adaptive Reasoning?

Claude Opus 5.5 Adaptive Reasoning comes out ahead on every measure the data separates: they are level on the intelligence index (53.4 and 53.6); Claude Opus 5.5 Adaptive Reasoning is 60% cheaper on blended price; and Claude Opus 5.5 Adaptive Reasoning reaches its first token sooner.

Which is faster, Claude Fable 5.1 Adaptive Reasoning or Claude Opus 5.5 Adaptive Reasoning?

Their output speeds are close: 67 tokens per second for Claude Fable 5.1 Adaptive Reasoning and 72 tokens per second for Claude Opus 5.5 Adaptive Reasoning. Claude Opus 5.5 Adaptive Reasoning reaches its first token sooner (20 seconds against 114 seconds).

Which is cheaper, Claude Fable 5.1 Adaptive Reasoning or Claude Opus 5.5 Adaptive Reasoning?

Claude Opus 5.5 Adaptive Reasoning is cheaper on a blended basis. Claude Fable 5.1 Adaptive Reasoning lists $10.00 per million input tokens and $50.00 per million output tokens; Claude Opus 5.5 Adaptive Reasoning lists $4.00 and $20.00. For 1 million input and 200,000 output tokens that is $20.00 against $8.00.

Which is better for coding, Claude Fable 5.1 Adaptive Reasoning or Claude Opus 5.5 Adaptive Reasoning?

The catalogue has no coding index for Claude Opus 5.5 Adaptive Reasoning yet, so there is no direct coding comparison. The closest signal is the overall intelligence index, 53.4 for Claude Fable 5.1 Adaptive Reasoning and 53.6 for Claude Opus 5.5 Adaptive Reasoning.

Who makes Claude Fable 5.1 Adaptive Reasoning and Claude Opus 5.5 Adaptive Reasoning?

Both are Anthropic models, listed as separate models in the catalogue. Claude Fable 5.1 Adaptive Reasoning was released on September 1, 2026 and Claude Opus 5.5 Adaptive Reasoning on September 17, 2026.

Final whistle

The choice between these models depends on your tolerance for latency and budget. Claude Fable 5.1 offers superior reasoning and coding performance, making it the choice for complex, high-stakes tasks where accuracy is paramount. Conversely, Claude Opus 5.5 is the more pragmatic choice for high-volume workflows, offering significantly faster response times and a lower cost structure, provided the slight dip in benchmark performance is acceptable for your specific use case.

Where the numbers come from

The scores, speed and prices in this comparison come from independent third-party model evaluations that Franklin AI syncs each day, and the article was written from a snapshot of them. For the latest results, open the Claude Opus 5.5 (Adaptive Reasoning, High Effort, Default Fallback) and Claude Fable 5.1 (Adaptive Reasoning, Max Effort, Default Fallback) pages. The AI Benchmark methodology explains how that data is collected and shown.

Comments (0)

No comments yet

Be the first to share your thoughts!