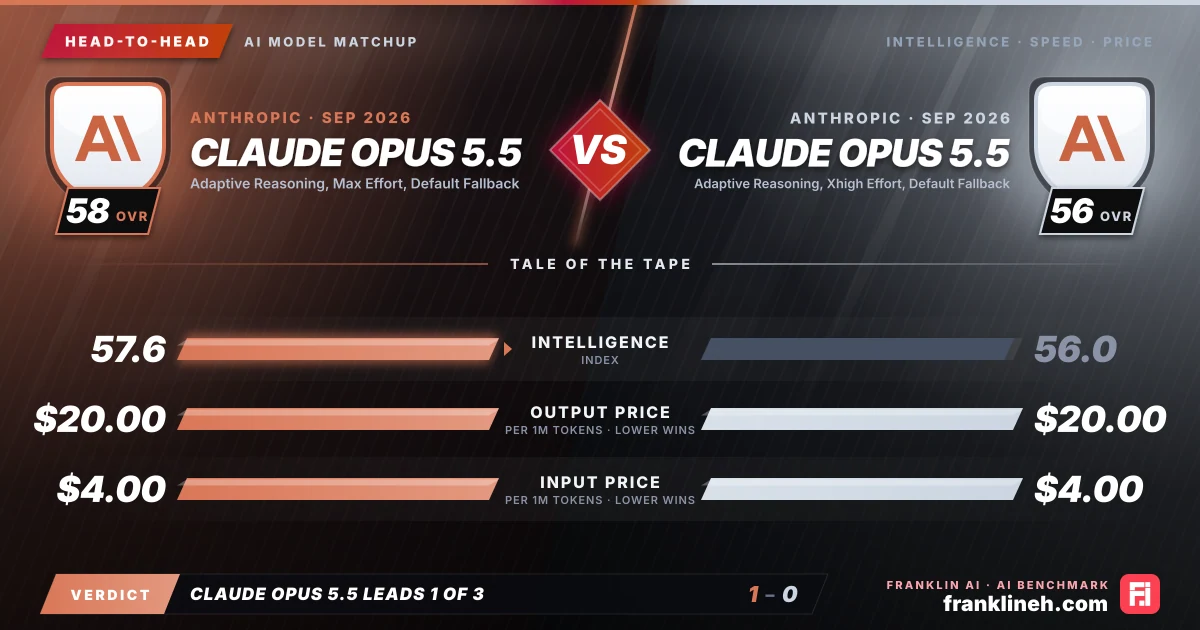
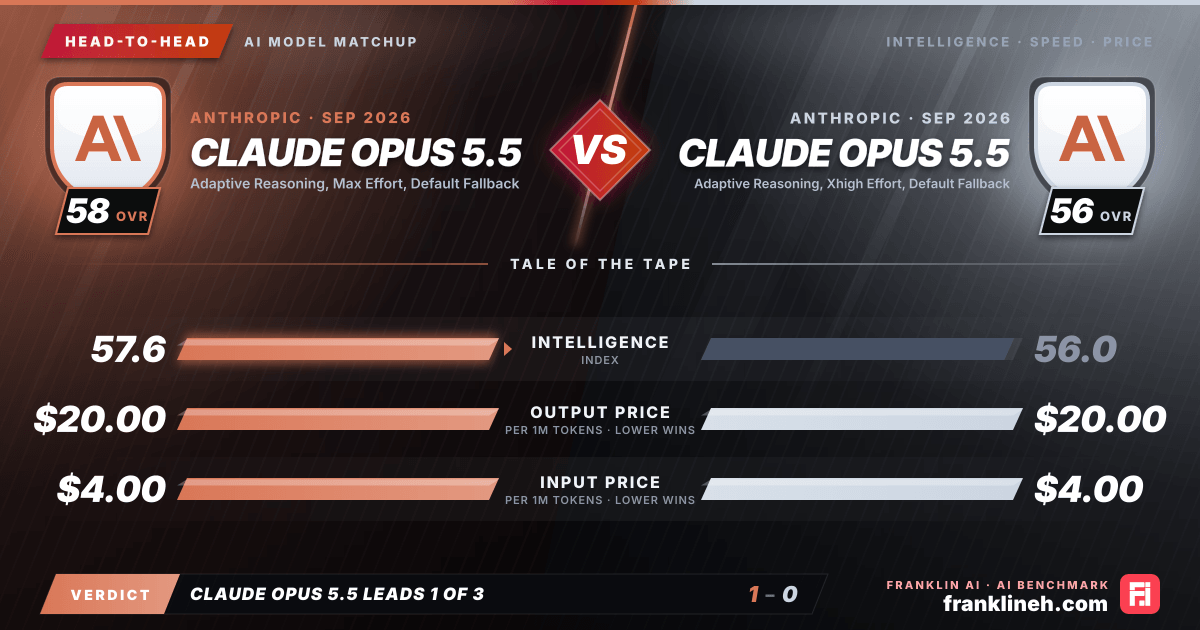
Head-to-head AI model comparison graphic: Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) (Anthropic) vs Claude Opus 5.5 (Adaptive Reasoning, Xhigh Effort, Default Fallback) (Anthropic). Intelligence index 57.6 vs 56.0; output price $20.00 vs $20.00 per million tokens; input price $4.00 vs $4.00 per million tokens. franklineh.com
Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) vs Claude Opus 5.5 (Adaptive Reasoning, Xhigh Effort, Default Fallback): head-to-head AI benchmark comparison. Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) leads on intelligence index; level on output price and input price.
Head to headUpdated

Comparing Claude Opus 5.5: Max Effort vs. Xhigh Effort

This comparison evaluates the performance and efficiency trade-offs between two configurations of Anthropic’s Claude Opus 5.5. By analyzing benchmark data and operational metrics, we determine which iteration of this model best serves specific computational needs.

Pick it for Claude Opus 5.5 · Max Effort

  • Workloads that benefit from the stronger overall intelligence score
  • Latency-sensitive chat, support, and interactive product flows
  • Teams already standardized on Anthropic

Pick it for Claude Opus 5.5 · Xhigh Effort

  • Longer responses where sustained output speed matters
  • Teams already standardized on Anthropic
  • Use cases where its strongest benchmark rows map to the workload

By the numbers

These figures describe the two model configurations shown here. A dash means the source snapshot had no usable figure for that metric. Scores, speed and API pricing may change as providers update models.

MetricClaude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback)Claude Opus 5.5 (Adaptive Reasoning, Xhigh Effort, Default Fallback)
Intelligence Index57.656.0
Input price (per 1M tokens)$4.00$4.00
Output price (per 1M tokens)$20.00$20.00
Output speed (tokens/s)–85
Time to first token–64s
Release date2026-09-222026-09-17

Understanding the Benchmark Landscape

The Claude Opus 5.5 series introduces two distinct operational configurations: Max Effort and Xhigh Effort. When evaluating these models through the lens of the HLE, SciCode, and LCR benchmarks, clear performance variations emerge. The Max Effort configuration achieves an intelligence index of 57.6, outperforming the Xhigh Effort configuration’s index of 56. This trend continues in the HLE benchmark, where Max Effort scores 0.614 compared to 0.575, and in the SciCode benchmark, where it scores 0.669 against 0.65. Interestingly, both configurations perform identically on the LCR benchmark, yielding a score of approximately 0.847. These results suggest that the Max Effort configuration is tuned for more complex reasoning tasks, whereas the Xhigh Effort configuration offers a slightly more streamlined approach.

Speed and Cost Considerations

From a financial perspective, the two models are indistinguishable. Both configurations are priced at $4.00 per million tokens for input and $20.00 per million tokens for output, resulting in a blended cost of $8.00 per million tokens. Because the cost structure is identical, the primary differentiator becomes performance efficiency. The Xhigh Effort configuration provides concrete operational data, boasting an output speed of 84.874 tokens per second and a time to first token of 63.684 seconds. Conversely, the Max Effort configuration currently lacks public data regarding output speed and time to first token. Users must weigh the benefit of the higher intelligence index in the Max Effort model against the known, measurable latency of the Xhigh Effort model.

Aligning Models with Workflows

Selecting the appropriate model requires an assessment of your specific project requirements. The Max Effort configuration is designed for high-stakes reasoning where the marginal gain in intelligence scores—as seen in the HLE and SciCode benchmarks—justifies the lack of transparent speed metrics. This makes it suitable for research-heavy tasks or complex problem-solving where accuracy is the primary constraint.

In contrast, the Xhigh Effort configuration is better suited for production environments where latency is a critical factor. Because this model provides defined output speeds, developers can better predict the performance of integrated applications. While it sacrifices a small percentage of intelligence capacity, the trade-off provides the reliability necessary for high-volume or time-sensitive workflows.

Decision Takeaway

Ultimately, the distinction between these two configurations is a matter of optimization. Anthropic has positioned these models to serve different stages of the development lifecycle. By utilizing the provided benchmark data, users can align their choice with the specific demands of their workload. Whether you prioritize the peak reasoning capabilities of the Max Effort configuration or the predictable, measurable performance of the Xhigh Effort configuration, both models represent the latest advancements in Anthropic’s flagship Opus 5.5 series.

Common questions about Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) and Claude Opus 5.5 (Adaptive Reasoning, Xhigh Effort, Default Fallback)

Is Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) better than Claude Opus 5.5 (Adaptive Reasoning, Xhigh Effort, Default Fallback)?

Where the data separates them, Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) is ahead each time: Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) scores higher on the intelligence index, 57.6 to 56.0; and their blended prices are about the same.

Who makes Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) and Claude Opus 5.5 (Adaptive Reasoning, Xhigh Effort, Default Fallback)?

Both are Anthropic models, listed as separate configurations of Claude Opus 5.5. Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) was released on September 22, 2026 and Claude Opus 5.5 (Adaptive Reasoning, Xhigh Effort, Default Fallback) on September 17, 2026.

Which is cheaper, Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) or Claude Opus 5.5 (Adaptive Reasoning, Xhigh Effort, Default Fallback)?

They cost about the same. Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) lists $4.00 in and $20.00 out per million tokens, and Claude Opus 5.5 (Adaptive Reasoning, Xhigh Effort, Default Fallback) lists $4.00 and $20.00.

Which is newer, Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) or Claude Opus 5.5 (Adaptive Reasoning, Xhigh Effort, Default Fallback)?

Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) is newer. It was released on September 22, 2026, 5 days after Claude Opus 5.5 (Adaptive Reasoning, Xhigh Effort, Default Fallback) (September 17, 2026).

Final whistle

The choice between these models depends on your tolerance for latency. If your workflow requires the highest possible intelligence scores, the Max Effort configuration is the clear choice. However, if your tasks are time-sensitive, the Xhigh Effort configuration provides a known output speed and predictable response times. Both models share identical pricing, meaning the decision rests entirely on whether you prioritize raw reasoning capability or operational throughput.

Where the numbers come from

The scores, speed and prices in this comparison come from independent third-party model evaluations that Franklin AI syncs each day, and the article was written from a snapshot of them. For the latest results, open the Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) and Claude Opus 5.5 (Adaptive Reasoning, Xhigh Effort, Default Fallback) pages. The AI Benchmark methodology explains how that data is collected and shown.

Comments (0)

No comments yet

Be the first to share your thoughts!