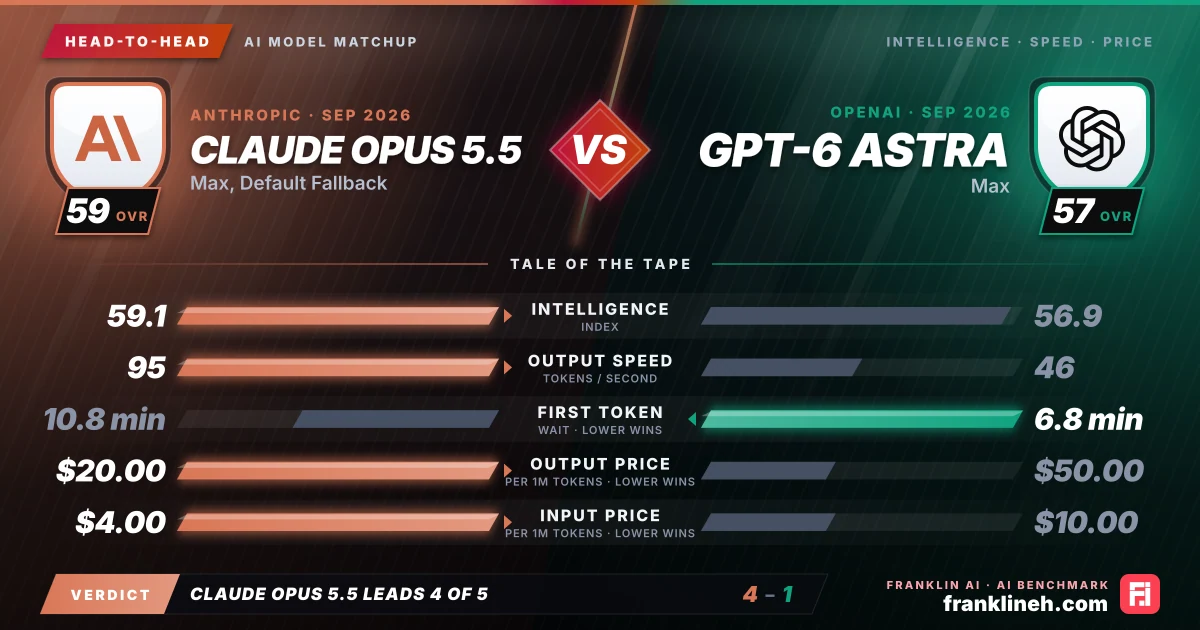
Claude Opus 5.5 vs GPT-6 Astra: head-to-head AI benchmark comparison. Claude Opus 5.5 leads on intelligence index, output speed, output price and input price; GPT-6 Astra leads on time to first token.
Claude Opus 5.5 (Max, Default Fallback) vs GPT-6 Astra (Max) benchmark comparison
Claude Opus 5.5 (Max, Default Fallback) vs GPT-6 Astra (Max) scores 59.1 and 56.9 on the captured intelligence index. Compare token prices and response timing.
Pick it for Claude Opus 5.5 · Max, Default Fallback
Test Opus on long completions at the lower listed rates.
Pick it for GPT-6 Astra · Max
Try Astra on requests where the first-token wait dominates.
By the numbers
These figures describe the two model configurations shown here. A dash means the source snapshot had no usable figure for that metric. Scores, speed and API pricing may change as providers update models.
Opus lists $4 and $20 per million input and output tokens against Astra’s $10 and $50. Opus emits output tokens faster in this capture. Astra starts responding earlier.
What to measure on your workload
A mixed workload can value these response characteristics differently. Include both a short exchange and a long document in the trial, then compare the result quality and the time until the complete answer.
Questions about Claude Opus 5.5 and GPT-6 Astra
How long does each variant take to start responding?
The captured time to first token is 645.03 seconds for Claude Opus 5.5 (Max, Default Fallback) and 304.07 seconds for GPT-6 Astra (Max).
What is the measured output speed?
Captured output throughput is 95.33 tokens per second for Claude Opus 5.5 (Max, Default Fallback) and 52.95 tokens per second for GPT-6 Astra (Max).
What release dates does the benchmark record list?
Claude Opus 5.5 has a recorded release date of 2026-09-22. GPT-6 Astra has a recorded release date of 2026-09-03.
Final whistle
Opus lists $4 and $20 per million input and output tokens against Astra’s $10 and $50. Opus emits output tokens faster in this capture. Astra starts responding earlier.
Where the numbers come from
The scores, speed and prices in this comparison come from independent third-party model evaluations that Franklin AI syncs each day, and the article was written from a snapshot of them. For the latest results, open the Claude Opus 5.5 (Max, Default Fallback) and GPT-6 Astra (Max) pages. The AI Benchmark methodology explains how that data is collected and shown.

Comments (0)
to join the discussion
No comments yet
Be the first to share your thoughts!