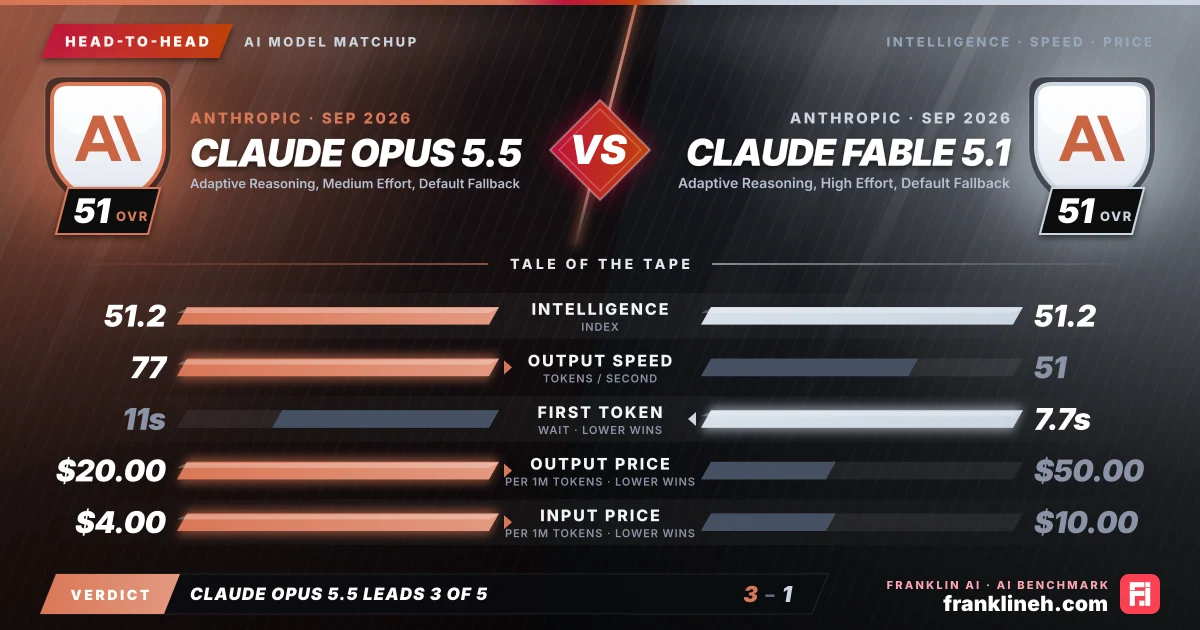
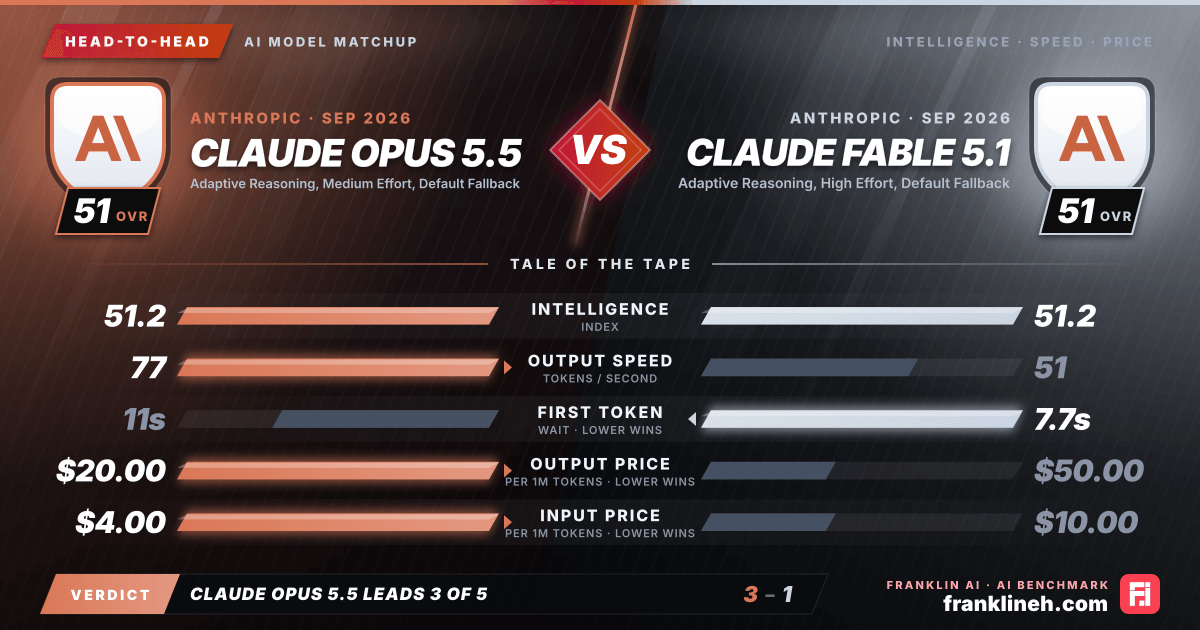
Head-to-head AI model comparison graphic: Claude Opus 5.5 (Anthropic) vs Claude Fable 5.1 (Anthropic). Intelligence index 51.2 vs 51.2; output speed 77 vs 51 tokens per second; time to first token 11s vs 7.7s; output price $20.00 vs $50.00 per million tokens; input price $4.00 vs $10.00 per million tokens. franklineh.com
Claude Opus 5.5 vs Claude Fable 5.1: head-to-head AI benchmark comparison. Claude Opus 5.5 leads on output speed, output price and input price; Claude Fable 5.1 leads on time to first token; level on intelligence index.
Head to headUpdated

Claude Opus 5.5 vs. Claude Fable 5.1: A Comparative Analysis

Anthropic’s latest models, Opus 5.5 and Fable 5.1, offer distinct trade-offs in reasoning, speed, and cost. While they share an identical intelligence index, their performance profiles cater to different operational needs, balancing high-effort complexity against resource efficiency.

Pick it for Claude Opus 5.5 · Adaptive Reasoning, Medium Effort, Default Fallback

  • Longer responses where sustained output speed matters
  • Higher-volume workloads where blended token cost matters
  • Teams already standardized on Anthropic

Pick it for Claude Fable 5.1 · Adaptive Reasoning, High Effort, Default Fallback

  • Coding and agentic tasks where the benchmark edge matters
  • Latency-sensitive chat, support, and interactive product flows
  • Teams already standardized on Anthropic

By the numbers

MetricClaude Opus 5.5 (Adaptive Reasoning, Medium Effort, Default Fallback)Claude Fable 5.1 (Adaptive Reasoning, High Effort, Default Fallback)
Intelligence Index51.251.2
Coding Index–79.1
Input price (per 1M tokens)$4.00$10.00
Output price (per 1M tokens)$20.00$50.00
Output speed (tokens/s)7751
Time to first token11s7.7s
Release date2026-09-172026-09-01

Understanding the Benchmark Landscape

Claude Opus 5.5 and Claude Fable 5.1 arrive as part of Anthropic’s recent push to refine adaptive reasoning capabilities. Both models share an identical intelligence index of 51.2, suggesting a baseline parity in general cognitive capacity. However, the benchmark data reveals nuanced differences in their specialized strengths. Claude Fable 5.1 demonstrates a slight edge in HLE (0.559) and a notable proficiency in coding, with a 79.1 coding index. In contrast, Opus 5.5 performs marginally better on SciCode (0.593) and LCR (0.843), indicating a potential advantage in scientific reasoning and logical consistency. While Fable 5.1 provides a high-effort approach to complex queries, Opus 5.5 serves as a more generalized, fallback-ready model that maintains competitive scores across the board without the same resource intensity.

Speed and Cost Trade-offs

The most immediate distinction between these two models lies in their economic and operational profiles. Claude Opus 5.5 is positioned as the more accessible option, with a blended pricing of $8.00 per 1M tokens, compared to the $20.00 per 1M tokens required for Fable 5.1. This pricing structure reflects the underlying architecture; Opus 5.5 is designed for medium-effort tasks, allowing it to achieve an output speed of 76.787 tokens per second. Fable 5.1, optimized for high-effort reasoning, operates at a more measured pace of 51.015 tokens per second.

Latency also plays a role in the user experience. Fable 5.1 offers a faster time to first token at 7.737 seconds, which may benefit interactive applications where immediate responsiveness is prioritized over sustained throughput. Opus 5.5, with a time to first token of 11.136 seconds, is slightly slower to initiate but compensates with a higher sustained output speed, making it better suited for batch processing or long-form content generation where overall completion time is the primary metric.

Aligning Models with Workflows

Selecting between these models requires an assessment of your specific workload requirements. Claude Fable 5.1 is engineered for scenarios where the depth of reasoning is the limiting factor. Its high-effort adaptive reasoning is well-suited for complex coding projects, intricate data analysis, and tasks where the GPQA score of 0.906 indicates a high degree of reliability in difficult, expert-level questions. It is a tool for precision, where the cost of the model is secondary to the quality and accuracy of the output.

Claude Opus 5.5, conversely, is built for scale. Its medium-effort design makes it an ideal candidate for high-volume applications, such as automated customer support, content summarization, or iterative development cycles where cost-per-token is a critical factor. By opting for Opus 5.5, users sacrifice the specialized high-effort reasoning of Fable 5.1 in exchange for a more sustainable operational budget and faster overall output speeds.

Decision Takeaway

Ultimately, the choice hinges on the nature of your tasks. If your operations involve heavy coding or highly complex, expert-level reasoning, the investment in Fable 5.1 is justified by its specialized indices. If your priority is maintaining a high-performance pipeline that remains cost-effective and efficient for general-purpose reasoning, Opus 5.5 provides a robust and reliable foundation.

Quick answers

Is Claude Opus 5.5 Adaptive Reasoning better than Claude Fable 5.1 Adaptive Reasoning?

Not across the board: they are level on the intelligence index (51.2 and 51.2); Claude Opus 5.5 Adaptive Reasoning is 60% cheaper on blended price; Claude Opus 5.5 Adaptive Reasoning streams output 1.5 times as fast; and Claude Fable 5.1 Adaptive Reasoning reaches its first token sooner.

Are Claude Fable 5.1 Adaptive Reasoning and Claude Opus 5.5 Adaptive Reasoning from the same company?

Both are Anthropic models, listed as separate models in the catalogue. Claude Fable 5.1 Adaptive Reasoning was released on September 1, 2026 and Claude Opus 5.5 Adaptive Reasoning on September 17, 2026.

Is Claude Fable 5.1 Adaptive Reasoning or Claude Opus 5.5 Adaptive Reasoning better at coding?

The catalogue has no coding index for Claude Opus 5.5 Adaptive Reasoning yet, so there is no direct coding comparison. The closest signal is the overall intelligence index, 51.2 for Claude Fable 5.1 Adaptive Reasoning and 51.2 for Claude Opus 5.5 Adaptive Reasoning.

When were Claude Fable 5.1 Adaptive Reasoning and Claude Opus 5.5 Adaptive Reasoning released?

Claude Opus 5.5 Adaptive Reasoning is newer. It was released on September 17, 2026, 16 days after Claude Fable 5.1 Adaptive Reasoning (September 1, 2026).

Which is faster, Claude Fable 5.1 Adaptive Reasoning or Claude Opus 5.5 Adaptive Reasoning?

Claude Opus 5.5 Adaptive Reasoning generates output faster, at 77 tokens per second against 51 tokens per second. Claude Fable 5.1 Adaptive Reasoning reaches its first token sooner (7.7 seconds against 11 seconds). Counting the first-token wait, Claude Fable 5.1 Adaptive Reasoning finishes short replies first and Claude Opus 5.5 Adaptive Reasoning pulls ahead beyond about 500 tokens.

Final whistle

Choose Claude Opus 5.5 if your workflow prioritizes cost-efficiency and high-throughput tasks, as it offers a significantly lower price point and faster output speeds. Conversely, select Claude Fable 5.1 for specialized, high-effort reasoning tasks where precision is paramount, despite the higher cost and slower token generation. Both models represent Anthropic’s latest advancements in adaptive reasoning, making the decision a matter of balancing your specific budget constraints against the need for deeper, high-effort analytical processing.

Where the numbers come from

The scores, speed and prices in this comparison come from independent third-party model evaluations that Franklin AI syncs each day, and the article was written from a snapshot of them. For the latest results, open the Claude Opus 5.5 (Adaptive Reasoning, Medium Effort, Default Fallback) and Claude Fable 5.1 (Adaptive Reasoning, High Effort, Default Fallback) pages. The AI Benchmark methodology explains how that data is collected and shown.

Comments (0)

No comments yet

Be the first to share your thoughts!