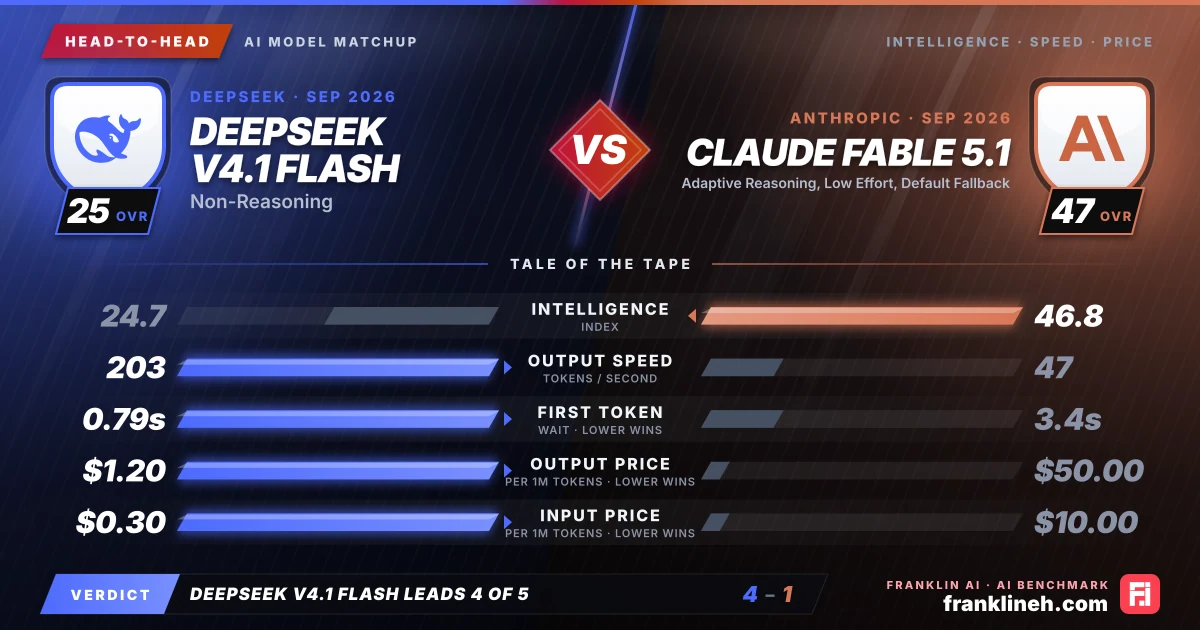
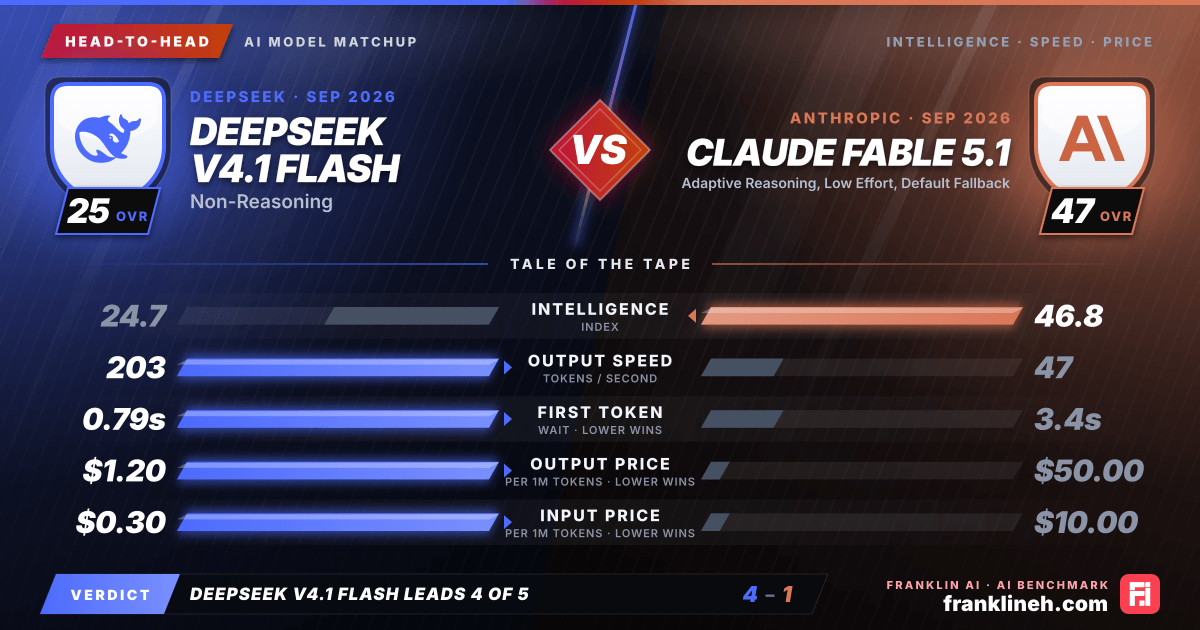
Head-to-head AI model comparison graphic: DeepSeek V4.1 Flash (DeepSeek) vs Claude Fable 5.1 (Anthropic). Intelligence index 24.7 vs 46.8; output speed 203 vs 47 tokens per second; time to first token 0.79s vs 3.4s; output price $1.20 vs $50.00 per million tokens; input price $0.30 vs $10.00 per million tokens. franklineh.com
DeepSeek V4.1 Flash vs Claude Fable 5.1: head-to-head AI benchmark comparison. DeepSeek V4.1 Flash leads on output speed, time to first token, output price and input price; Claude Fable 5.1 leads on intelligence index.
Head to headUpdated

DeepSeek V4.1 Flash vs. Claude Fable 5.1: A Comparative Analysis

This comparison evaluates the performance, cost-efficiency, and benchmark capabilities of DeepSeek V4.1 Flash and Claude Fable 5.1. While DeepSeek offers high-speed, low-cost utility, Claude Fable 5.1 provides significantly higher intelligence and reasoning capabilities, presenting a clear trade-off between operational economy and complex problem-solving performance.

Pick it for DeepSeek V4.1 Flash · Non-Reasoning

  • Latency-sensitive chat, support, and interactive product flows
  • Longer responses where sustained output speed matters
  • Higher-volume workloads where blended token cost matters

Pick it for Claude Fable 5.1 · Adaptive Reasoning, Low Effort, Default Fallback

  • Workloads that benefit from the stronger overall intelligence score
  • Coding and agentic tasks where the benchmark edge matters
  • Teams already standardized on Anthropic

By the numbers

These figures describe the two model configurations shown here. A dash means the source snapshot had no usable figure for that metric. Scores, speed and API pricing may change as providers update models.

MetricDeepSeek V4.1 Flash (Non-Reasoning)Claude Fable 5.1 (Adaptive Reasoning, Low Effort, Default Fallback)
Intelligence Index24.746.8
Coding Index–75.2
Input price (per 1M tokens)$0.30$10.00
Output price (per 1M tokens)$1.20$50.00
Output speed (tokens/s)20347
Time to first token0.79s3.4s
Release date2026-09-102026-09-01

What the Benchmarks Show

The performance gap between DeepSeek V4.1 Flash and Claude Fable 5.1 is substantial across all measured metrics. Claude Fable 5.1 demonstrates a clear advantage in general intelligence, holding an index score of 46.8 compared to DeepSeek’s 24.7. This disparity is mirrored in the benchmark results: Claude achieves an HLE score of 0.489 and an LCR score of 0.823, whereas DeepSeek records 0.108 and 0.553, respectively. Furthermore, Claude’s coding index of 75.2 highlights its specialization in technical tasks. While DeepSeek provides a functional baseline for general queries, it lacks the specialized reasoning depth and technical proficiency observed in the Claude Fable 5.1 architecture.

Speed and Cost Trade-offs

Operational efficiency is where the two models diverge most sharply. DeepSeek V4.1 Flash is engineered for high-throughput environments, delivering an output speed of 203.209 tokens per second with a rapid time-to-first-token of 0.79 seconds. This performance comes at a highly competitive price point, with a blended cost of $0.53 per million tokens. In contrast, Claude Fable 5.1 prioritizes accuracy over raw speed. It operates at 47.308 tokens per second with a time-to-first-token of 3.398 seconds. The cost structure for Claude is significantly higher, with a blended rate of $20.00 per million tokens. Users must decide if the increased reasoning capability of Claude justifies a cost that is roughly 37 times higher than that of the DeepSeek model.

Aligning Models with Workflows

DeepSeek V4.1 Flash is best suited for high-volume, latency-sensitive applications where the cost of processing is a primary concern. Its rapid response time makes it ideal for real-time chat interfaces, large-scale data extraction, or simple classification tasks where the model does not need to perform deep logical deduction. The low cost allows for extensive scaling without the financial burden associated with more complex models.

Claude Fable 5.1 is designed for workflows that demand high cognitive fidelity. Its adaptive reasoning capabilities make it appropriate for complex coding projects, nuanced analytical writing, and tasks requiring high accuracy across technical benchmarks. While the latency is higher, the model’s ability to handle intricate instructions and provide more reliable outputs makes it the preferred choice for professional-grade development and research environments where precision is non-negotiable.

Decision Takeaway

Selecting the right model requires an honest assessment of your project's requirements. If your workflow involves repetitive, high-frequency tasks where speed and budget are the limiting factors, DeepSeek V4.1 Flash provides a reliable and efficient solution. However, if your objectives involve complex problem-solving or technical development where accuracy is paramount, the investment in Claude Fable 5.1 is warranted. The performance delta in the intelligence and coding indices suggests that Claude will handle edge cases and complex logic with a level of sophistication that the DeepSeek model is not currently positioned to match.

Common questions about Claude Fable 5.1 Adaptive Reasoning and DeepSeek V4.1 Flash Non-Reasoning

Is Claude Fable 5.1 Adaptive Reasoning better than DeepSeek V4.1 Flash Non-Reasoning?

Not across the board: Claude Fable 5.1 Adaptive Reasoning scores higher on the intelligence index, 46.8 to 24.7; DeepSeek V4.1 Flash Non-Reasoning is 97% cheaper on blended price; and DeepSeek V4.1 Flash Non-Reasoning streams output 4.3 times as fast.

Are Claude Fable 5.1 Adaptive Reasoning and DeepSeek V4.1 Flash Non-Reasoning from the same company?

Claude Fable 5.1 Adaptive Reasoning is made by Anthropic and DeepSeek V4.1 Flash Non-Reasoning by DeepSeek. Claude Fable 5.1 Adaptive Reasoning was released on September 1, 2026 and DeepSeek V4.1 Flash Non-Reasoning on September 10, 2026.

Which model has lower latency?

DeepSeek V4.1 Flash Non-Reasoning generates output faster, at 203 tokens per second against 47 tokens per second. DeepSeek V4.1 Flash Non-Reasoning reaches its first token sooner (0.79 seconds against 3.4 seconds).

Is Claude Fable 5.1 Adaptive Reasoning or DeepSeek V4.1 Flash Non-Reasoning better at coding?

The catalogue has no coding index for DeepSeek V4.1 Flash Non-Reasoning yet, so there is no direct coding comparison. The closest signal is the overall intelligence index, 46.8 for Claude Fable 5.1 Adaptive Reasoning and 24.7 for DeepSeek V4.1 Flash Non-Reasoning.

Which is newer, Claude Fable 5.1 Adaptive Reasoning or DeepSeek V4.1 Flash Non-Reasoning?

DeepSeek V4.1 Flash Non-Reasoning is newer. It was released on September 10, 2026, 9 days after Claude Fable 5.1 Adaptive Reasoning (September 1, 2026).

Final whistle

The choice between these models depends on your tolerance for latency and cost versus your need for reasoning depth. DeepSeek V4.1 Flash is an exceptional tool for high-volume, cost-sensitive tasks where speed is the primary constraint. Conversely, Claude Fable 5.1 is the superior choice for complex, high-stakes workflows that require advanced reasoning and higher accuracy, provided the user can accommodate the significantly higher cost and slower response times.

Where the numbers come from

The scores, speed and prices in this comparison come from independent third-party model evaluations that Franklin AI syncs each day, and the article was written from a snapshot of them. For the latest results, open the DeepSeek V4.1 Flash (Non-Reasoning) and Claude Fable 5.1 (Adaptive Reasoning, Low Effort, Default Fallback) pages. The AI Benchmark methodology explains how that data is collected and shown.

Comments (0)

No comments yet

Be the first to share your thoughts!