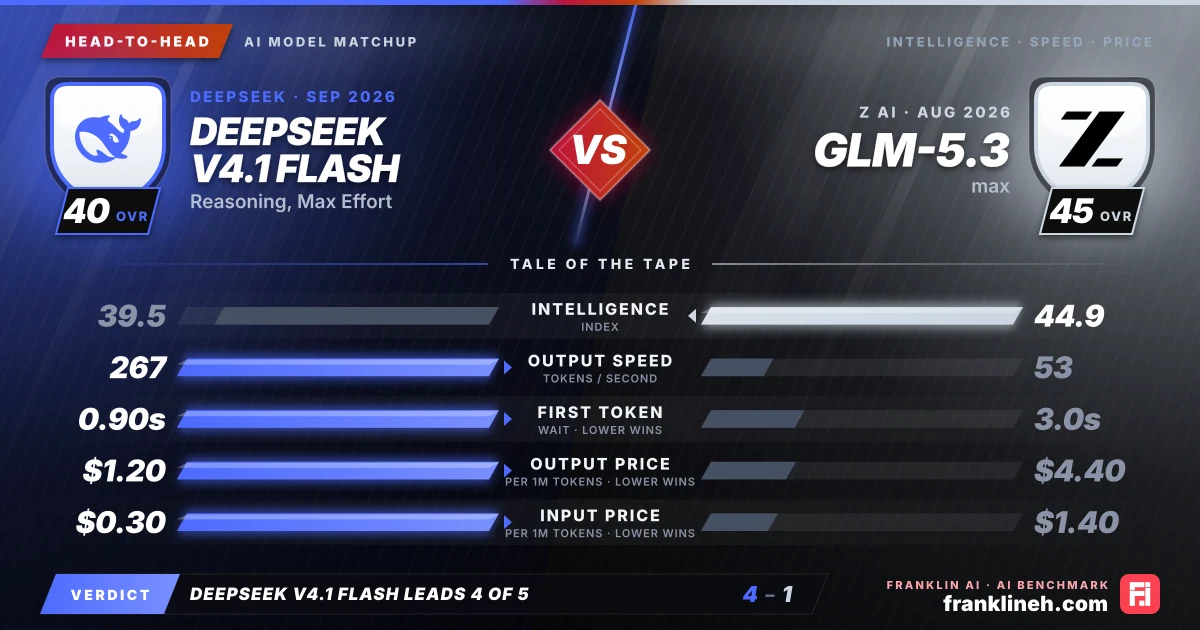
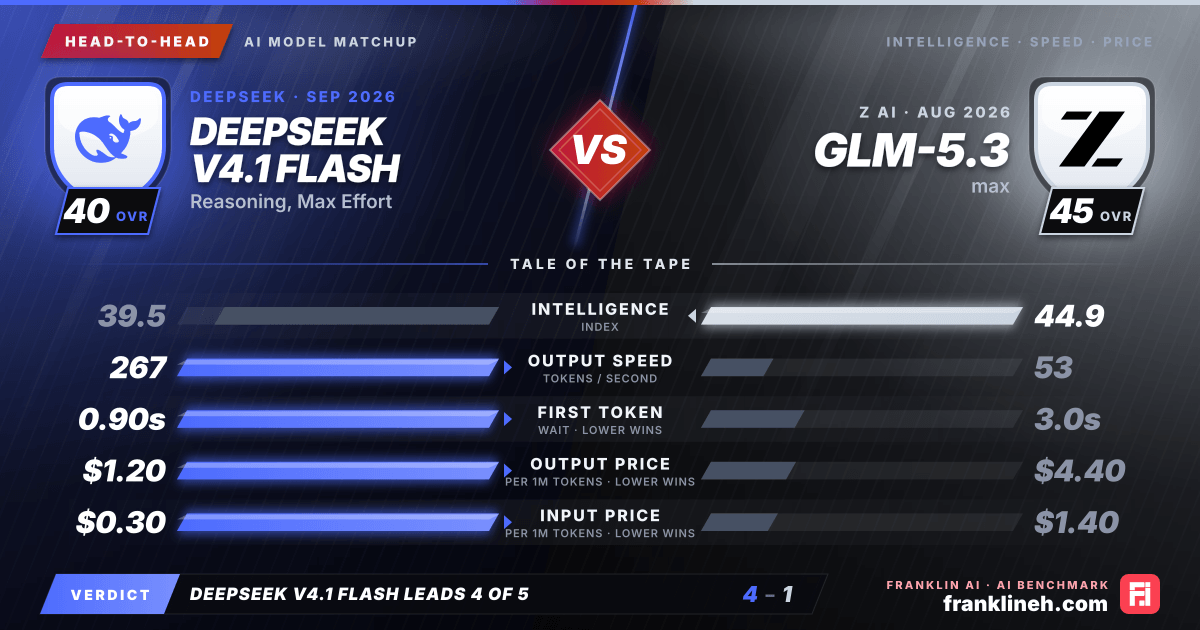
Head-to-head AI model comparison graphic: DeepSeek V4.1 Flash (DeepSeek) vs GLM-5.3 (Z AI). Intelligence index 39.5 vs 44.9; output speed 267 vs 53 tokens per second; time to first token 0.90s vs 3.0s; output price $1.20 vs $4.40 per million tokens; input price $0.30 vs $1.40 per million tokens. franklineh.com
DeepSeek V4.1 Flash vs GLM-5.3: head-to-head AI benchmark comparison. DeepSeek V4.1 Flash leads on output speed, time to first token, output price and input price; GLM-5.3 leads on intelligence index.
Head to headUpdated

DeepSeek V4.1 Flash vs. GLM-5.3 (max): A Comparative Analysis

This comparison evaluates the DeepSeek V4.1 Flash and Z AI’s GLM-5.3 (max), highlighting the trade-offs between DeepSeek’s high-velocity, cost-effective architecture and GLM-5.3’s superior intelligence and coding capabilities. Choosing between these models depends on whether your priority is rapid, large-scale throughput or high-precision reasoning and complex development tasks.

Pick it for DeepSeek V4.1 Flash · Reasoning, Max Effort

  • Latency-sensitive chat, support, and interactive product flows
  • Longer responses where sustained output speed matters
  • Higher-volume workloads where blended token cost matters

Pick it for GLM-5.3 · Max

  • Workloads that benefit from the stronger overall intelligence score
  • Coding and agentic tasks where the benchmark edge matters
  • Teams already standardized on Z AI

By the numbers

These figures describe the two model configurations shown here. A dash means the source snapshot had no usable figure for that metric. Scores, speed and API pricing may change as providers update models.

MetricDeepSeek V4.1 Flash (Reasoning, Max Effort)GLM-5.3 (max)
Intelligence Index39.544.9
Coding Index–74.8
Input price (per 1M tokens)$0.30$1.40
Output price (per 1M tokens)$1.20$4.40
Output speed (tokens/s)26753
Time to first token0.90s3.0s
Release date2026-09-102026-08-18

What the Benchmarks Show

When evaluating the raw intelligence of these two models, the data suggests distinct specializations. GLM-5.3 (max) holds a clear advantage in general intelligence, boasting an index of 44.9 compared to DeepSeek V4.1 Flash’s 39.5. This lead is further reflected in specialized benchmarks: GLM-5.3 (max) achieves a GPQA score of 0.917 and a SciCode score of 0.59, outperforming DeepSeek’s 0.519 in the latter. Furthermore, GLM-5.3 (max) demonstrates significant proficiency in software development with a coding index of 74.8.

DeepSeek V4.1 Flash, however, remains competitive in specific areas. It achieves an LCR score of 0.84, surpassing the 0.797 recorded by GLM-5.3 (max). While the HLE benchmark shows GLM-5.3 (max) at 0.423 against DeepSeek’s 0.392, the gap is relatively narrow. The data indicates that while GLM-5.3 (max) is better suited for complex scientific and coding reasoning, DeepSeek V4.1 Flash maintains a strong baseline performance that is highly capable for standard reasoning tasks.

Speed and Cost

The most significant differentiator between these models is their operational efficiency. DeepSeek V4.1 Flash is engineered for high-speed, low-cost deployment, delivering an impressive output speed of 267.06 tokens per second with a time-to-first-token of just 0.896 seconds. This performance is paired with a blended pricing model of $0.53 per million tokens.

In contrast, GLM-5.3 (max) prioritizes depth over raw speed. It operates at a significantly slower output speed of 53.453 tokens per second and a time-to-first-token of 2.987 seconds. The cost structure is also substantially higher, with a blended price of $2.15 per million tokens. Users must weigh the necessity of real-time, high-throughput responses against the requirement for the deeper, more resource-intensive processing provided by the GLM architecture.

Which Model Fits Which Workflow

DeepSeek V4.1 Flash is optimized for environments where latency and budget are the primary constraints. Its high token-per-second rate makes it an ideal candidate for real-time customer support agents, large-scale data processing pipelines, and applications where the cost of inference must be minimized without sacrificing basic reasoning capabilities. The model's efficiency allows for frequent, high-volume interactions that would be prohibitively expensive or sluggish with heavier models.

GLM-5.3 (max) is better suited for high-stakes, compute-heavy workflows. Its superior intelligence and coding indices make it a robust tool for software engineering, complex mathematical problem-solving, and research-oriented tasks where the model's ability to navigate intricate logic is more valuable than the speed of the output. While the higher cost and latency are notable, they are justified by the model's increased accuracy in specialized domains.

Decision Takeaway

Ultimately, the decision rests on the specific demands of your application. If your workflow requires high-frequency, cost-effective automation, DeepSeek V4.1 Flash provides the necessary velocity. If your project demands high-level reasoning, complex code generation, or advanced problem-solving, the investment in GLM-5.3 (max) is likely to yield more accurate and reliable results.

FAQ

Is DeepSeek V4.1 Flash Reasoning better than GLM-5.3 max?

It depends on what you need: GLM-5.3 max scores higher on the intelligence index, 44.9 to 39.5; DeepSeek V4.1 Flash Reasoning is 76% cheaper on blended price; and DeepSeek V4.1 Flash Reasoning streams output 5 times as fast.

Is GLM-5.3 max cheaper than DeepSeek V4.1 Flash Reasoning?

DeepSeek V4.1 Flash Reasoning is cheaper on a blended basis. DeepSeek V4.1 Flash Reasoning lists $0.30 per million input tokens and $1.20 per million output tokens; GLM-5.3 max lists $1.40 and $4.40. For 1 million input and 200,000 output tokens that is $0.54 against $2.28.

Does DeepSeek V4.1 Flash Reasoning respond faster than GLM-5.3 max?

DeepSeek V4.1 Flash Reasoning generates output faster, at 267 tokens per second against 53 tokens per second. DeepSeek V4.1 Flash Reasoning reaches its first token sooner (0.90 seconds against 3.0 seconds).

Are DeepSeek V4.1 Flash Reasoning and GLM-5.3 max from the same company?

DeepSeek V4.1 Flash Reasoning is made by DeepSeek and GLM-5.3 max by Z AI. DeepSeek V4.1 Flash Reasoning was released on September 10, 2026 and GLM-5.3 max on August 18, 2026.

Is DeepSeek V4.1 Flash Reasoning or GLM-5.3 max better at coding?

The catalogue has no coding index for DeepSeek V4.1 Flash Reasoning yet, so there is no direct coding comparison. The closest signal is the overall intelligence index, 39.5 for DeepSeek V4.1 Flash Reasoning and 44.9 for GLM-5.3 max.

Final whistle

The choice between these models hinges on your project's constraints. DeepSeek V4.1 Flash is the superior choice for high-volume, latency-sensitive applications where cost-efficiency is paramount. Conversely, GLM-5.3 (max) is the clear winner for complex, logic-heavy tasks and software engineering workflows where accuracy and reasoning depth outweigh the higher operational costs and slower response times. Evaluate your tolerance for latency against your requirement for advanced intelligence to determine the optimal fit.

Where the numbers come from

The scores, speed and prices in this comparison come from independent third-party model evaluations that Franklin AI syncs each day, and the article was written from a snapshot of them. For the latest results, open the DeepSeek V4.1 Flash (Reasoning, Max Effort) and GLM-5.3 (max) pages. The AI Benchmark methodology explains how that data is collected and shown.

Comments (0)

No comments yet

Be the first to share your thoughts!