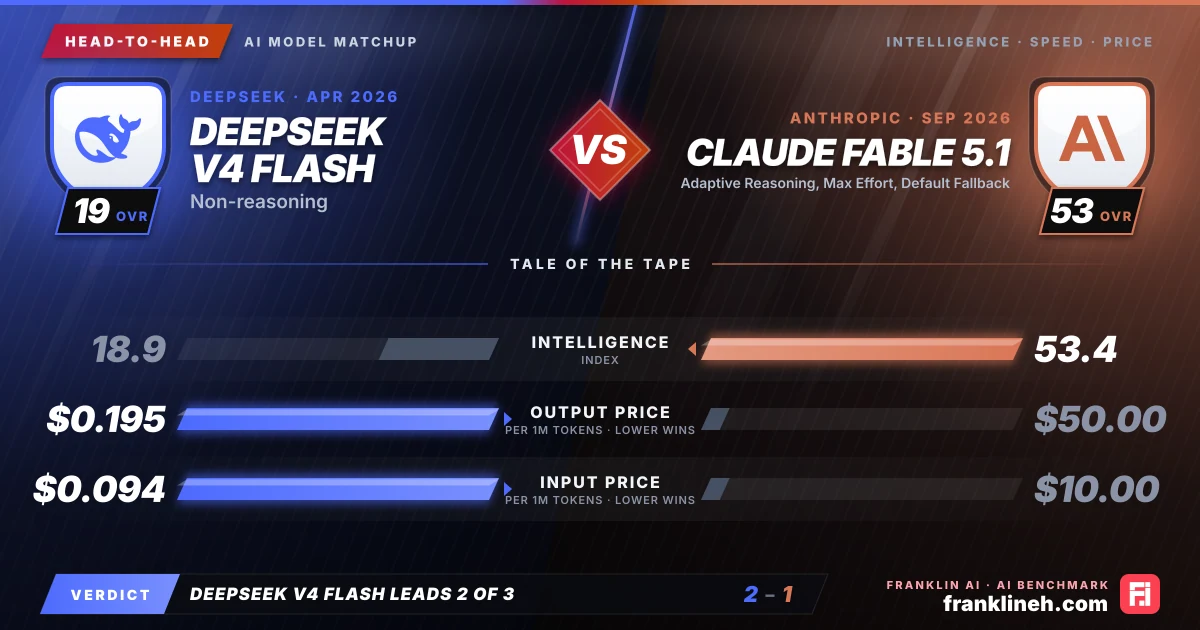
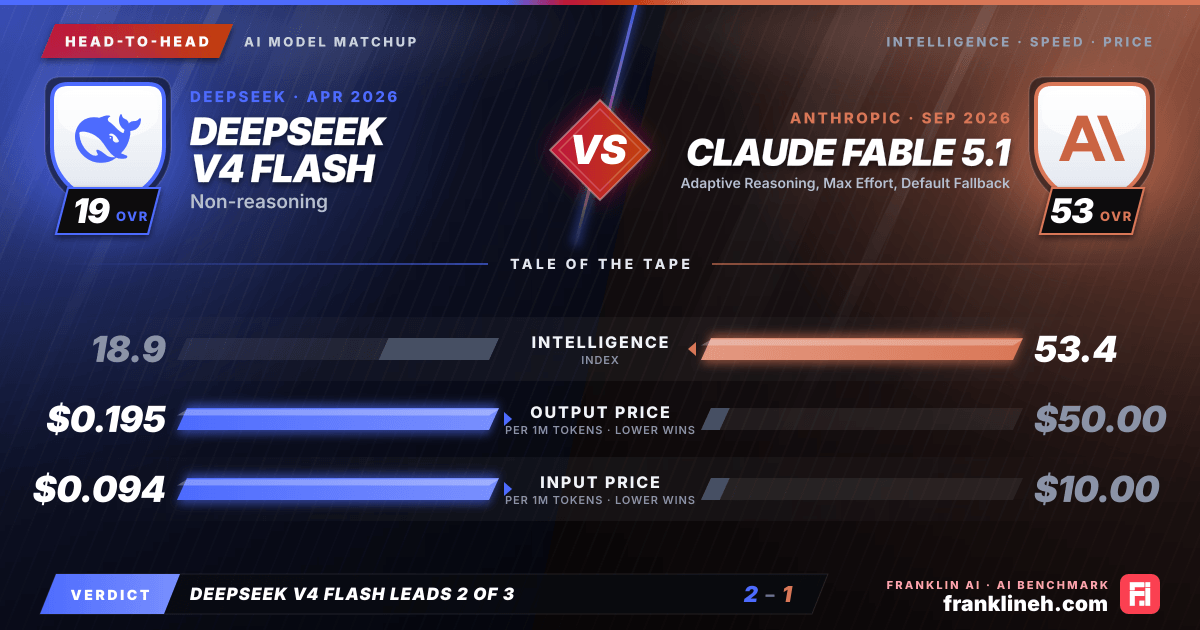
Head-to-head AI model comparison graphic: DeepSeek V4 Flash (DeepSeek) vs Claude Fable 5.1 (Anthropic). Intelligence index 18.9 vs 53.4; output price $0.195 vs $50.00 per million tokens; input price $0.094 vs $10.00 per million tokens. franklineh.com
DeepSeek V4 Flash vs Claude Fable 5.1: head-to-head AI benchmark comparison. DeepSeek V4 Flash leads on output price and input price; Claude Fable 5.1 leads on intelligence index.
Head to headUpdated

DeepSeek V4 Flash vs. Claude Fable 5.1: A Comparative Analysis

This analysis compares the cost-efficient DeepSeek V4 Flash with the high-reasoning Claude Fable 5.1. While DeepSeek offers extreme affordability for high-volume tasks, Claude Fable 5.1 provides superior intelligence and coding capabilities for complex problem-solving, highlighting a clear trade-off between operational expenditure and model performance.

Pick it for DeepSeek V4 Flash · Non-reasoning

  • Latency-sensitive chat, support, and interactive product flows
  • Higher-volume workloads where blended token cost matters
  • Teams already standardized on DeepSeek

Pick it for Claude Fable 5.1 · Adaptive Reasoning, Max Effort, Default Fallback

  • Workloads that benefit from the stronger overall intelligence score
  • Coding and agentic tasks where the benchmark edge matters
  • Longer responses where sustained output speed matters

By the numbers

These figures describe the two model configurations shown here. A dash means the source snapshot had no usable figure for that metric. Scores, speed and API pricing may change as providers update models.

MetricDeepSeek V4 Flash (Non-reasoning)Claude Fable 5.1 (Adaptive Reasoning, Max Effort, Default Fallback)
Intelligence Index18.953.4
Coding Index–81.6
Input price (per 1M tokens)$0.094$10.00
Output price (per 1M tokens)$0.195$50.00
Output speed (tokens/s)–68
Time to first token–2.3 min
Release date2026-04-242026-09-01

Understanding the Benchmark Landscape

The performance gap between DeepSeek V4 Flash and Claude Fable 5.1 is significant, reflecting their distinct design philosophies. Claude Fable 5.1, released in September 2026, boasts an Intelligence index of 53.4 and a Coding index of 81.6. Its performance on the GPQA benchmark (0.937) and LCR (0.853) demonstrates a high capacity for complex reasoning and technical accuracy. In contrast, DeepSeek V4 Flash, released in April 2026, shows an Intelligence index of 18.9. While its benchmark scores, such as 0.716 on GPQA and 0.472 on IFBench, indicate a capable model for standard tasks, it lacks the specialized coding and reasoning depth found in the Fable 5.1 architecture.

Evaluating Speed and Cost Efficiency

The economic disparity between these two models is stark. DeepSeek V4 Flash is positioned as a high-efficiency tool, with a blended pricing model of $0.12 per million tokens. This makes it a highly attractive option for developers managing large-scale data processing or high-frequency API calls where cost management is critical. While specific output speeds for the V4 Flash remain unknown, its pricing structure suggests it is optimized for throughput rather than deep, multi-step inference.

Claude Fable 5.1 operates at a premium, with a blended cost of $20.00 per million tokens. This cost is accompanied by a measured output speed of 68.471 tokens per second and a time-to-first-token of 137.018 seconds. These metrics indicate that Fable 5.1 is designed for precision and deep reasoning, where the model requires more time to process complex instructions before delivering a response. Users must weigh this higher latency and cost against the model's ability to handle sophisticated coding and logic tasks that the V4 Flash may struggle to resolve.

Determining the Right Workflow

Selecting the appropriate model requires an assessment of the task's complexity. DeepSeek V4 Flash is best suited for workflows that prioritize volume and cost-effectiveness. It is well-positioned for tasks such as simple data extraction, routine text classification, or high-volume content generation where the model's lower intelligence index is sufficient to meet the requirements. Because it is a non-reasoning model, it avoids the latency overhead associated with adaptive reasoning processes.

Claude Fable 5.1 is engineered for high-complexity environments. Its adaptive reasoning and max-effort capabilities make it the preferred choice for software engineering, complex research, and tasks requiring high-fidelity logical output. The model's ability to handle technical coding challenges, as evidenced by its 81.6 coding index, makes it a powerful asset for developers who need reliable, high-quality code generation and debugging assistance. While the cost is significantly higher, the reduction in manual oversight and error correction often provides a net benefit in professional development environments.

Frequently asked questions

Is Claude Fable 5.1 Adaptive Reasoning better than DeepSeek V4 Flash Non-reasoning?

Neither wins everywhere: Claude Fable 5.1 Adaptive Reasoning scores higher on the intelligence index, 53.4 to 18.9; and DeepSeek V4 Flash Non-reasoning is 99% cheaper on blended price.

Which is cheaper, Claude Fable 5.1 Adaptive Reasoning or DeepSeek V4 Flash Non-reasoning?

DeepSeek V4 Flash Non-reasoning is cheaper on a blended basis. Claude Fable 5.1 Adaptive Reasoning lists $10.00 per million input tokens and $50.00 per million output tokens; DeepSeek V4 Flash Non-reasoning lists $0.094 and $0.195. For 1 million input and 200,000 output tokens that is $20.00 against $0.13.

When were Claude Fable 5.1 Adaptive Reasoning and DeepSeek V4 Flash Non-reasoning released?

Claude Fable 5.1 Adaptive Reasoning is newer. It was released on September 1, 2026, about 4 months after DeepSeek V4 Flash Non-reasoning (April 24, 2026).

Is Claude Fable 5.1 Adaptive Reasoning or DeepSeek V4 Flash Non-reasoning better at coding?

The catalogue has no coding index for DeepSeek V4 Flash Non-reasoning yet, so there is no direct coding comparison. The closest signal is the overall intelligence index, 53.4 for Claude Fable 5.1 Adaptive Reasoning and 18.9 for DeepSeek V4 Flash Non-reasoning.

Who makes Claude Fable 5.1 Adaptive Reasoning and DeepSeek V4 Flash Non-reasoning?

Claude Fable 5.1 Adaptive Reasoning is made by Anthropic and DeepSeek V4 Flash Non-reasoning by DeepSeek. Claude Fable 5.1 Adaptive Reasoning was released on September 1, 2026 and DeepSeek V4 Flash Non-reasoning on April 24, 2026.

Final whistle

The choice between these models depends on your specific resource constraints. DeepSeek V4 Flash is an ideal utility model for high-volume, low-complexity tasks where budget is the primary concern. Conversely, Claude Fable 5.1 is the superior choice for high-stakes development and reasoning-heavy workflows. If your project requires advanced coding or complex logical deduction, the performance gains of Claude justify its higher cost, whereas DeepSeek is best reserved for tasks where speed and cost-efficiency are prioritized over deep reasoning.

Where the numbers come from

The scores, speed and prices in this comparison come from independent third-party model evaluations that Franklin AI syncs each day, and the article was written from a snapshot of them. For the latest results, open the DeepSeek V4 Flash (Non-reasoning) and Claude Fable 5.1 (Adaptive Reasoning, Max Effort, Default Fallback) pages. The AI Benchmark methodology explains how that data is collected and shown.

Comments (0)

No comments yet

Be the first to share your thoughts!