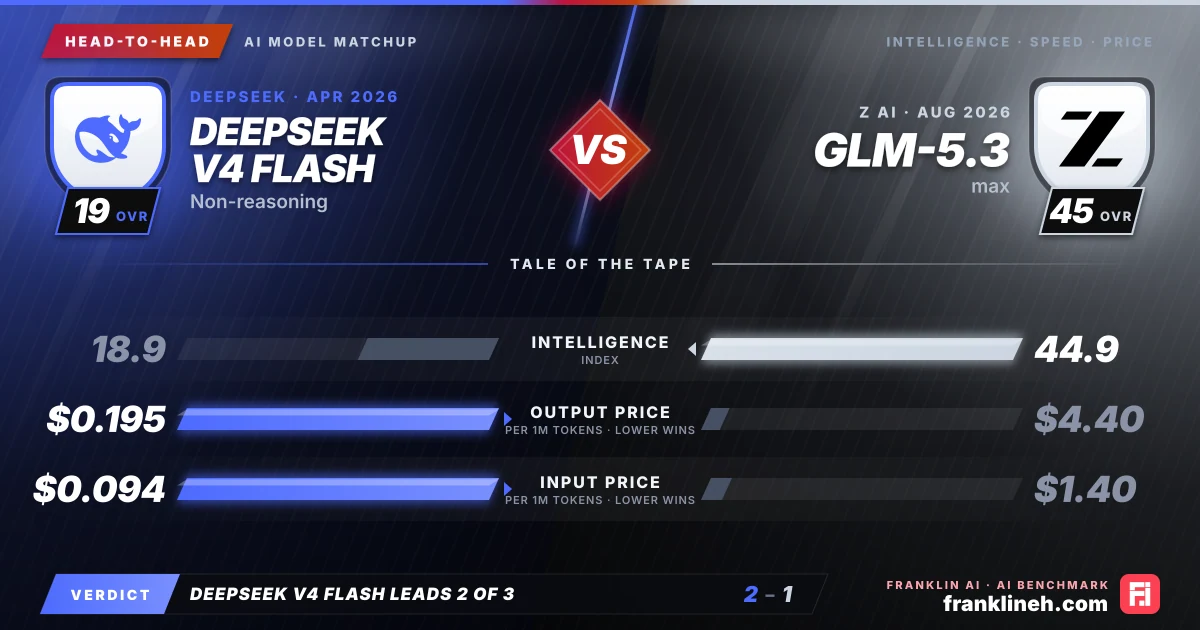
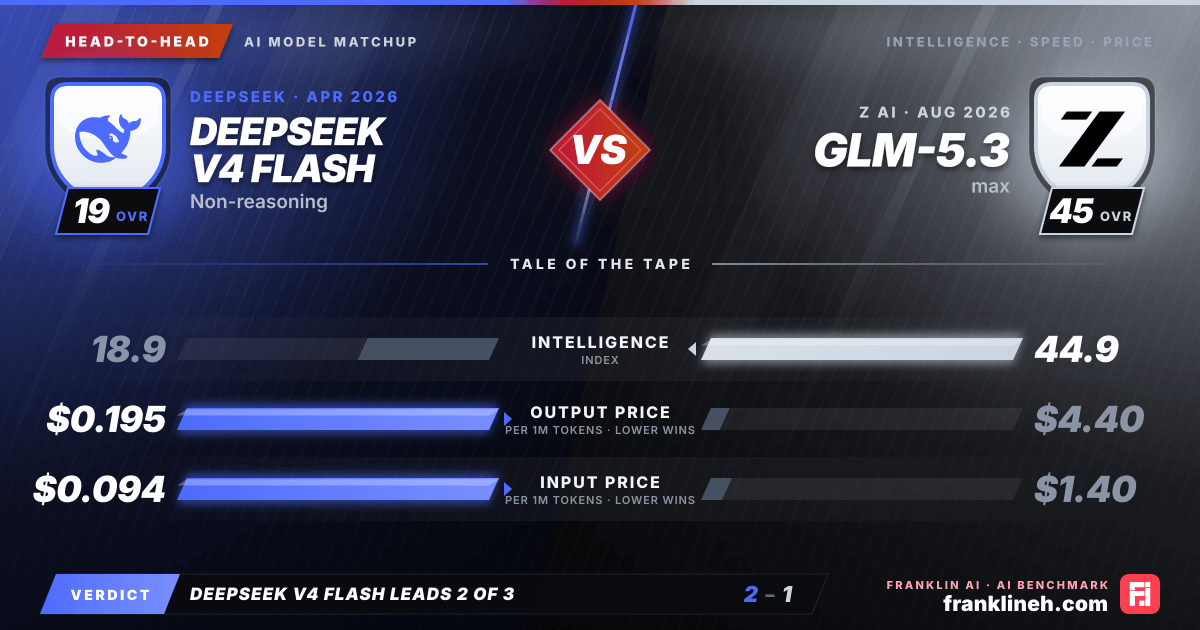
Head-to-head AI model comparison graphic: DeepSeek V4 Flash (DeepSeek) vs GLM-5.3 (Z AI). Intelligence index 18.9 vs 44.9; output price $0.195 vs $4.40 per million tokens; input price $0.094 vs $1.40 per million tokens. franklineh.com
DeepSeek V4 Flash vs GLM-5.3: head-to-head AI benchmark comparison. DeepSeek V4 Flash leads on output price and input price; GLM-5.3 leads on intelligence index.
Head to headUpdated

DeepSeek V4 Flash vs. GLM-5.3 (max): A Comparative Analysis

This analysis compares the DeepSeek V4 Flash and GLM-5.3 (max) models, evaluating their distinct positioning in intelligence, cost-efficiency, and performance benchmarks to help users determine the optimal choice for their specific computational requirements.

Pick it for DeepSeek V4 Flash · Non-reasoning

  • Latency-sensitive chat, support, and interactive product flows
  • Higher-volume workloads where blended token cost matters
  • Teams already standardized on DeepSeek

Pick it for GLM-5.3 · Max

  • Workloads that benefit from the stronger overall intelligence score
  • Coding and agentic tasks where the benchmark edge matters
  • Longer responses where sustained output speed matters

By the numbers

MetricDeepSeek V4 Flash (Non-reasoning)GLM-5.3 (max)
Intelligence Index18.944.9
Coding Index–74.8
Input price (per 1M tokens)$0.094$1.40
Output price (per 1M tokens)$0.195$4.40
Output speed (tokens/s)–61
Time to first token–2.7s
Release date2026-04-242026-08-18

Understanding the Benchmark Landscape

The performance disparity between DeepSeek V4 Flash and GLM-5.3 (max) is significant, reflecting their different design philosophies. With an intelligence index of 44.9, GLM-5.3 (max) substantially outperforms DeepSeek V4 Flash, which holds an intelligence index of 18.9. This gap is mirrored in the benchmark results: GLM-5.3 (max) achieves a GPQA score of 0.917 and an HLE score of 0.423, compared to 0.716 and 0.078 for DeepSeek V4 Flash, respectively. Furthermore, GLM-5.3 (max) demonstrates strong specialized capabilities with a coding index of 74.8 and a SciCode score of 0.59. While DeepSeek V4 Flash shows competitive performance in specific areas like TAU2 (0.944), its lower scores across LCR and TerminalBench Hard suggest it is optimized for different, perhaps less computationally demanding, tasks than the GLM-5.3 (max).

Speed and Cost Trade-offs

The economic profiles of these two models are starkly different. DeepSeek V4 Flash is positioned as a high-efficiency, low-cost model, with a blended price of $0.12 per million tokens. This makes it significantly more affordable than GLM-5.3 (max), which carries a blended cost of $2.15 per million tokens. For organizations processing massive datasets or running high-frequency agentic workflows, the cost savings offered by DeepSeek are substantial. However, this affordability comes without the performance transparency found in the GLM-5.3 (max), which reports a clear output speed of 60.919 tokens per second and a time-to-first-token of 2.666 seconds. DeepSeek V4 Flash does not provide public data regarding its output speed or latency, which may be a consideration for developers building time-sensitive applications.

Aligning Models with Workflows

Determining which model fits a specific workflow requires balancing the need for high-level reasoning against operational expenditure. GLM-5.3 (max) is clearly built for complex, high-stakes environments. Its superior coding index and benchmark performance suggest it is well-suited for software development, scientific research, and advanced analytical tasks where the cost of an error outweighs the cost of the token usage. The model's ability to handle complex logic is evidenced by its high intelligence index, making it a robust tool for sophisticated agentic workflows.

In contrast, DeepSeek V4 Flash is an ideal candidate for high-throughput scenarios where the primary goal is efficiency. Its pricing structure allows for broad deployment in applications where the model's intelligence index is sufficient for the task at hand, such as basic data classification, high-volume content summarization, or routine automated responses. By choosing DeepSeek V4 Flash, developers can scale their operations significantly without the proportional increase in costs associated with premium models like GLM-5.3 (max).

Final Considerations

Ultimately, the decision rests on the specific requirements of the project. If the application demands top-tier reasoning and coding capabilities, the investment in GLM-5.3 (max) is justified by its performance metrics. If the project requires a cost-effective, high-volume solution where extreme reasoning depth is secondary to throughput and budget, DeepSeek V4 Flash provides a compelling, economical alternative. Users should weigh the known performance metrics of GLM-5.3 against the budget-friendly, albeit less transparent, architecture of DeepSeek V4 Flash.

Quick answers

Is GLM-5.3 max better than DeepSeek V4 Flash Non-reasoning?

Not across the board: GLM-5.3 max scores higher on the intelligence index, 44.9 to 18.9; and DeepSeek V4 Flash Non-reasoning is 94% cheaper on blended price.

When were DeepSeek V4 Flash Non-reasoning and GLM-5.3 max released?

GLM-5.3 max is newer. It was released on August 18, 2026, about 4 months after DeepSeek V4 Flash Non-reasoning (April 24, 2026).

Which is better for coding, DeepSeek V4 Flash Non-reasoning or GLM-5.3 max?

The catalogue has no coding index for DeepSeek V4 Flash Non-reasoning yet, so there is no direct coding comparison. The closest signal is the overall intelligence index, 18.9 for DeepSeek V4 Flash Non-reasoning and 44.9 for GLM-5.3 max.

How much do DeepSeek V4 Flash Non-reasoning and GLM-5.3 max cost?

DeepSeek V4 Flash Non-reasoning is cheaper on a blended basis. DeepSeek V4 Flash Non-reasoning lists $0.094 per million input tokens and $0.195 per million output tokens; GLM-5.3 max lists $1.40 and $4.40. For 1 million input and 200,000 output tokens that is $0.13 against $2.28.

Who makes DeepSeek V4 Flash Non-reasoning and GLM-5.3 max?

DeepSeek V4 Flash Non-reasoning is made by DeepSeek and GLM-5.3 max by Z AI. DeepSeek V4 Flash Non-reasoning was released on April 24, 2026 and GLM-5.3 max on August 18, 2026.

Final whistle

The choice between these models hinges on the trade-off between cost and raw capability. DeepSeek V4 Flash is an exceptionally economical choice for high-volume, lightweight tasks where budget is the primary constraint. Conversely, GLM-5.3 (max) is the superior choice for complex, reasoning-intensive workflows where performance accuracy is critical. Users requiring high-level coding proficiency or superior general intelligence should prioritize GLM-5.3, while those managing large-scale, cost-sensitive agentic workflows will find V4 Flash more sustainable.

Where the numbers come from

The scores, speed and prices in this comparison come from independent third-party model evaluations that Franklin AI syncs each day, and the article was written from a snapshot of them. For the latest results, open the DeepSeek V4 Flash (Non-reasoning) and GLM-5.3 (max) pages. The AI Benchmark methodology explains how that data is collected and shown.

Comments (0)

No comments yet

Be the first to share your thoughts!