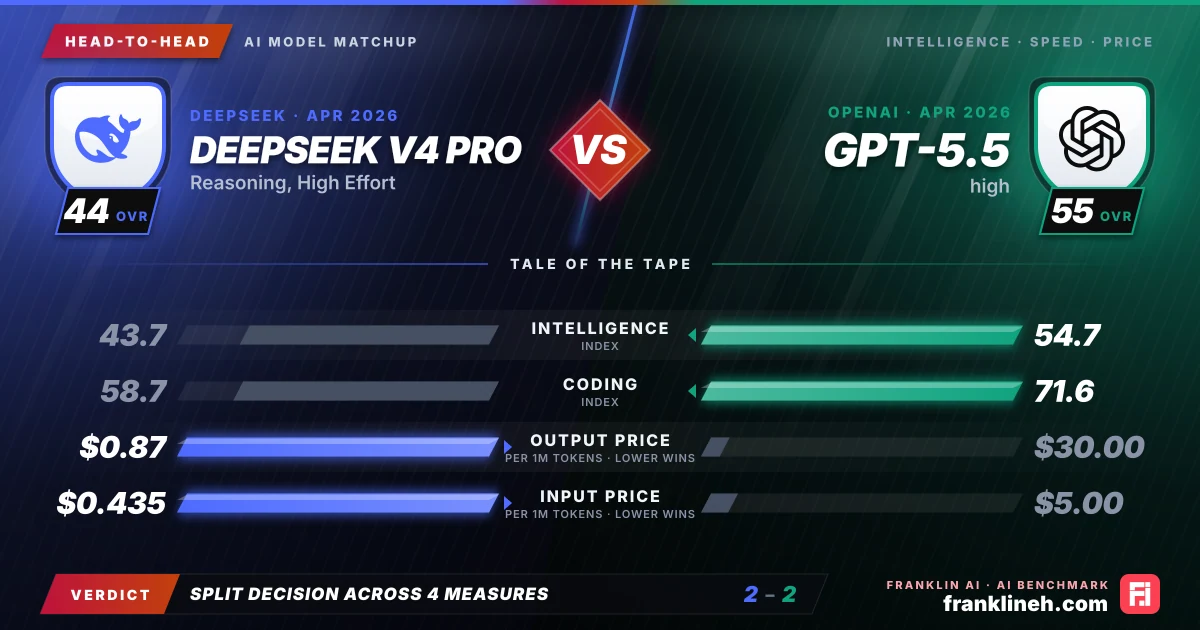
Head-to-head AI model comparison graphic: DeepSeek V4 Pro (DeepSeek) vs GPT-5.5 (OpenAI). Intelligence index 43.7 vs 54.7; coding index 58.7 vs 71.6; output price $0.87 vs $30.00 per million tokens; input price $0.435 vs $5.00 per million tokens. franklineh.com
DeepSeek V4 Pro vs GPT-5.5: head-to-head AI benchmark comparison. DeepSeek V4 Pro leads on output price and input price; GPT-5.5 leads on intelligence index and coding index.
Head to headUpdated

DeepSeek V4 Pro vs. GPT-5.5: A Comparative Analysis

Released just one day apart in April 2026, DeepSeek V4 Pro and OpenAI’s GPT-5.5 represent the latest frontier in AI development. While GPT-5.5 leads in raw intelligence and coding capability, DeepSeek V4 Pro offers a distinct advantage in cost-efficiency and operational transparency for high-volume reasoning tasks.

Pick it for DeepSeek V4 Pro · Reasoning, High Effort

  • Longer responses where sustained output speed matters
  • Higher-volume workloads where blended token cost matters
  • Teams already standardized on DeepSeek

Pick it for GPT-5.5 · High

  • Workloads that benefit from the stronger overall intelligence score
  • Coding and agentic tasks where the benchmark edge matters
  • Latency-sensitive chat, support, and interactive product flows

By the numbers

These figures describe the two model configurations shown here. A dash means the source snapshot had no usable figure for that metric. Scores, speed and API pricing may change as providers update models.

MetricDeepSeek V4 Pro (Reasoning, High Effort)GPT-5.5 (high)
Intelligence Index43.754.7
Coding Index58.771.6
Input price (per 1M tokens)$0.435$5.00
Output price (per 1M tokens)$0.87$30.00
Output speed (tokens/s)61–
Time to first token1.4s–
Release date2026-04-242026-04-23

Benchmarking Intelligence and Capability

When evaluating the raw performance metrics of these two models, GPT-5.5 consistently holds the lead across most standardized benchmarks. With an intelligence index of 54.7 compared to DeepSeek V4 Pro’s 43.7, and a coding index of 71.6 versus 58.7, GPT-5.5 demonstrates a higher ceiling for complex problem-solving and software development tasks. This superiority is reflected in the benchmark scores: GPT-5.5 achieves higher marks in GPQA (0.932), HLE (0.45), and SciCode (0.559).

However, the gap narrows significantly in specific domains. In the TAU2 benchmark, DeepSeek V4 Pro actually outperforms GPT-5.5 with a score of 0.941 compared to 0.929, suggesting that DeepSeek’s reasoning architecture is highly optimized for specific task-based evaluations. Furthermore, both models show comparable performance on IFBench, with scores of 0.712 and 0.716 respectively, indicating that both are equally capable of following complex, multi-step instructions.

Speed and Cost Tradeoffs

The most striking difference between these two models lies in their economic profile. DeepSeek V4 Pro is positioned as an exceptionally cost-effective solution, with a blended pricing of $0.54 per million tokens. In contrast, GPT-5.5 commands a premium price, with a blended cost of $11.25 per million tokens—more than 20 times the cost of the DeepSeek alternative. For organizations processing massive datasets or running continuous reasoning loops, this price disparity is the primary factor in model selection.

Operational speed further differentiates the two. DeepSeek V4 Pro provides transparent performance data, delivering an output speed of 61.151 tokens per second with a time-to-first-token of 1.398 seconds. While performance metrics for GPT-5.5 remain unlisted, the sheer scale of the model typically implies higher latency compared to more specialized, high-efficiency architectures. Users requiring real-time responsiveness will find the predictable, high-speed output of DeepSeek V4 Pro to be a significant operational asset.

Aligning Models with Workflows

Selecting the appropriate model requires an assessment of your specific project requirements. GPT-5.5 is best suited for high-complexity, low-volume tasks where the cost of an error outweighs the cost of the API call. Its superior coding index and broader intelligence metrics make it the preferred engine for advanced software architecture, complex scientific research, and high-level analytical reasoning where every percentage point of accuracy is critical.

DeepSeek V4 Pro is designed for high-throughput environments. Its aggressive pricing structure and high-speed output make it ideal for agentic workflows, large-scale data processing, and applications where the model must run frequently without incurring prohibitive costs. While it may trail GPT-5.5 in peak intelligence, its performance on the TAU2 benchmark proves it is more than capable of handling sophisticated reasoning tasks at a fraction of the cost, making it the more sustainable choice for long-term, high-volume production deployments.

Frequently asked questions

Is GPT-5.5 high better than DeepSeek V4 Pro?

Not across the board: GPT-5.5 high scores higher on the intelligence index, 54.7 to 43.7; and DeepSeek V4 Pro is 95% cheaper on blended price.

Are DeepSeek V4 Pro and GPT-5.5 high from the same company?

DeepSeek V4 Pro is made by DeepSeek and GPT-5.5 high by OpenAI. DeepSeek V4 Pro was released on April 24, 2026 and GPT-5.5 high on April 23, 2026.

Which is cheaper, DeepSeek V4 Pro or GPT-5.5 high?

DeepSeek V4 Pro is cheaper on a blended basis. DeepSeek V4 Pro lists $0.435 per million input tokens and $0.87 per million output tokens; GPT-5.5 high lists $5.00 and $30.00. For 1 million input and 200,000 output tokens that is $0.61 against $11.00.

Is DeepSeek V4 Pro or GPT-5.5 high better at coding?

GPT-5.5 high has the higher coding index, 71.6 against 58.7.

Which is newer, DeepSeek V4 Pro or GPT-5.5 high?

DeepSeek V4 Pro is newer. It was released on April 24, 2026, one day after GPT-5.5 high (April 23, 2026).

Final whistle

The choice between these models hinges on the balance between peak performance and operational overhead. GPT-5.5 is the clear choice for complex, high-stakes coding and reasoning projects where accuracy is paramount and budget is secondary. Conversely, DeepSeek V4 Pro is the superior option for scaling intensive reasoning workflows, offering a highly competitive performance-to-cost ratio that makes it significantly more accessible for sustained, high-volume production environments.

Where the numbers come from

The scores, speed and prices in this comparison come from independent third-party model evaluations that Franklin AI syncs each day, and the article was written from a snapshot of them. For the latest results, open the DeepSeek V4 Pro (Reasoning, High Effort) and GPT-5.5 (high) pages. The AI Benchmark methodology explains how that data is collected and shown.

Comments (0)

No comments yet

Be the first to share your thoughts!