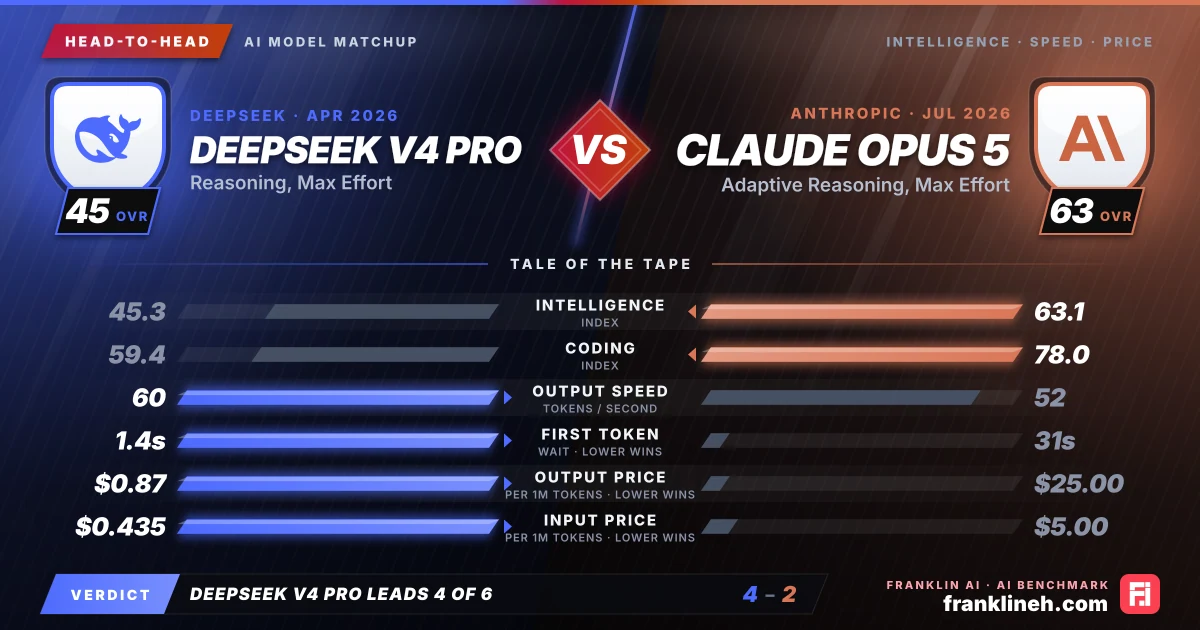
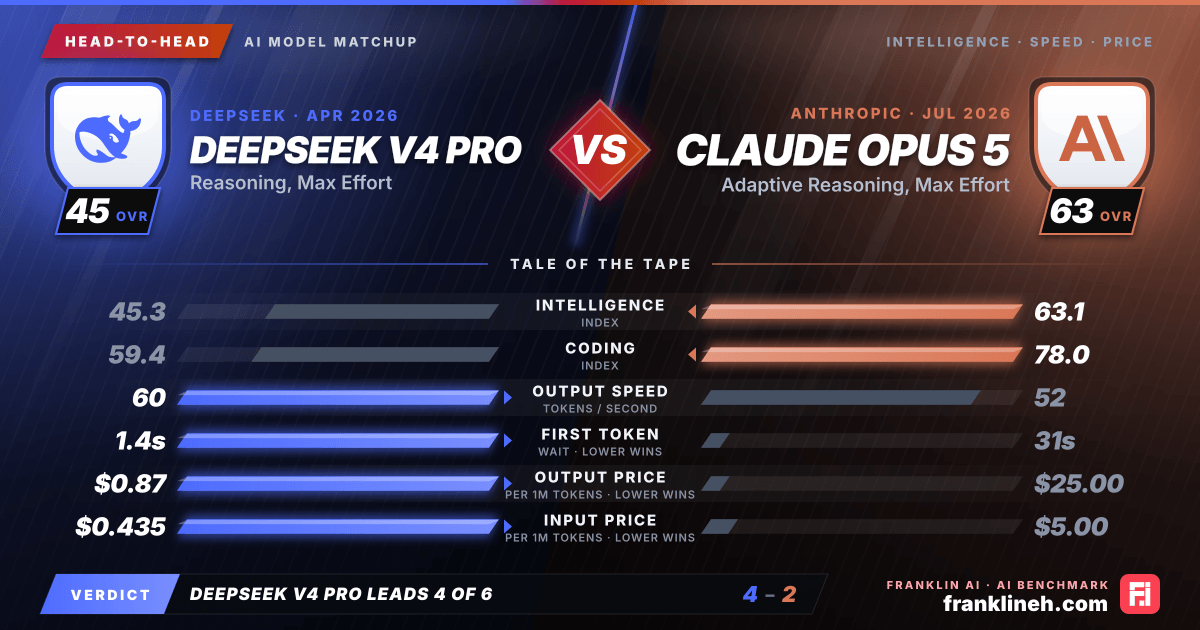
Head-to-head AI model comparison graphic: DeepSeek V4 Pro (DeepSeek) vs Claude Opus 5 (Anthropic). Intelligence index 45.3 vs 63.1; coding index 59.4 vs 78.0; output speed 60 vs 52 tokens per second; time to first token 1.4s vs 31s; output price $0.87 vs $25.00 per million tokens; input price $0.435 vs $5.00 per million tokens. franklineh.com
DeepSeek V4 Pro vs Claude Opus 5: head-to-head AI benchmark comparison. DeepSeek V4 Pro leads on output speed, time to first token, output price and input price; Claude Opus 5 leads on intelligence index and coding index.
Head to headUpdated

DeepSeek V4 Pro vs. Claude Opus 5: A Comparative Analysis

This analysis compares the DeepSeek V4 Pro and Claude Opus 5, evaluating their performance metrics, cost structures, and operational speeds to help users determine the optimal model for their specific reasoning and coding requirements.

Pick it for DeepSeek V4 Pro · Reasoning, Max Effort

  • Latency-sensitive chat, support, and interactive product flows
  • Longer responses where sustained output speed matters
  • Higher-volume workloads where blended token cost matters

Pick it for Claude Opus 5 · Adaptive Reasoning, Max Effort

  • Workloads that benefit from the stronger overall intelligence score
  • Coding and agentic tasks where the benchmark edge matters
  • Teams already standardized on Anthropic

By the numbers

These figures describe the two model configurations shown here. A dash means the source snapshot had no usable figure for that metric. Scores, speed and API pricing may change as providers update models.

MetricDeepSeek V4 Pro (Reasoning, Max Effort)Claude Opus 5 (Adaptive Reasoning, Max Effort)
Intelligence Index45.363.1
Coding Index59.478.0
Input price (per 1M tokens)$0.435$5.00
Output price (per 1M tokens)$0.87$25.00
Output speed (tokens/s)6052
Time to first token1.4s31s
Release date2026-04-242026-07-24

Understanding the Benchmarks

The performance gap between DeepSeek V4 Pro and Claude Opus 5 is evident across most standardized evaluations. Claude Opus 5, released in July 2026, holds a clear lead in the intelligence index at 63.1 compared to DeepSeek’s 45.3. This advantage translates into higher scores across key benchmarks, including GPQA (0.932 vs 0.888), HLE (0.549 vs 0.375), and LCR (0.757 vs 0.700). Claude Opus 5 also demonstrates superior coding capabilities, with a coding index of 78 against DeepSeek’s 59.4. While both models provide robust reasoning, the data suggests that Claude Opus 5 is better suited for tasks requiring deeper logical synthesis and complex problem-solving, whereas DeepSeek V4 Pro remains a highly capable, albeit slightly less intensive, reasoning tool.

Speed and Cost Trade-offs

The operational profiles of these two models present a stark contrast in efficiency. DeepSeek V4 Pro is engineered for speed, delivering an output rate of 59.866 tokens per second with a rapid time-to-first-token of 1.429 seconds. This makes it exceptionally responsive for interactive applications. In contrast, Claude Opus 5 exhibits a significantly slower time-to-first-token of 31.474 seconds and a lower output speed of 51.797 tokens per second.

Financial considerations further widen the gap between the two. DeepSeek V4 Pro offers a highly competitive blended pricing of $0.54 per million tokens. Claude Opus 5, positioned as a premium frontier model, commands a blended price of $10.00 per million tokens. Users must weigh whether the incremental gains in intelligence and coding accuracy provided by Claude Opus 5 justify a cost that is roughly 18 times higher than that of the DeepSeek V4 Pro.

Aligning Models with Workflows

Determining the right model depends heavily on the nature of the user's workflow. DeepSeek V4 Pro excels in environments where latency is a primary constraint, such as real-time coding assistants, high-volume data processing, or conversational interfaces where user experience is tied to immediate feedback. Its cost-efficiency allows for extensive usage without the budgetary pressures associated with premium models.

Claude Opus 5 is best reserved for high-stakes, complex reasoning tasks where the model’s superior intelligence index and benchmark performance can provide a tangible advantage. This includes architectural planning, advanced scientific research, or complex code refactoring where the cost of a mistake is high and the time-to-first-token is less critical than the quality of the final output. The model’s performance in the HLE and SciCode benchmarks suggests it is better equipped to handle nuanced, multi-step logical chains that might overwhelm less specialized models.

Decision Takeaway

Ultimately, the decision rests on the specific requirements of the project. If the priority is maintaining a high-velocity, cost-effective pipeline, DeepSeek V4 Pro provides a compelling balance of speed and capability. If the project demands the highest possible reasoning accuracy and the budget allows for premium pricing, Claude Opus 5 is the more robust choice for complex, mission-critical operations.

Frequently asked questions

Is Claude Opus 5 Adaptive Reasoning better than DeepSeek V4 Pro?

Not across the board: Claude Opus 5 Adaptive Reasoning scores higher on the intelligence index, 63.1 to 45.3; DeepSeek V4 Pro is 95% cheaper on blended price; and DeepSeek V4 Pro streams output 1.2 times as fast.

When were Claude Opus 5 Adaptive Reasoning and DeepSeek V4 Pro released?

Claude Opus 5 Adaptive Reasoning is newer. It was released on July 24, 2026, about 3 months after DeepSeek V4 Pro (April 24, 2026).

Who makes Claude Opus 5 Adaptive Reasoning and DeepSeek V4 Pro?

Claude Opus 5 Adaptive Reasoning is made by Anthropic and DeepSeek V4 Pro by DeepSeek. Claude Opus 5 Adaptive Reasoning was released on July 24, 2026 and DeepSeek V4 Pro on April 24, 2026.

Which is faster, Claude Opus 5 Adaptive Reasoning or DeepSeek V4 Pro?

DeepSeek V4 Pro generates output faster, at 60 tokens per second against 52 tokens per second. DeepSeek V4 Pro reaches its first token sooner (1.4 seconds against 31 seconds).

Which is cheaper, Claude Opus 5 Adaptive Reasoning or DeepSeek V4 Pro?

DeepSeek V4 Pro is cheaper on a blended basis. Claude Opus 5 Adaptive Reasoning lists $5.00 per million input tokens and $25.00 per million output tokens; DeepSeek V4 Pro lists $0.435 and $0.87. For 1 million input and 200,000 output tokens that is $10.00 against $0.61.

Final whistle

The choice between these models hinges on the trade-off between latency and raw intelligence. DeepSeek V4 Pro is the superior choice for high-throughput, cost-sensitive applications where rapid response times are critical. Conversely, Claude Opus 5 serves as a high-performance engine for complex, non-time-sensitive tasks where maximum reasoning depth and accuracy are non-negotiable, despite the significantly higher cost and increased initial latency.

Where the numbers come from

The scores, speed and prices in this comparison come from independent third-party model evaluations that Franklin AI syncs each day, and the article was written from a snapshot of them. For the latest results, open the DeepSeek V4 Pro (Reasoning, Max Effort) and Claude Opus 5 (Adaptive Reasoning, Max Effort) pages. The AI Benchmark methodology explains how that data is collected and shown.

Comments (0)

No comments yet

Be the first to share your thoughts!