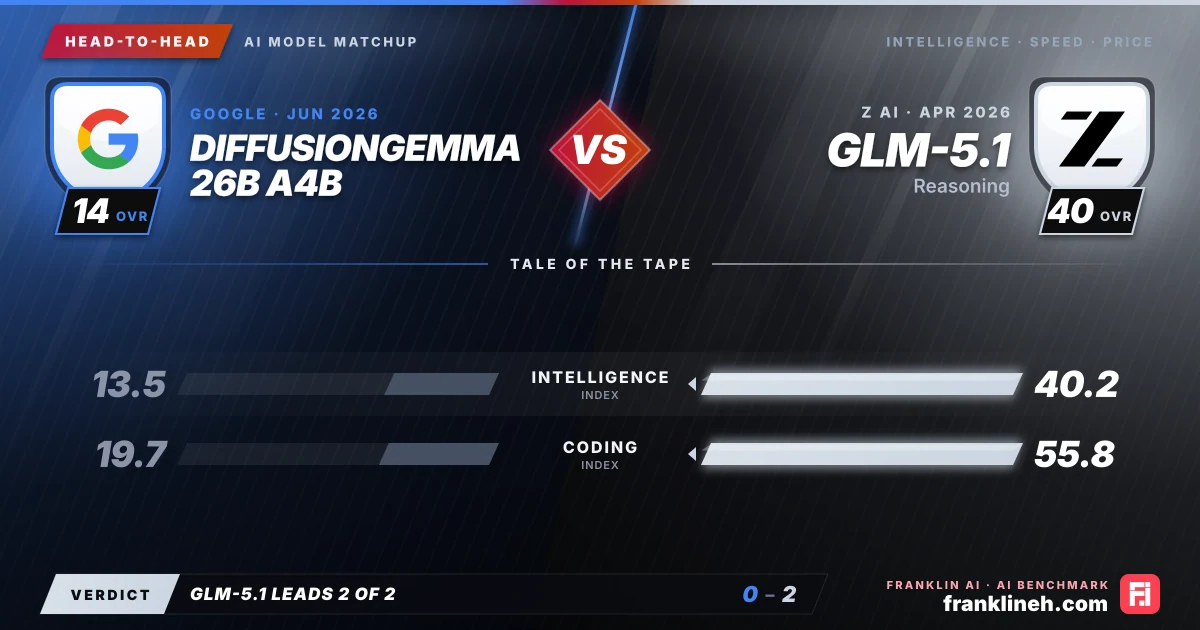
GLM-5.1 (Reasoning) significantly outperforms DiffusionGemma 26B A4B across all intelligence and coding metrics, offering superior reasoning capabilities despite its associated costs, whereas DiffusionGemma provides a free-to-use alternative for users prioritizing zero-cost access over high-performance benchmarks.
Pick it for DiffusionGemma 26B A4B
Zero-cost experimental projects
Budget-constrained environments
General-purpose low-stakes tasks
Pick it for GLM-5.1 · Reasoning
Complex reasoning and coding
Production environments requiring speed
High-accuracy analytical workflows
By the numbers
These figures describe the two model configurations shown here. A dash means the source snapshot had no usable figure for that metric. Scores, speed and API pricing may change as providers update models.
This comparison evaluates Google’s DiffusionGemma 26B A4B, released on June 10, 2026, against Z AI’s GLM-5.1 (Reasoning), released on April 7, 2026. While DiffusionGemma offers a unique zero-cost pricing structure, GLM-5.1 dominates in intelligence, coding, and benchmark performance.
Benchmark Read
GLM-5.1 (Reasoning) consistently outperforms DiffusionGemma 26B A4B across all shared metrics:
GPQA: 0.868 (GLM) vs 0.669 (DiffusionGemma)
HLE: 0.28 (GLM) vs 0.102 (DiffusionGemma)
SciCode: 0.438 (GLM) vs 0.343 (DiffusionGemma)
IFBench: 0.763 (GLM) vs 0.595 (DiffusionGemma)
LCR: 0.623 (GLM) vs 0.143 (DiffusionGemma)
Additionally, GLM-5.1 demonstrates high proficiency in specialized tasks, scoring 0.432 on TerminalBench Hard and 0.977 on TAU2. Math index data remains unknown for both models.
Cost and Speed
DiffusionGemma 26B A4B: This model is free to use, with input, output, and blended costs all listed at $0.00/1M tokens. Performance metrics, including output speed and time to first token, are currently unknown.
GLM-5.1 (Reasoning): This is a paid model costing $1.40/1M for input and $4.40/1M for output, resulting in a blended cost of $2.15/1M. It provides transparent performance data, featuring an output speed of 70.022 tok/s and a time to first token of 0.887s.
Best Fit
GLM-5.1 is designed for high-performance reasoning and coding tasks where speed and accuracy are critical. Its benchmark profile suggests it is well-suited for complex problem-solving. DiffusionGemma 26B A4B serves as a cost-effective solution for users who require a functional model without financial overhead, though users should be prepared for lower performance ceilings.
Quick answers
Is GLM-5.1 Reasoning better than DiffusionGemma 26B A4B?
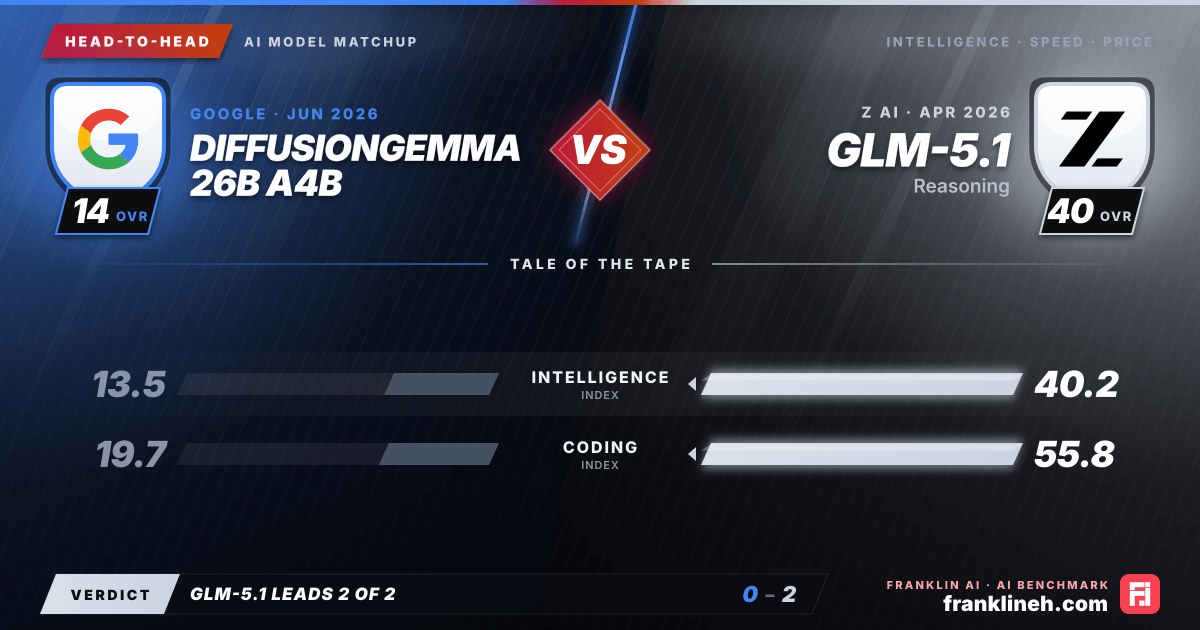
Where the data separates them, GLM-5.1 Reasoning is ahead each time: GLM-5.1 Reasoning scores higher on the intelligence index, 40.2 to 13.5.
Which is newer, DiffusionGemma 26B A4B or GLM-5.1 Reasoning?
DiffusionGemma 26B A4B is newer. It was released on June 10, 2026, about 2 months after GLM-5.1 Reasoning (April 7, 2026).
Is DiffusionGemma 26B A4B or GLM-5.1 Reasoning better at coding?
GLM-5.1 Reasoning has the higher coding index, 55.8 against 19.7.
Are DiffusionGemma 26B A4B and GLM-5.1 Reasoning from the same company?
DiffusionGemma 26B A4B is made by Google and GLM-5.1 Reasoning by Z AI. DiffusionGemma 26B A4B was released on June 10, 2026 and GLM-5.1 Reasoning on April 7, 2026.
Final whistle
For professional applications requiring high reasoning, complex coding, and reliable speed, GLM-5.1 (Reasoning) is the clear choice. Its superior benchmark performance across all tested categories justifies its pricing. DiffusionGemma 26B A4B is best suited for experimental or low-stakes tasks where budget constraints are the primary concern, as it lacks the performance depth and speed metrics of the GLM-5.1 model.
Where the numbers come from
The scores, speed and prices in this comparison come from independent third-party model evaluations that Franklin AI syncs each day, and the article was written from a snapshot of them. For the latest results, open the DiffusionGemma 26B A4B and GLM-5.1 (Reasoning) pages. The AI Benchmark methodology explains how that data is collected and shown.

Comments (0)
to join the discussion
No comments yet
Be the first to share your thoughts!