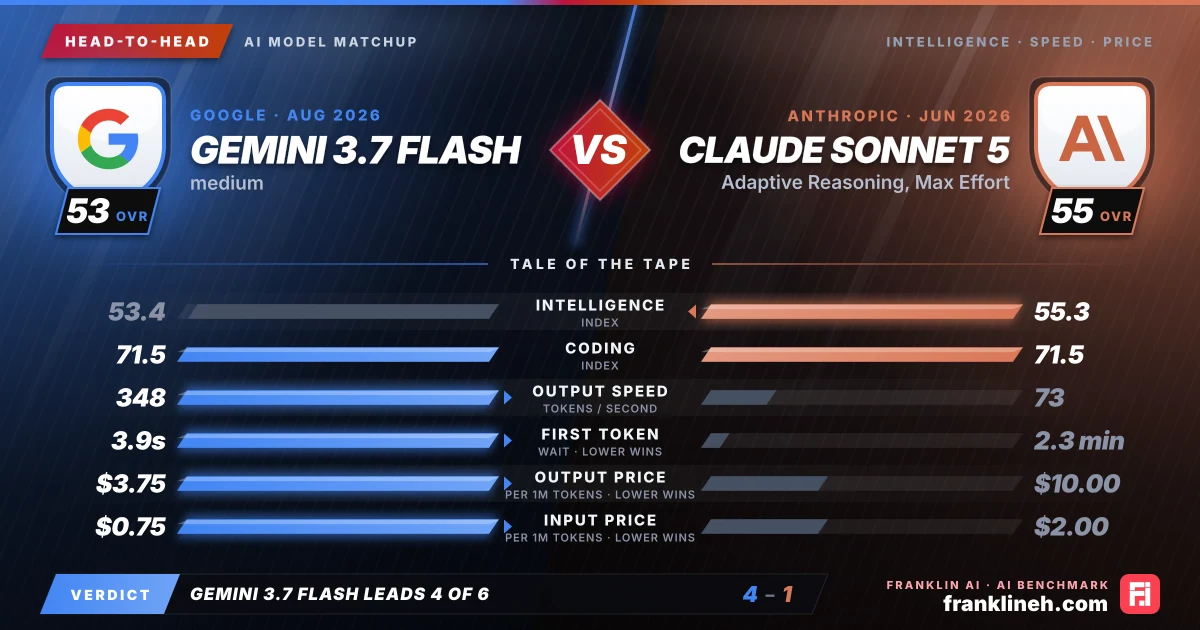
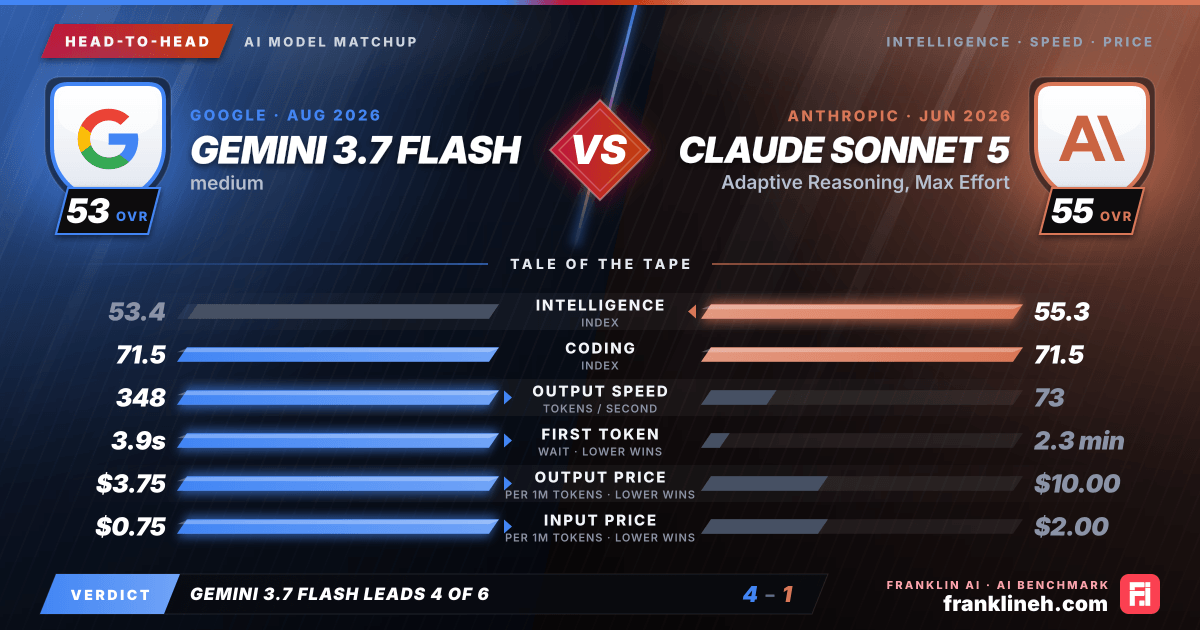
Head-to-head AI model comparison graphic: Gemini 3.7 Flash (Google) vs Claude Sonnet 5 (Anthropic). Intelligence index 53.4 vs 55.3; coding index 71.5 vs 71.5; output speed 348 vs 73 tokens per second; time to first token 3.9s vs 2.3 min; output price $3.75 vs $10.00 per million tokens; input price $0.75 vs $2.00 per million tokens. franklineh.com
Gemini 3.7 Flash vs Claude Sonnet 5: head-to-head AI benchmark comparison. Gemini 3.7 Flash leads on output speed, time to first token, output price and input price; Claude Sonnet 5 leads on intelligence index; level on coding index.
Head to headUpdated

Gemini 3.7 Flash vs. Claude Sonnet 5: Balancing Speed and Reasoning

This comparison evaluates the Gemini 3.7 Flash and Claude Sonnet 5 (Adaptive Reasoning, Max Effort) models. While both offer identical coding capabilities, they diverge significantly in architectural philosophy, balancing Google’s focus on high-speed agentic throughput against Anthropic’s emphasis on deep, deliberate reasoning performance.

Pick it for Gemini 3.7 Flash · Medium

  • Latency-sensitive chat, support, and interactive product flows
  • Longer responses where sustained output speed matters
  • Higher-volume workloads where blended token cost matters

Pick it for Claude Sonnet 5 · Adaptive Reasoning, Max Effort

  • Workloads that benefit from the stronger overall intelligence score
  • Teams already standardized on Anthropic
  • Use cases where its strongest benchmark rows map to the workload

By the numbers

These figures describe the two model configurations shown here. A dash means the source snapshot had no usable figure for that metric. Scores, speed and API pricing may change as providers update models.

MetricGemini 3.7 Flash (medium)Claude Sonnet 5 (Adaptive Reasoning, Max Effort)
Intelligence Index53.455.3
Coding Index71.571.5
Input price (per 1M tokens)$0.75$2.00
Output price (per 1M tokens)$3.75$10.00
Output speed (tokens/s)34873
Time to first token3.9s2.3 min
Release date2026-08-132026-06-30

What the Benchmarks Show

When evaluating the raw intelligence and technical proficiency of these two models, the data reveals a nuanced trade-off. Claude Sonnet 5 holds a slight edge in general intelligence, with an index of 55.3 compared to Gemini 3.7 Flash’s 53.4. This is reflected in the HLE benchmark, where Claude scores 0.413 against Gemini’s 0.39. However, the models reach parity in coding proficiency, both recording an identical coding index of 71.5.

In specialized scientific and reasoning tasks, the results are mixed. Gemini 3.7 Flash demonstrates superior performance in the GPQA benchmark (0.921 vs. 0.911) and the SciCode benchmark (0.579 vs. 0.536), suggesting that despite a lower general intelligence index, it is highly optimized for complex scientific inquiry and code-based problem solving. Claude maintains a slight advantage in the LCR benchmark, scoring 0.77 compared to Gemini’s 0.81, indicating that performance variations are highly dependent on the specific nature of the prompt rather than a blanket superiority of one model over the other.

Speed and Cost

The most striking difference between these models lies in their operational efficiency. Gemini 3.7 Flash is engineered for high-velocity environments, delivering an output speed of 347.826 tokens per second with a time-to-first-token of just 3.87 seconds. This makes it exceptionally responsive for interactive applications. In contrast, Claude Sonnet 5, specifically in its Adaptive Reasoning Max Effort mode, prioritizes depth over speed. It delivers output at 73.033 tokens per second, with a significant time-to-first-token of 137.232 seconds, which may be prohibitive for real-time user interfaces.

This performance gap is mirrored in the pricing structure. Gemini 3.7 Flash is significantly more economical, with a blended cost of $1.50 per million tokens. Claude Sonnet 5 commands a premium, with a blended cost of $4.00 per million tokens. Users must decide if the specific reasoning advantages of the Claude architecture provide enough value to justify paying nearly three times the cost of the Gemini model.

Which Model Fits Which Workflow

Determining the right model requires an assessment of your specific operational constraints. Gemini 3.7 Flash is designed for agentic workflows where the model must act as a rapid intermediary, processing large volumes of data or maintaining a fluid conversation with a user. Its low latency and lower cost profile make it ideal for scaling applications where budget and speed are primary constraints.

Claude Sonnet 5 is better positioned for high-stakes, analytical workflows. The "Max Effort" reasoning mode suggests a model designed to take its time to ensure accuracy and logical consistency. While the latency is high, the model’s design is intended for tasks where the cost of an error is high and the time taken to reach a conclusion is secondary to the quality of the reasoning provided. It is a tool for deep-dive research, complex architectural planning, and high-level synthesis where the user can afford to wait for a more deliberate output.

Quick answers

Is Claude Sonnet 5 Adaptive Reasoning better than Gemini 3.7 Flash medium?

Neither wins everywhere: Claude Sonnet 5 Adaptive Reasoning scores higher on the intelligence index, 55.3 to 53.4; Gemini 3.7 Flash medium is 63% cheaper on blended price; and Gemini 3.7 Flash medium streams output 4.8 times as fast.

Is Claude Sonnet 5 Adaptive Reasoning or Gemini 3.7 Flash medium better at coding?

Their coding index scores are level at 71.5 and 71.5.

When were Claude Sonnet 5 Adaptive Reasoning and Gemini 3.7 Flash medium released?

Gemini 3.7 Flash medium is newer. It was released on August 13, 2026, 44 days after Claude Sonnet 5 Adaptive Reasoning (June 30, 2026).

Who makes Claude Sonnet 5 Adaptive Reasoning and Gemini 3.7 Flash medium?

Claude Sonnet 5 Adaptive Reasoning is made by Anthropic and Gemini 3.7 Flash medium by Google. Claude Sonnet 5 Adaptive Reasoning was released on June 30, 2026 and Gemini 3.7 Flash medium on August 13, 2026.

Which model has lower latency?

Gemini 3.7 Flash medium generates output faster, at 348 tokens per second against 73 tokens per second. Gemini 3.7 Flash medium reaches its first token sooner (3.9 seconds against 2.3 minutes).

Final whistle

The choice between these models depends on your tolerance for latency. Gemini 3.7 Flash is the clear winner for high-volume, real-time agentic workflows where speed is a functional requirement. Conversely, Claude Sonnet 5 is better suited for complex, non-time-sensitive tasks where the higher intelligence index and nuanced reasoning capabilities justify the increased cost and significant wait times. If your application requires rapid iteration, Gemini is the superior choice; for deep analysis, lean toward Claude.

Where the numbers come from

The scores, speed and prices in this comparison come from independent third-party model evaluations that Franklin AI syncs each day, and the article was written from a snapshot of them. For the latest results, open the Gemini 3.7 Flash (medium) and Claude Sonnet 5 (Adaptive Reasoning, Max Effort) pages. The AI Benchmark methodology explains how that data is collected and shown.

Comments (0)

No comments yet

Be the first to share your thoughts!