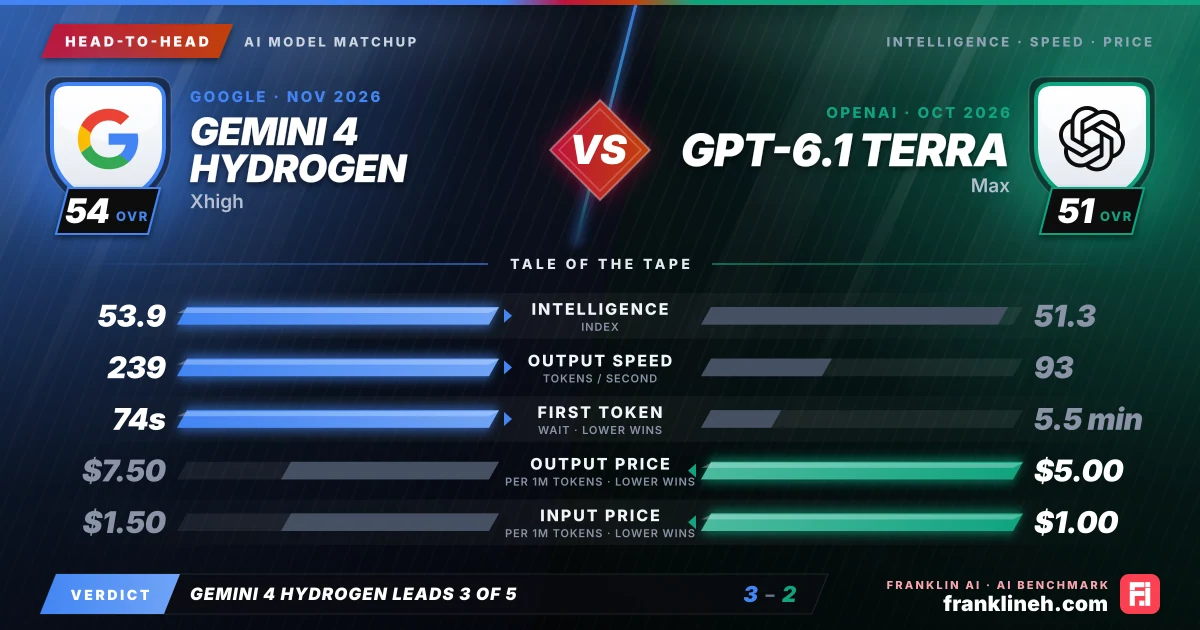
Gemini 4 Hydrogen vs GPT-6.1 Terra: head-to-head AI benchmark comparison. Gemini 4 Hydrogen leads on intelligence index, output speed and time to first token; GPT-6.1 Terra leads on output price and input price.
Gemini 4 Hydrogen (Xhigh) vs GPT-6.1 Terra (Max): Hydrogen has the higher captured score and throughput; Terra lists lower token rates.
Pick it for Gemini 4 Hydrogen · Xhigh
Trial Hydrogen when start time and output rate are material.
Pick it for GPT-6.1 Terra · Max
Check Terra’s lower token rates on work without a tight deadline.
By the numbers
These figures describe the two model configurations shown here. A dash means the source snapshot had no usable figure for that metric. Scores, speed and API pricing may change as providers update models.
Terra trades slower measured output for lower rates
Hydrogen leads on the aggregate index and in both captured timing measures. Terra lists lower input and output rates. A lower price per million tokens can still matter for work that does not need a quick response. Gemini 4 Hydrogen lists $1.5 input and $7.5 output, and GPT-6.1 Terra lists $1 input and $5 output per million tokens.
What to measure on your workload
Test a fixed workload with the same completion criteria. Count input and output separately and measure the time to finish each accepted answer. That will show whether the rate difference matters more than the response timing in your application.
Timing and benchmark data
How long does each variant take to start responding?
The snapshot records 74.03 seconds for Gemini 4 Hydrogen (Xhigh) and 328.55 seconds for GPT-6.1 Terra (Max).
What is the measured output speed?
The snapshot records 239.34 tokens per second for Gemini 4 Hydrogen (Xhigh) and 92.75 tokens per second for GPT-6.1 Terra (Max).
What release dates does the benchmark record list?
The recorded release dates are 2026-11-12 for Gemini 4 Hydrogen (Xhigh) and 2026-10-26 for GPT-6.1 Terra (Max).
Are separate coding and math indices available?
The captured records do not report a standalone coding or math index for either setting.
Final whistle
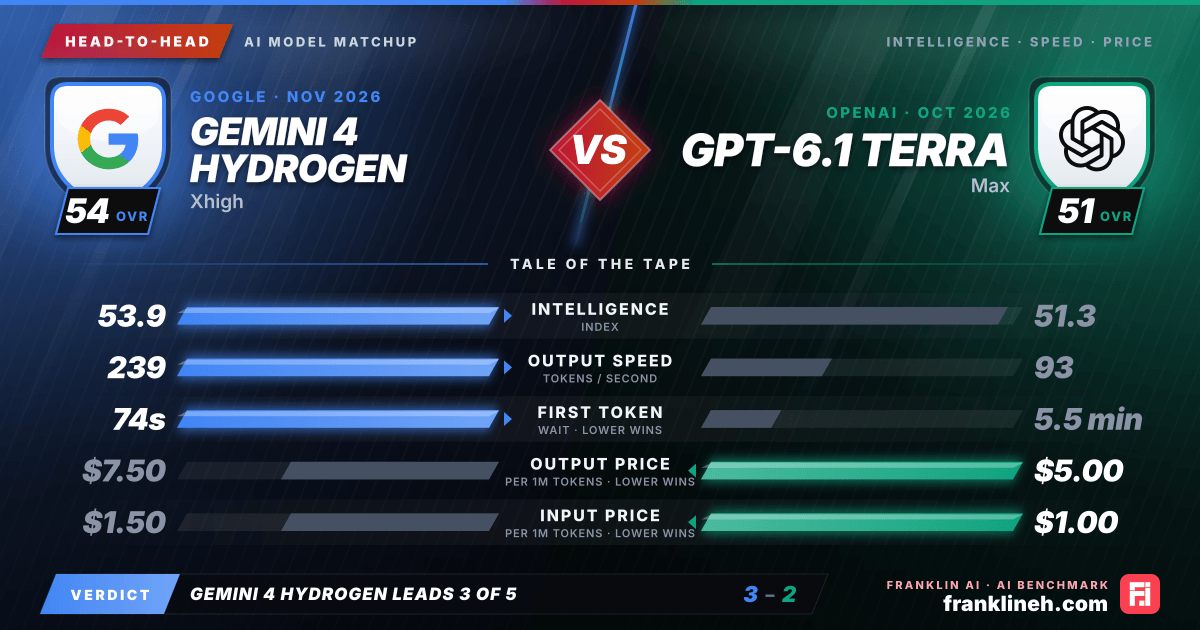
Hydrogen leads on the aggregate index and in both captured timing measures. Terra lists lower input and output rates. A lower price per million tokens can still matter for work that does not need a quick response.
Where the numbers come from
The scores, speed and prices in this comparison come from independent third-party model evaluations that Franklin AI syncs each day, and the article was written from a snapshot of them. For the latest results, open the Gemini 4 Hydrogen (Xhigh) and GPT-6.1 Terra (Max) pages. The AI Benchmark methodology explains how that data is collected and shown.

Comments (0)
to join the discussion
No comments yet
Be the first to share your thoughts!