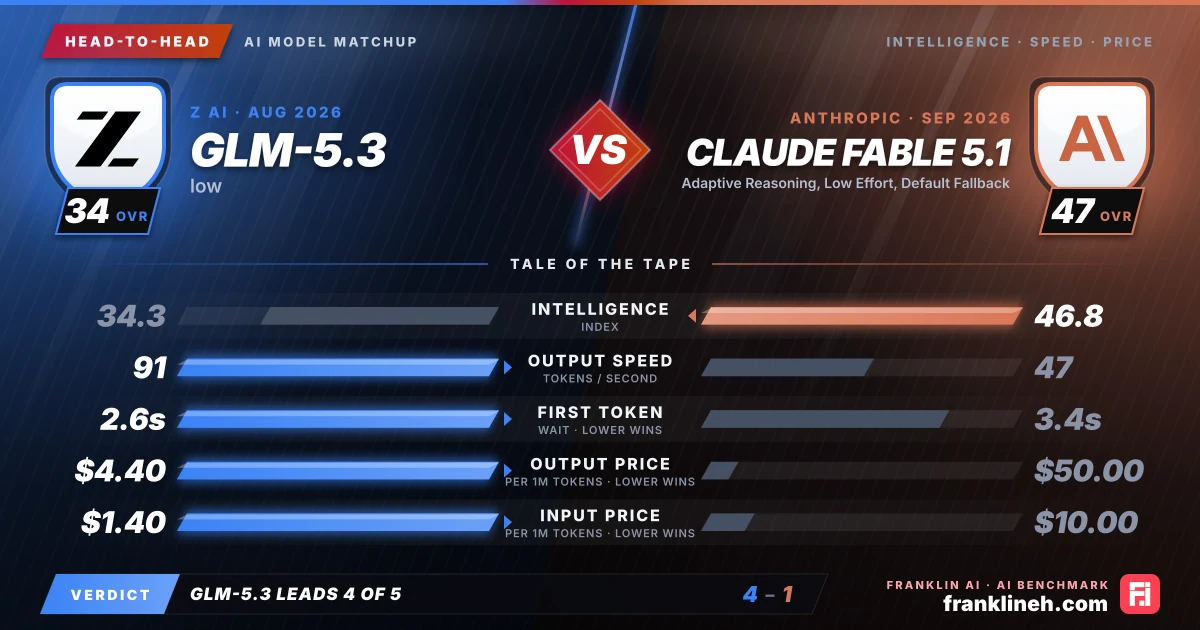
Head-to-head AI model comparison graphic: GLM-5.3 (Z AI) vs Claude Fable 5.1 (Anthropic). Intelligence index 34.3 vs 46.8; output speed 91 vs 47 tokens per second; time to first token 2.6s vs 3.4s; output price $4.40 vs $50.00 per million tokens; input price $1.40 vs $10.00 per million tokens. franklineh.com
GLM-5.3 vs Claude Fable 5.1: head-to-head AI benchmark comparison. GLM-5.3 leads on output speed, time to first token, output price and input price; Claude Fable 5.1 leads on intelligence index.
Head to headUpdated

GLM-5.3 vs. Claude Fable 5.1: Balancing Efficiency and Reasoning

This comparison evaluates the GLM-5.3 (low) and Claude Fable 5.1, analyzing their performance, cost structures, and benchmark capabilities to help users determine which model best aligns with their specific operational requirements and computational constraints.

Pick it for GLM-5.3 · Low

  • Latency-sensitive chat, support, and interactive product flows
  • Longer responses where sustained output speed matters
  • Higher-volume workloads where blended token cost matters

Pick it for Claude Fable 5.1 · Adaptive Reasoning, Low Effort, Default Fallback

  • Workloads that benefit from the stronger overall intelligence score
  • Coding and agentic tasks where the benchmark edge matters
  • Teams already standardized on Anthropic

By the numbers

These figures describe the two model configurations shown here. A dash means the source snapshot had no usable figure for that metric. Scores, speed and API pricing may change as providers update models.

MetricGLM-5.3 (low)Claude Fable 5.1 (Adaptive Reasoning, Low Effort, Default Fallback)
Intelligence Index34.346.8
Coding Index–75.2
Input price (per 1M tokens)$1.40$10.00
Output price (per 1M tokens)$4.40$50.00
Output speed (tokens/s)9147
Time to first token2.6s3.4s
Release date2026-08-182026-09-01

What the benchmarks show

When evaluating the raw capability of these two models, the divergence in their design goals becomes apparent. Claude Fable 5.1 holds a significant advantage in intelligence, posting an index score of 46.8 compared to GLM-5.3’s 34.3. This gap is reflected in the benchmark results, where Claude consistently outperforms GLM-5.3 across all shared metrics. Specifically, Claude achieves an HLE score of 0.489 against GLM-5.3’s 0.366, and a SciCode score of 0.567 versus 0.42. Furthermore, Claude’s coding index of 75.2 suggests a specialized proficiency in software development tasks that GLM-5.3 does not explicitly claim. While GLM-5.3 maintains a respectable LCR score of 0.726, it falls short of Claude’s 0.823, indicating that Claude is better suited for tasks requiring nuanced logical deduction and complex reasoning.

Speed and cost

The economic and performance profiles of these models present a classic trade-off between throughput and capability. GLM-5.3 is optimized for speed and affordability, delivering an output speed of 90.644 tokens per second with a time-to-first-token of 2.596 seconds. This makes it highly responsive for real-time applications. Financially, it is significantly more accessible, with a blended cost of $2.15 per million tokens. In contrast, Claude Fable 5.1 operates at a more measured pace, with an output speed of 47.308 tokens per second and a time-to-first-token of 3.398 seconds. The cost structure for Claude is substantially higher, at $20.00 per million tokens blended, reflecting the increased computational resources required to support its advanced reasoning capabilities.

Which model fits which workflow

Determining the appropriate model requires an assessment of the specific demands of the workload. GLM-5.3 is best utilized in environments where high-volume, repetitive tasks are the norm. Its low latency and cost-efficiency make it an ideal candidate for simple data extraction, high-frequency conversational interfaces, or large-scale content processing where the marginal utility of higher intelligence does not justify the increased expense. It is a workhorse model designed for scale.

Claude Fable 5.1, however, is designed for high-stakes, cognitively demanding workflows. Its superior intelligence and coding benchmarks make it the preferred choice for complex software engineering, technical research, and nuanced analysis where errors are costly. While the latency and pricing are higher, the model’s ability to handle intricate logical structures provides a necessary safety net for professional-grade output. Anthropic’s recent focus on autonomous alignment and model development suggests that Fable 5.1 benefits from a robust research-backed architecture, further justifying its use in critical development environments.

Decision takeaway

Ultimately, the decision rests on whether your project requires raw reasoning power or operational efficiency. If the objective is to minimize cost while maintaining a high volume of output, GLM-5.3 provides a compelling value proposition. If the objective is to maximize the quality of complex outputs, particularly in coding or technical domains, the investment in Claude Fable 5.1 is warranted. Organizations should consider a hybrid approach, utilizing GLM-5.3 for standard interactions while routing complex queries to Claude Fable 5.1 to optimize both performance and budget.

Common questions about Claude Fable 5.1 Adaptive Reasoning and GLM-5.3 low

Is GLM-5.3 low better than Claude Fable 5.1 Adaptive Reasoning?

Not across the board: Claude Fable 5.1 Adaptive Reasoning scores higher on the intelligence index, 46.8 to 34.3; GLM-5.3 low is 89% cheaper on blended price; and GLM-5.3 low streams output 1.9 times as fast.

Which is better for coding, Claude Fable 5.1 Adaptive Reasoning or GLM-5.3 low?

The catalogue has no coding index for GLM-5.3 low yet, so there is no direct coding comparison. The closest signal is the overall intelligence index, 46.8 for Claude Fable 5.1 Adaptive Reasoning and 34.3 for GLM-5.3 low.

Is GLM-5.3 low cheaper than Claude Fable 5.1 Adaptive Reasoning?

GLM-5.3 low is cheaper on a blended basis. Claude Fable 5.1 Adaptive Reasoning lists $10.00 per million input tokens and $50.00 per million output tokens; GLM-5.3 low lists $1.40 and $4.40. For 1 million input and 200,000 output tokens that is $20.00 against $2.28.

Which model has lower latency?

GLM-5.3 low generates output faster, at 91 tokens per second against 47 tokens per second. GLM-5.3 low reaches its first token sooner (2.6 seconds against 3.4 seconds).

When were Claude Fable 5.1 Adaptive Reasoning and GLM-5.3 low released?

Claude Fable 5.1 Adaptive Reasoning is newer. It was released on September 1, 2026, 14 days after GLM-5.3 low (August 18, 2026).

Final whistle

The choice between these models depends on the priority of the task. GLM-5.3 is an economically superior choice for high-volume, latency-sensitive applications where extreme reasoning depth is not required. Conversely, Claude Fable 5.1 is the clear choice for complex problem-solving and technical tasks where accuracy and reasoning capability outweigh the significantly higher cost. Users should weigh the 9x price difference against the substantial gains in intelligence and coding proficiency offered by Anthropic’s model.

Where the numbers come from

The scores, speed and prices in this comparison come from independent third-party model evaluations that Franklin AI syncs each day, and the article was written from a snapshot of them. For the latest results, open the GLM-5.3 (low) and Claude Fable 5.1 (Adaptive Reasoning, Low Effort, Default Fallback) pages. The AI Benchmark methodology explains how that data is collected and shown.

Comments (0)

No comments yet

Be the first to share your thoughts!