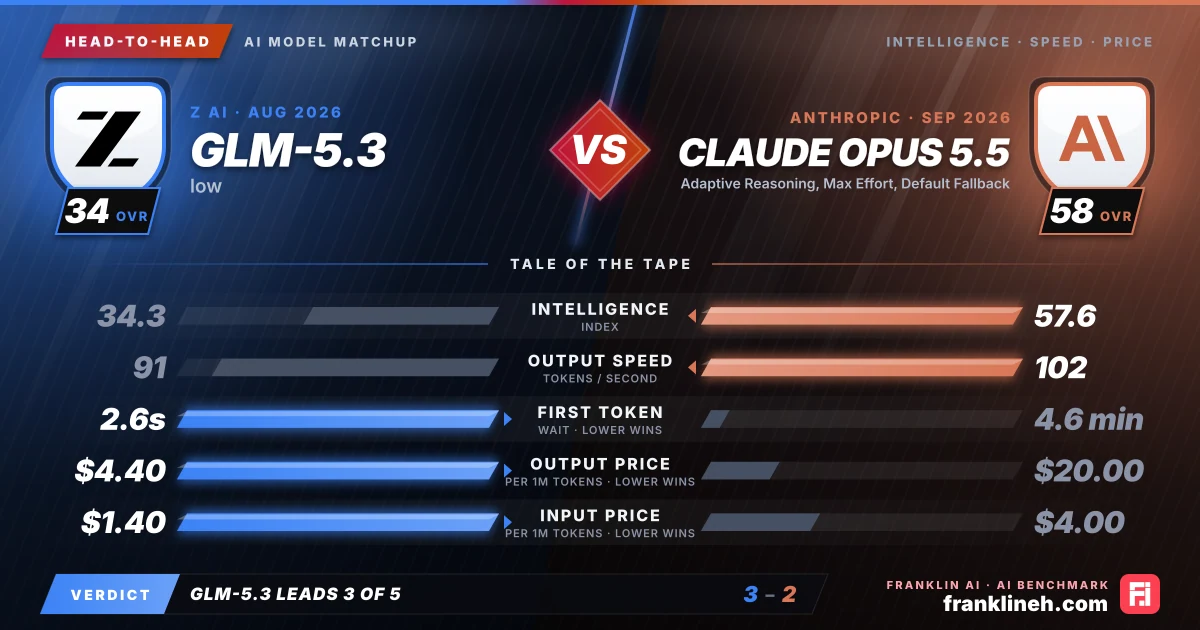
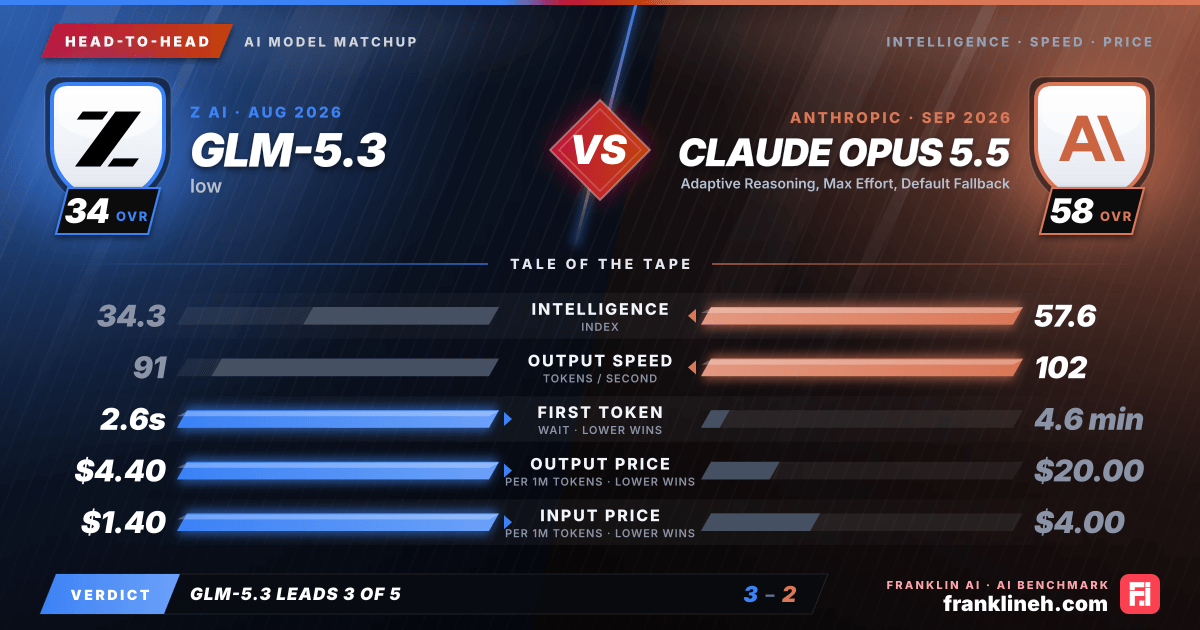
Head-to-head AI model comparison graphic: GLM-5.3 (Z AI) vs Claude Opus 5.5 (Anthropic). Intelligence index 34.3 vs 57.6; output speed 91 vs 102 tokens per second; time to first token 2.6s vs 4.6 min; output price $4.40 vs $20.00 per million tokens; input price $1.40 vs $4.00 per million tokens. franklineh.com
GLM-5.3 vs Claude Opus 5.5: head-to-head AI benchmark comparison. GLM-5.3 leads on time to first token, output price and input price; Claude Opus 5.5 leads on intelligence index and output speed.
Head to headUpdated

GLM-5.3 vs. Claude Opus 5.5: A Comparative Analysis

This comparison evaluates the GLM-5.3 (low) from Z AI and Anthropic’s Claude Opus 5.5. While GLM-5.3 offers significant cost advantages and rapid response times, Claude Opus 5.5 provides superior reasoning capabilities and benchmark performance, presenting a clear trade-off between operational efficiency and high-level cognitive output.

Pick it for GLM-5.3 · Low

  • Latency-sensitive chat, support, and interactive product flows
  • Higher-volume workloads where blended token cost matters
  • Teams already standardized on Z AI

Pick it for Claude Opus 5.5 · Adaptive Reasoning, Max Effort, Default Fallback

  • Workloads that benefit from the stronger overall intelligence score
  • Longer responses where sustained output speed matters
  • Teams already standardized on Anthropic

By the numbers

These figures describe the two model configurations shown here. A dash means the source snapshot had no usable figure for that metric. Scores, speed and API pricing may change as providers update models.

MetricGLM-5.3 (low)Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback)
Intelligence Index34.357.6
Input price (per 1M tokens)$1.40$4.00
Output price (per 1M tokens)$4.40$20.00
Output speed (tokens/s)91102
Time to first token2.6s4.6 min
Release date2026-08-182026-09-22

What the benchmarks show

When evaluating the raw intelligence of these models, Claude Opus 5.5 establishes a clear lead. With an intelligence index of 57.6 compared to GLM-5.3’s 34.3, the Opus 5.5 model demonstrates a higher capacity for complex problem-solving. This is corroborated by the benchmark data: Opus 5.5 achieves an HLE score of 0.614 and a SciCode score of 0.669, significantly outperforming GLM-5.3, which sits at 0.366 and 0.42 respectively. The LCR benchmark follows a similar trend, with Opus 5.5 scoring 0.846 and GLM-5.3 scoring 0.726. These figures suggest that for tasks requiring deep reasoning or scientific computation, Claude Opus 5.5 is the more capable instrument.

Speed and cost

The economic and performance profiles of these models reveal a stark contrast. GLM-5.3 is designed for high-throughput environments, offering a blended price of $2.15 per million tokens, less than a third of the $8.00 per million charged by Claude Opus 5.5. Furthermore, GLM-5.3 is optimized for immediate interaction, boasting a time to first token of 2.596 seconds. In contrast, Claude Opus 5.5 requires 276.865 seconds to produce its first token, which may be prohibitive for real-time applications. While Opus 5.5 does achieve a faster output speed of 101.998 tokens per second compared to GLM-5.3’s 90.644 tokens per second, the initial latency gap makes the Z AI model feel significantly more responsive in conversational or interactive settings.

Which model fits which workflow

Selecting the right model requires balancing the need for raw intelligence against the constraints of your infrastructure. GLM-5.3 is best suited for high-volume, automated workflows where cost-per-token is a primary concern. Its low latency makes it an ideal candidate for customer-facing chatbots, rapid data processing, or any application where the user experience is tied to near-instantaneous feedback. The model’s efficiency allows for scaling operations without a linear increase in budget.

Claude Opus 5.5, despite its high cost and initial latency, is built for heavy-duty cognitive tasks. It is best utilized in scenarios where the accuracy of the output is more valuable than the speed of delivery. This includes complex coding projects, deep research analysis, or strategic planning where the model’s higher intelligence index can prevent errors that might arise from using a less capable model. While the long time to first token is a drawback, the quality of the subsequent output stream makes it a powerful tool for asynchronous, high-stakes tasks.

Decision takeaway

Ultimately, the decision rests on whether your project prioritizes throughput or depth. If you are building a system that requires constant, low-cost interaction, GLM-5.3 provides a reliable and economical foundation. If your work involves nuanced reasoning and the resolution of difficult technical problems, the performance ceiling of Claude Opus 5.5 is worth the investment. Organizations should weigh the cost of potential errors against the cost of inference to determine which model aligns with their specific operational requirements.

Quick answers

Is GLM-5.3 low better than Claude Opus 5.5 Adaptive Reasoning?

It depends on what you need: Claude Opus 5.5 Adaptive Reasoning scores higher on the intelligence index, 57.6 to 34.3; GLM-5.3 low is 73% cheaper on blended price; Claude Opus 5.5 Adaptive Reasoning streams output 1.1 times as fast; and GLM-5.3 low reaches its first token sooner.

Which model has lower latency?

Claude Opus 5.5 Adaptive Reasoning generates output faster, at 102 tokens per second against 91 tokens per second. GLM-5.3 low reaches its first token sooner (2.6 seconds against 4.6 minutes). Counting the first-token wait, GLM-5.3 low finishes first for any reply shorter than about 220,000 tokens.

How much do Claude Opus 5.5 Adaptive Reasoning and GLM-5.3 low cost?

GLM-5.3 low is cheaper on a blended basis. Claude Opus 5.5 Adaptive Reasoning lists $4.00 per million input tokens and $20.00 per million output tokens; GLM-5.3 low lists $1.40 and $4.40. For 1 million input and 200,000 output tokens that is $8.00 against $2.28.

Who makes Claude Opus 5.5 Adaptive Reasoning and GLM-5.3 low?

Claude Opus 5.5 Adaptive Reasoning is made by Anthropic and GLM-5.3 low by Z AI. Claude Opus 5.5 Adaptive Reasoning was released on September 22, 2026 and GLM-5.3 low on August 18, 2026.

Which is newer, Claude Opus 5.5 Adaptive Reasoning or GLM-5.3 low?

Claude Opus 5.5 Adaptive Reasoning is newer. It was released on September 22, 2026, 35 days after GLM-5.3 low (August 18, 2026).

Final whistle

The choice between these models depends on your tolerance for latency and budget constraints. GLM-5.3 is the pragmatic choice for high-volume, cost-sensitive applications where speed is paramount. Conversely, Claude Opus 5.5 is the necessary investment for complex tasks requiring high intelligence and reasoning, despite its significantly higher cost and slower initial response time. If your workflow demands precision over throughput, the performance gains of Opus 5.5 justify the premium.

Where the numbers come from

The scores, speed and prices in this comparison come from independent third-party model evaluations that Franklin AI syncs each day, and the article was written from a snapshot of them. For the latest results, open the GLM-5.3 (low) and Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) pages. The AI Benchmark methodology explains how that data is collected and shown.

Comments (0)

No comments yet

Be the first to share your thoughts!