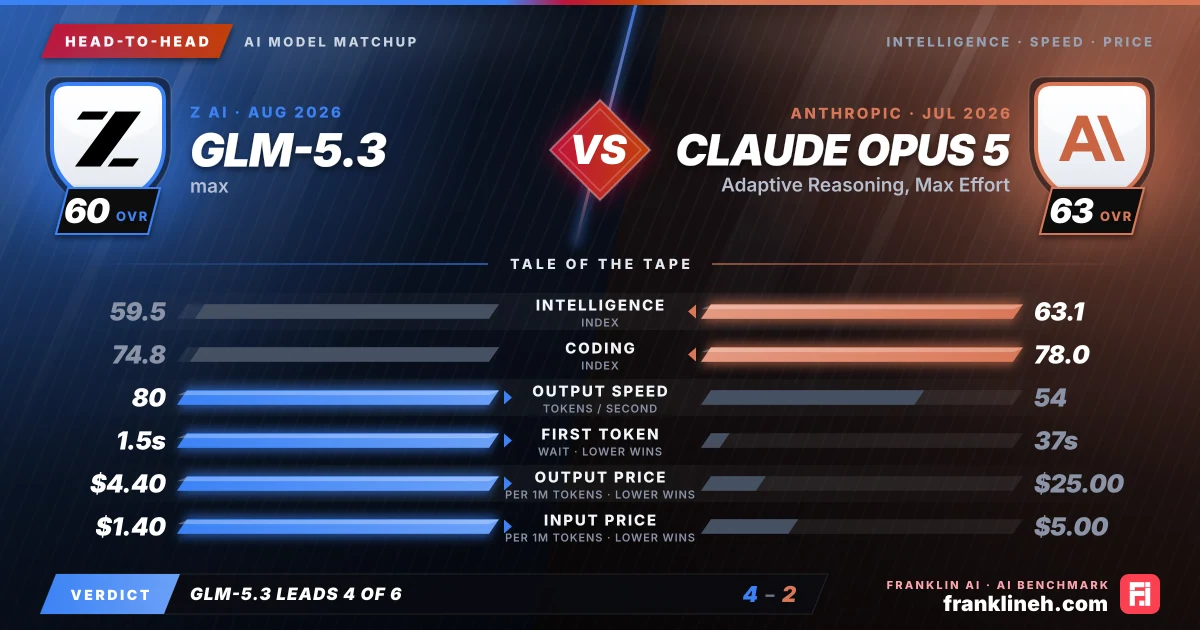
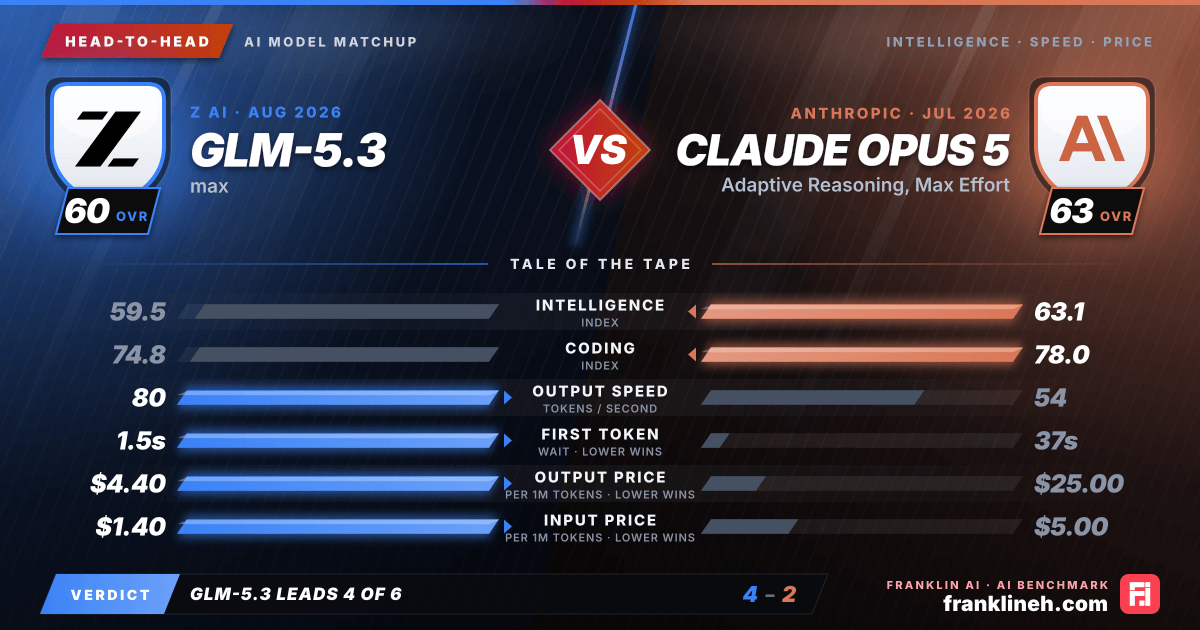
Head-to-head AI model comparison graphic: GLM-5.3 (Z AI) vs Claude Opus 5 (Anthropic). Intelligence index 59.5 vs 63.1; coding index 74.8 vs 78.0; output speed 80 vs 54 tokens per second; time to first token 1.5s vs 37s; output price $4.40 vs $25.00 per million tokens; input price $1.40 vs $5.00 per million tokens. franklineh.com
GLM-5.3 vs Claude Opus 5: head-to-head AI benchmark comparison. GLM-5.3 leads on output speed, time to first token, output price and input price; Claude Opus 5 leads on intelligence index and coding index.
Head to headUpdated

GLM-5.3 (max) vs. Claude Opus 5: A Comparative Analysis

This analysis compares Z AI’s GLM-5.3 (max) and Anthropic’s Claude Opus 5. While Claude Opus 5 leads in raw intelligence and reasoning benchmarks, GLM-5.3 (max) offers superior latency and cost-efficiency, presenting a clear trade-off between peak performance and operational throughput for developers and enterprise users.

Pick it for GLM-5.3 · Max

  • Latency-sensitive chat, support, and interactive product flows
  • Longer responses where sustained output speed matters
  • Higher-volume workloads where blended token cost matters

Pick it for Claude Opus 5 · Adaptive Reasoning, Max Effort

  • Workloads that benefit from the stronger overall intelligence score
  • Coding and agentic tasks where the benchmark edge matters
  • Teams already standardized on Anthropic

By the numbers

These figures describe the two model configurations shown here. A dash means the source snapshot had no usable figure for that metric. Scores, speed and API pricing may change as providers update models.

MetricGLM-5.3 (max)Claude Opus 5 (Adaptive Reasoning, Max Effort)
Intelligence Index59.563.1
Coding Index74.878.0
Input price (per 1M tokens)$1.40$5.00
Output price (per 1M tokens)$4.40$25.00
Output speed (tokens/s)8054
Time to first token1.5s37s
Release date2026-08-182026-07-24

What the benchmarks show

When evaluating the raw intelligence of these two models, Claude Opus 5 consistently edges out GLM-5.3 (max). With an intelligence index of 63.1 compared to GLM-5.3’s 59.5, Claude Opus 5 demonstrates a higher capacity for complex reasoning. This is further reflected in the benchmark data, where Claude Opus 5 achieves a GPQA score of 0.932 and an HLE score of 0.549, outperforming GLM-5.3’s 0.917 and 0.423, respectively. However, the gap narrows in other domains. GLM-5.3 (max) shows surprising strength in coding, with an index of 74.8, and actually leads slightly in the LCR benchmark with a score of 0.763 compared to Claude Opus 5’s 0.756. While both models lack publicly available math index scores, their performance across scientific and reasoning tasks suggests that Claude Opus 5 is better suited for deep, multi-step analytical work, while GLM-5.3 (max) remains a highly competitive alternative for technical and coding-heavy tasks.

Speed and cost

The most significant divergence between these two models lies in their operational profiles. GLM-5.3 (max) is engineered for high-velocity environments, delivering an output speed of 79.593 tokens per second with a time-to-first-token of just 1.507 seconds. This makes it exceptionally responsive for real-time applications. In contrast, Claude Opus 5 is significantly slower, outputting at 54.418 tokens per second with a substantial 36.976-second delay before the first token appears. This latency profile suggests that Claude Opus 5 is optimized for deep, contemplative processing rather than conversational fluidity.

This performance gap is mirrored in the pricing structure. GLM-5.3 (max) is positioned as a high-efficiency model, with a blended cost of $2.15 per million tokens. Claude Opus 5 carries a premium price point, with a blended cost of $10.00 per million tokens—nearly five times the cost of the Z AI model. For organizations processing massive datasets or building high-frequency agentic systems, the cost differential between these two models will likely be the deciding factor.

Which model fits which workflow

Selecting the right model requires balancing the need for deep reasoning against the constraints of your infrastructure. Claude Opus 5 is best suited for complex, non-time-sensitive tasks where accuracy is the primary objective. Its higher intelligence index and benchmark scores suggest it can handle nuanced reasoning that might elude less capable models. It is an ideal "heavy lifter" for research, long-form content generation, or complex logic problems where the 36-second wait time is an acceptable trade-off for higher-quality output.

GLM-5.3 (max) is the superior choice for production environments that require rapid, scalable inference. Its low latency and aggressive pricing make it suitable for customer-facing chatbots, real-time coding assistants, and automated workflows that require high throughput. By prioritizing speed and cost-efficiency, Z AI has created a model that integrates more easily into standard application architectures without the performance bottlenecks inherent in larger, more resource-intensive models like Claude Opus 5.

FAQ

Is GLM-5.3 max better than Claude Opus 5 Adaptive Reasoning?

Neither wins everywhere: Claude Opus 5 Adaptive Reasoning scores higher on the intelligence index, 63.1 to 59.5; GLM-5.3 max is 79% cheaper on blended price; and GLM-5.3 max streams output 1.5 times as fast.

Which model has lower latency?

GLM-5.3 max generates output faster, at 80 tokens per second against 54 tokens per second. GLM-5.3 max reaches its first token sooner (1.5 seconds against 37 seconds).

Is Claude Opus 5 Adaptive Reasoning or GLM-5.3 max better at coding?

Claude Opus 5 Adaptive Reasoning has the higher coding index, 78.0 against 74.8.

Which is cheaper, Claude Opus 5 Adaptive Reasoning or GLM-5.3 max?

GLM-5.3 max is cheaper on a blended basis. Claude Opus 5 Adaptive Reasoning lists $5.00 per million input tokens and $25.00 per million output tokens; GLM-5.3 max lists $1.40 and $4.40. For 1 million input and 200,000 output tokens that is $10.00 against $2.28.

Are Claude Opus 5 Adaptive Reasoning and GLM-5.3 max from the same company?

Claude Opus 5 Adaptive Reasoning is made by Anthropic and GLM-5.3 max by Z AI. Claude Opus 5 Adaptive Reasoning was released on July 24, 2026 and GLM-5.3 max on August 18, 2026.

Final whistle

Choose Claude Opus 5 if your workflow demands the highest possible reasoning capability and benchmark accuracy, regardless of cost or latency. Conversely, GLM-5.3 (max) is the superior choice for high-volume applications where rapid response times and budget constraints are critical. The decision hinges on whether your project requires the absolute ceiling of model intelligence or the agility of a high-speed, cost-effective inference engine.

Where the numbers come from

The scores, speed and prices in this comparison come from independent third-party model evaluations that Franklin AI syncs each day, and the article was written from a snapshot of them. For the latest results, open the GLM-5.3 (max) and Claude Opus 5 (Adaptive Reasoning, Max Effort) pages. The AI Benchmark methodology explains how that data is collected and shown.

Comments (0)

No comments yet

Be the first to share your thoughts!