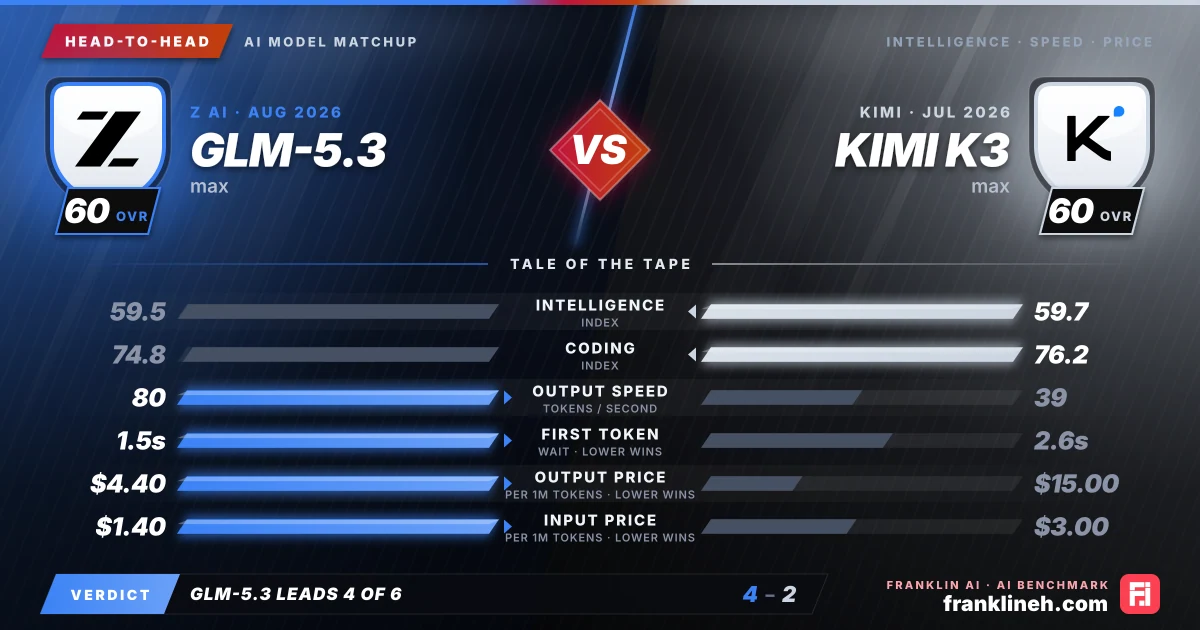
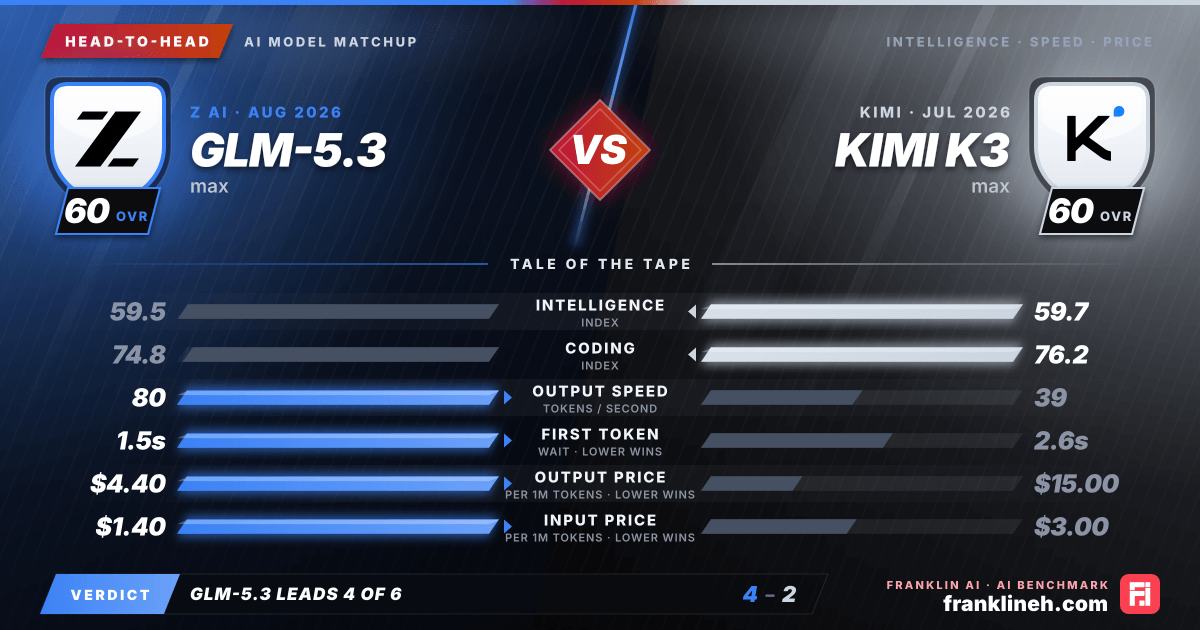
Head-to-head AI model comparison graphic: GLM-5.3 (Z AI) vs Kimi K3 (Kimi). Intelligence index 59.5 vs 59.7; coding index 74.8 vs 76.2; output speed 80 vs 39 tokens per second; time to first token 1.5s vs 2.6s; output price $4.40 vs $15.00 per million tokens; input price $1.40 vs $3.00 per million tokens. franklineh.com
GLM-5.3 vs Kimi K3: head-to-head AI benchmark comparison. GLM-5.3 leads on output speed, time to first token, output price and input price; Kimi K3 leads on intelligence index and coding index.
Head to headUpdated

GLM-5.3 (max) vs. Kimi K3 (max): A Comparative Analysis

This analysis compares the GLM-5.3 (max) and Kimi K3 (max) models, evaluating their performance metrics, cost efficiency, and benchmark results to help users determine which system better aligns with their specific computational and economic requirements.

Pick it for GLM-5.3 · Max

  • Latency-sensitive chat, support, and interactive product flows
  • Longer responses where sustained output speed matters
  • Higher-volume workloads where blended token cost matters

Pick it for Kimi K3 · Max

  • Workloads that benefit from the stronger overall intelligence score
  • Coding and agentic tasks where the benchmark edge matters
  • Teams already standardized on Kimi

By the numbers

These figures describe the two model configurations shown here. A dash means the source snapshot had no usable figure for that metric. Scores, speed and API pricing may change as providers update models.

MetricGLM-5.3 (max)Kimi K3 (max)
Intelligence Index59.559.7
Coding Index74.876.2
Input price (per 1M tokens)$1.40$3.00
Output price (per 1M tokens)$4.40$15.00
Output speed (tokens/s)8039
Time to first token1.5s2.6s
Release date2026-08-182026-07-16

What the Benchmarks Show

The performance landscape between GLM-5.3 (max) and Kimi K3 (max) reveals a tight competition across standardized metrics. Kimi K3 (max) holds a marginal lead in the Intelligence index at 59.7 compared to GLM-5.3’s 59.5, and maintains a higher Coding index of 76.2 versus 74.8. This trend persists across specific academic benchmarks, where Kimi K3 (max) scores 0.935 on GPQA, 0.469 on HLE, 0.587 on SciCode, and 0.826 on LCR. While GLM-5.3 (max) trails slightly in these specific categories—scoring 0.917, 0.423, 0.565, and 0.763 respectively—the differences are relatively narrow. Both models currently lack published data for the Math index, leaving a gap in their comparative assessment for purely quantitative reasoning tasks.

Speed and Cost

Economic and operational efficiency serves as the primary differentiator between these two models. GLM-5.3 (max) is significantly more cost-effective, with a blended pricing of $2.15 per million tokens, compared to the $6.00 per million tokens required for Kimi K3 (max). This pricing disparity is mirrored in the input and output costs, where GLM-5.3 (max) charges $1.40 and $4.40 per million tokens, respectively, while Kimi K3 (max) charges $3.00 and $15.00.

Beyond pricing, operational speed favors GLM-5.3 (max). It delivers an output speed of 79.593 tokens per second with a time to first token of 1.507 seconds. Kimi K3 (max) operates at a lower output speed of 38.637 tokens per second and exhibits a longer latency period, with a time to first token of 2.585 seconds. For applications requiring rapid, high-throughput generation, the performance profile of GLM-5.3 (max) provides a distinct advantage.

Which Model Fits Which Workflow

Selecting the appropriate model requires balancing the need for peak benchmark performance against the constraints of budget and latency. Kimi K3 (max) is better suited for high-stakes development or research environments where the marginal gains in coding and intelligence benchmarks are critical to the project's success. Its higher cost is a reflection of its position as a premium tool for complex, logic-heavy tasks.

GLM-5.3 (max) is optimized for workflows where scale and speed are paramount. Its lower cost structure and faster output speeds make it an excellent candidate for large-scale API integrations, real-time interactive applications, or high-volume data processing tasks where maintaining a lower cost-per-token is essential for project sustainability.

Decision Takeaway

Ultimately, the decision rests on whether your use case demands the absolute highest benchmark scores or a more balanced approach to performance and cost. If your application is latency-sensitive or requires processing massive amounts of data, the efficiency of GLM-5.3 (max) is difficult to overlook. However, if your primary objective is to leverage the most capable reasoning engine available for specialized coding or complex problem-solving, the Kimi K3 (max) model remains the more potent, albeit more expensive, option.

Frequently asked questions

Is GLM-5.3 max better than Kimi K3 max?

GLM-5.3 max comes out ahead on every measure the data separates: they are level on the intelligence index (59.5 and 59.7); GLM-5.3 max is 64% cheaper on blended price; and GLM-5.3 max streams output 2.1 times as fast.

Which is better for coding, GLM-5.3 max or Kimi K3 max?

Kimi K3 max has the higher coding index, 76.2 against 74.8.

How much do GLM-5.3 max and Kimi K3 max cost?

GLM-5.3 max is cheaper on a blended basis. GLM-5.3 max lists $1.40 per million input tokens and $4.40 per million output tokens; Kimi K3 max lists $3.00 and $15.00. For 1 million input and 200,000 output tokens that is $2.28 against $6.00.

Which is faster, GLM-5.3 max or Kimi K3 max?

GLM-5.3 max generates output faster, at 80 tokens per second against 39 tokens per second. GLM-5.3 max reaches its first token sooner (1.5 seconds against 2.6 seconds).

Which is newer, GLM-5.3 max or Kimi K3 max?

GLM-5.3 max is newer. It was released on August 18, 2026, 33 days after Kimi K3 max (July 16, 2026).

Final whistle

The choice between these models depends on your priority: GLM-5.3 (max) offers superior cost-efficiency and faster response times, making it ideal for high-volume production tasks. Conversely, Kimi K3 (max) provides a slight edge in raw intelligence and coding benchmarks, justifying its higher price point for users who require maximum precision in complex reasoning and development workflows. Both models represent significant advancements in current large-scale language modeling.

Where the numbers come from

The scores, speed and prices in this comparison come from independent third-party model evaluations that Franklin AI syncs each day, and the article was written from a snapshot of them. For the latest results, open the GLM-5.3 (max) and Kimi K3 (max) pages. The AI Benchmark methodology explains how that data is collected and shown.

Comments (0)

No comments yet

Be the first to share your thoughts!