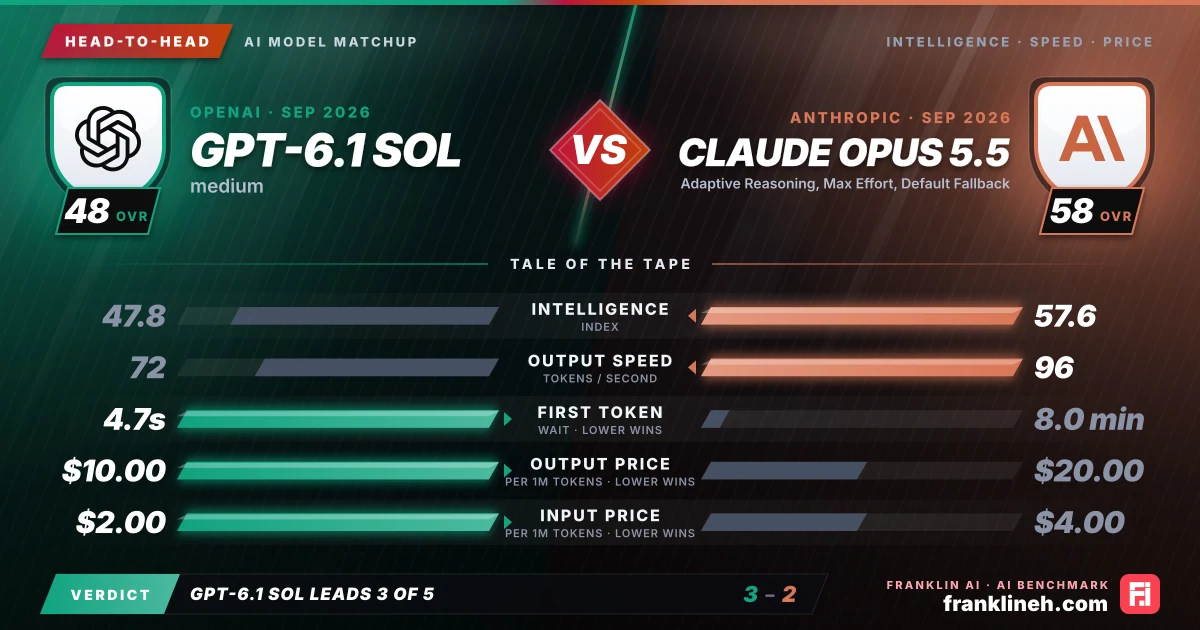
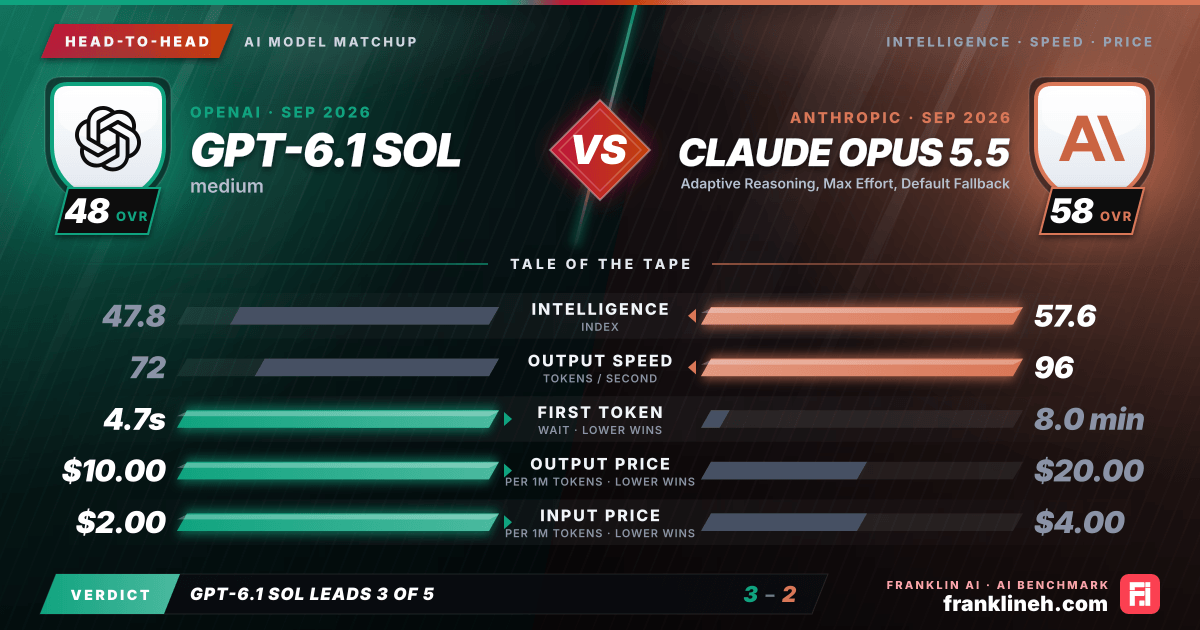
Head-to-head AI model comparison graphic: GPT-6.1 Sol (OpenAI) vs Claude Opus 5.5 (Anthropic). Intelligence index 47.8 vs 57.6; output speed 72 vs 96 tokens per second; time to first token 4.7s vs 8.0 min; output price $10.00 vs $20.00 per million tokens; input price $2.00 vs $4.00 per million tokens. franklineh.com
GPT-6.1 Sol vs Claude Opus 5.5: head-to-head AI benchmark comparison. GPT-6.1 Sol leads on time to first token, output price and input price; Claude Opus 5.5 leads on intelligence index and output speed.
Head to headUpdated

GPT-6.1 Sol (medium) vs Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback)

GPT-6.1 Sol (medium) and Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) are compared across intelligence, coding, math, speed, pricing, and benchmark coverage.

Pick it for GPT-6.1 Sol · Medium

  • Latency-sensitive chat, support, and interactive product flows
  • Higher-volume workloads where blended token cost matters
  • Teams already standardized on OpenAI

Pick it for Claude Opus 5.5 · Adaptive Reasoning, Max Effort, Default Fallback

  • Workloads that benefit from the stronger overall intelligence score
  • Longer responses where sustained output speed matters
  • Teams already standardized on Anthropic

By the numbers

These figures describe the two model configurations shown here. A dash means the source snapshot had no usable figure for that metric. Scores, speed and API pricing may change as providers update models.

MetricGPT-6.1 Sol (medium)Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback)
Intelligence Index47.857.6
Input price (per 1M tokens)$2.00$4.00
Output price (per 1M tokens)$10.00$20.00
Output speed (tokens/s)7296
Time to first token4.7s8.0 min
Release date2026-09-292026-09-22

GPT-6.1 Sol (medium) and Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) serve similar evaluation needs, but the useful difference is not the brand name. It is how the benchmark profile, latency, and token pricing line up with the work a reader actually wants to run.

What the benchmarks show

Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) has the stronger overall benchmark position in Franklin AI's current dataset, with an intelligence index of 57.6 compared with 47.8 for GPT-6.1 Sol (medium). That makes Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) the clearer default when a workflow depends on the highest available reasoning score. The rest of the table still matters, because coding, math, and individual benchmark rows can point to a different choice for narrow use cases.

Speed and cost

Pricing and responsiveness can change the decision even when one model leads on the headline index. A model with a lower blended token cost may be easier to use at scale, while a model with faster first-token response can feel better in interactive products. The benchmark table below keeps those tradeoffs visible instead of reducing the comparison to one score.

Which model fits which workflow

Choose Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) when the work benefits from the stronger benchmark profile and the cost profile still fits the project. Choose GPT-6.1 Sol (medium) when its provider ecosystem, latency, or pricing better matches the way the model will be used. The best choice is the one whose advantage appears in the rows that map to the actual workload.

Decision takeaway

For most readers, Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) is the stronger benchmark pick today. GPT-6.1 Sol (medium) remains worth considering when budget, speed, provider preference, or a specific benchmark row matters more than the overall intelligence index.

FAQ

Is Claude Opus 5.5 Adaptive Reasoning better than GPT-6.1 Sol medium?

Not across the board: Claude Opus 5.5 Adaptive Reasoning scores higher on the intelligence index, 57.6 to 47.8; GPT-6.1 Sol medium is 50% cheaper on blended price; Claude Opus 5.5 Adaptive Reasoning streams output 1.3 times as fast; and GPT-6.1 Sol medium reaches its first token sooner.

Which is newer, Claude Opus 5.5 Adaptive Reasoning or GPT-6.1 Sol medium?

GPT-6.1 Sol medium is newer. It was released on September 29, 2026, 7 days after Claude Opus 5.5 Adaptive Reasoning (September 22, 2026).

Which model has lower latency?

Claude Opus 5.5 Adaptive Reasoning generates output faster, at 96 tokens per second against 72 tokens per second. GPT-6.1 Sol medium reaches its first token sooner (4.7 seconds against 8.0 minutes). Counting the first-token wait, GPT-6.1 Sol medium finishes first for any reply shorter than about 140,000 tokens.

Who makes Claude Opus 5.5 Adaptive Reasoning and GPT-6.1 Sol medium?

Claude Opus 5.5 Adaptive Reasoning is made by Anthropic and GPT-6.1 Sol medium by OpenAI. Claude Opus 5.5 Adaptive Reasoning was released on September 22, 2026 and GPT-6.1 Sol medium on September 29, 2026.

Which is cheaper, Claude Opus 5.5 Adaptive Reasoning or GPT-6.1 Sol medium?

GPT-6.1 Sol medium is cheaper on a blended basis. Claude Opus 5.5 Adaptive Reasoning lists $4.00 per million input tokens and $20.00 per million output tokens; GPT-6.1 Sol medium lists $2.00 and $10.00. For 1 million input and 200,000 output tokens that is $8.00 against $4.00.

Final whistle

Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) currently has the stronger overall benchmark profile, while GPT-6.1 Sol (medium) may still be preferable depending on price, latency, coding strength, or ecosystem fit.

Where the numbers come from

The scores, speed and prices in this comparison come from independent third-party model evaluations that Franklin AI syncs each day, and the article was written from a snapshot of them. For the latest results, open the GPT-6.1 Sol (medium) and Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) pages. The AI Benchmark methodology explains how that data is collected and shown.

Comments (0)

No comments yet

Be the first to share your thoughts!