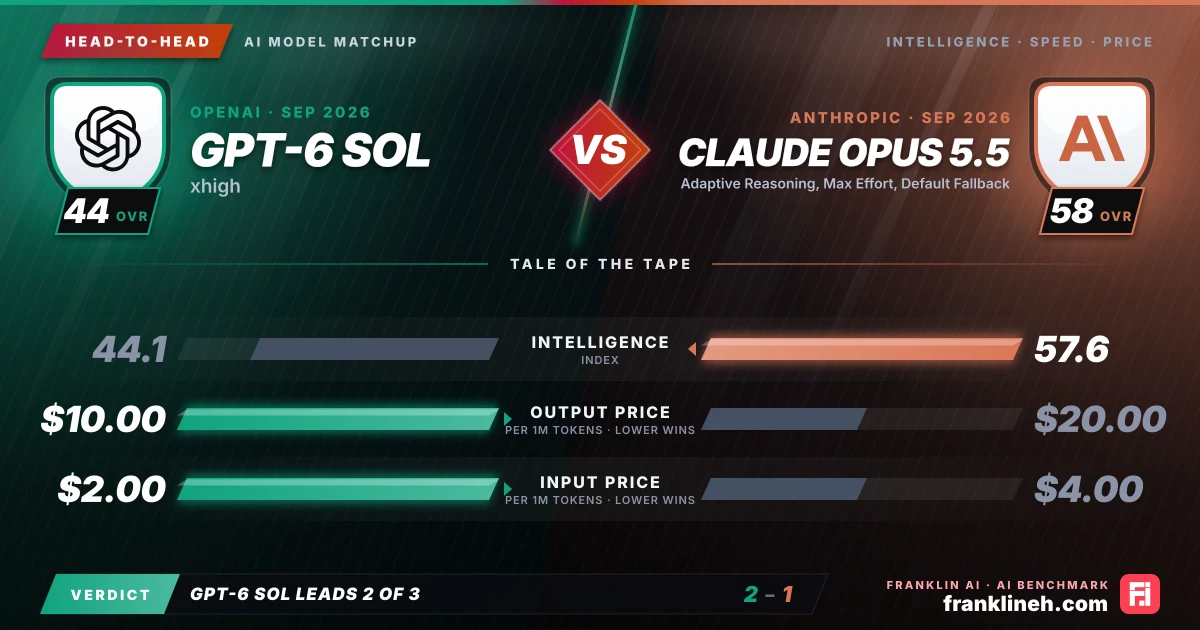
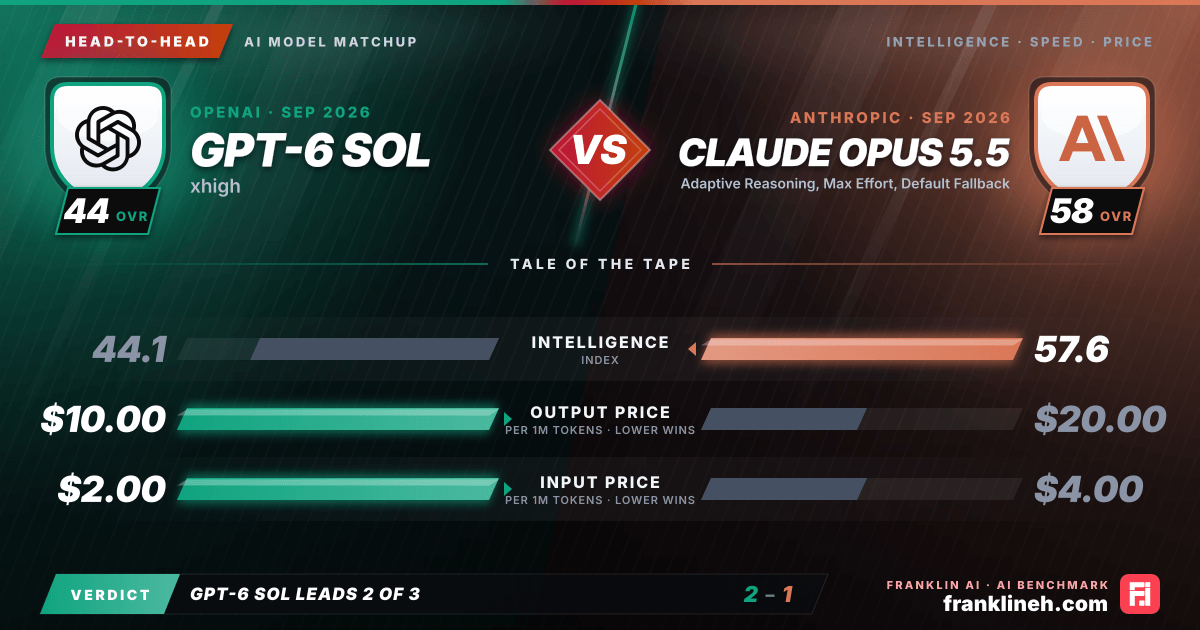
Head-to-head AI model comparison graphic: GPT-6 Sol (OpenAI) vs Claude Opus 5.5 (Anthropic). Intelligence index 44.1 vs 57.6; output price $10.00 vs $20.00 per million tokens; input price $2.00 vs $4.00 per million tokens. franklineh.com
GPT-6 Sol vs Claude Opus 5.5: head-to-head AI benchmark comparison. GPT-6 Sol leads on output price and input price; Claude Opus 5.5 leads on intelligence index.
Head to headUpdated

GPT-6 Sol vs. Claude Opus 5.5: A Comparative Analysis

Released on the same date, OpenAI’s GPT-6 Sol and Anthropic’s Claude Opus 5.5 represent distinct approaches to model architecture. While GPT-6 Sol prioritizes operational efficiency and speed, Claude Opus 5.5 positions itself as the more capable reasoning engine, creating a clear tradeoff between cost-effectiveness and raw performance for high-stakes tasks.

Pick it for GPT-6 Sol · Xhigh

  • Longer responses where sustained output speed matters
  • Higher-volume workloads where blended token cost matters
  • Teams already standardized on OpenAI

Pick it for Claude Opus 5.5 · Adaptive Reasoning, Max Effort, Default Fallback

  • Workloads that benefit from the stronger overall intelligence score
  • Latency-sensitive chat, support, and interactive product flows
  • Teams already standardized on Anthropic

By the numbers

These figures describe the two model configurations shown here. A dash means the source snapshot had no usable figure for that metric. Scores, speed and API pricing may change as providers update models.

MetricGPT-6 Sol (xhigh)Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback)
Intelligence Index44.157.6
Input price (per 1M tokens)$2.00$4.00
Output price (per 1M tokens)$10.00$20.00
Output speed (tokens/s)126–
Time to first token28s–
Release date2026-09-222026-09-22

What the benchmarks show

When evaluating the raw intelligence and reasoning capabilities of these two models, the data suggests a clear performance gap. Claude Opus 5.5 consistently outperforms GPT-6 Sol across all measured benchmarks. In the HLE (Human Learning Evaluation), Claude Opus 5.5 achieves a score of 0.614 compared to the 0.463 recorded by GPT-6 Sol. This trend continues in the SciCode benchmark, where Opus 5.5 scores 0.669 against Sol’s 0.551, and in the LCR benchmark, where Opus 5.5 leads with 0.8466 compared to Sol’s 0.8133.

These figures indicate that Claude Opus 5.5 is better suited for tasks requiring deep logical deduction and scientific reasoning. While GPT-6 Sol remains a highly capable model with an Intelligence Index of 44.1, it falls short of the 57.6 index assigned to Claude Opus 5.5. Users should note that coding and math-specific indices remain unknown for both models, meaning that while general reasoning is higher in Opus, specific domain performance may vary based on the nature of the prompt.

Speed and cost

Operational efficiency is where GPT-6 Sol distinguishes itself. OpenAI has optimized this model for speed, delivering an output rate of 126.074 tokens per second. However, users should be aware of the 27.683-second time-to-first-token, which may impact applications requiring real-time, low-latency interaction. In contrast, performance metrics for Claude Opus 5.5 are currently unknown, suggesting that Anthropic may be prioritizing reasoning depth over raw speed optimization.

From a financial perspective, the models occupy different tiers. GPT-6 Sol is significantly more affordable, with a blended cost of $4.00 per million tokens. Claude Opus 5.5 is priced at double that rate, with a blended cost of $8.00 per million tokens. For high-volume enterprise applications, the cost difference between these two models will compound quickly, making GPT-6 Sol the more sustainable choice for large-scale deployments where the marginal gains in reasoning provided by Opus are not strictly necessary.

Which model fits which workflow

Selecting the right model requires balancing the necessity of high-level reasoning against the constraints of your budget and latency requirements. Claude Opus 5.5 is designed for workflows that demand maximum effort and adaptive reasoning. It is the preferred tool for complex problem-solving, research-heavy tasks, and scenarios where the cost of an error outweighs the cost of the token usage.

Conversely, GPT-6 Sol is optimized for high-throughput environments. Its lower pricing and documented speed make it ideal for applications that require consistent, rapid output. It is well-suited for standard content generation, data processing pipelines, and internal tools where the model's intelligence index is sufficient for the task at hand. By opting for GPT-6 Sol, organizations can maintain a predictable cost structure while still benefiting from a modern, high-performance architecture.

Common questions about Claude Opus 5.5 Adaptive Reasoning and GPT-6 Sol xhigh

Is Claude Opus 5.5 Adaptive Reasoning better than GPT-6 Sol xhigh?

Not across the board: Claude Opus 5.5 Adaptive Reasoning scores higher on the intelligence index, 57.6 to 44.1; and GPT-6 Sol xhigh is 50% cheaper on blended price.

How much do Claude Opus 5.5 Adaptive Reasoning and GPT-6 Sol xhigh cost?

GPT-6 Sol xhigh is cheaper on a blended basis. Claude Opus 5.5 Adaptive Reasoning lists $4.00 per million input tokens and $20.00 per million output tokens; GPT-6 Sol xhigh lists $2.00 and $10.00. For 1 million input and 200,000 output tokens that is $8.00 against $4.00.

Are Claude Opus 5.5 Adaptive Reasoning and GPT-6 Sol xhigh from the same company?

Claude Opus 5.5 Adaptive Reasoning is made by Anthropic and GPT-6 Sol xhigh by OpenAI. Claude Opus 5.5 Adaptive Reasoning was released on September 22, 2026 and GPT-6 Sol xhigh on September 22, 2026.

Final whistle

The choice between these models depends on your tolerance for latency and cost versus your need for peak reasoning capability. If your workflow demands high throughput and budget predictability, GPT-6 Sol is the superior choice. However, for complex, high-stakes tasks where accuracy is paramount and cost is secondary, the superior benchmark performance of Claude Opus 5.5 justifies its higher price point. Evaluate your project’s sensitivity to time-to-first-token delays before committing to the more intensive Opus architecture.

Where the numbers come from

The scores, speed and prices in this comparison come from independent third-party model evaluations that Franklin AI syncs each day, and the article was written from a snapshot of them. For the latest results, open the GPT-6 Sol (xhigh) and Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) pages. The AI Benchmark methodology explains how that data is collected and shown.

Comments (0)

No comments yet

Be the first to share your thoughts!