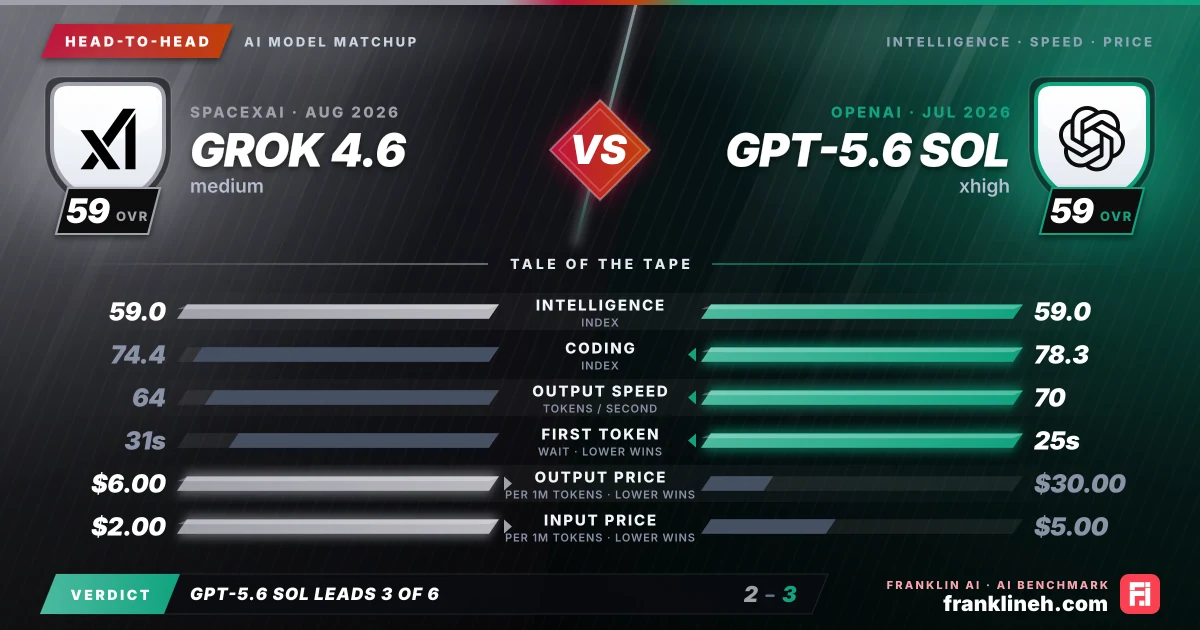
Head-to-head AI model comparison graphic: Grok 4.6 (SpaceXAI) vs GPT-5.6 Sol (OpenAI). Intelligence index 59.0 vs 59.0; coding index 74.4 vs 78.3; output speed 64 vs 70 tokens per second; time to first token 31s vs 25s; output price $6.00 vs $30.00 per million tokens; input price $2.00 vs $5.00 per million tokens. franklineh.com
Grok 4.6 vs GPT-5.6 Sol: head-to-head AI benchmark comparison. GPT-5.6 Sol leads on coding index, output speed and time to first token; Grok 4.6 leads on output price and input price; level on intelligence index.
Head to headUpdated

Grok 4.6 vs. GPT-5.6 Sol: A Comparative Analysis

This comparison evaluates the performance, cost, and technical capabilities of SpaceXAI’s Grok 4.6 and OpenAI’s GPT-5.6 Sol. While both models share an identical intelligence index, they diverge significantly in pricing structures, coding proficiency, and latency, offering distinct advantages for developers and enterprise users depending on their specific operational priorities.

Pick it for Grok 4.6 · Medium

  • Higher-volume workloads where blended token cost matters
  • Teams already standardized on SpaceXAI
  • Use cases where its strongest benchmark rows map to the workload

Pick it for GPT-5.6 Sol · Xhigh

  • Coding and agentic tasks where the benchmark edge matters
  • Latency-sensitive chat, support, and interactive product flows
  • Longer responses where sustained output speed matters

By the numbers

These figures describe the two model configurations shown here. A dash means the source snapshot had no usable figure for that metric. Scores, speed and API pricing may change as providers update models.

MetricGrok 4.6 (medium)GPT-5.6 Sol (xhigh)
Intelligence Index59.059.0
Coding Index74.478.3
Input price (per 1M tokens)$2.00$5.00
Output price (per 1M tokens)$6.00$30.00
Output speed (tokens/s)6470
Time to first token31s25s
Release date2026-08-122026-07-09

What the benchmarks show

When evaluating the intelligence of Grok 4.6 and GPT-5.6 Sol, both models arrive at an identical intelligence index of 59. However, a deeper look into specific domain benchmarks reveals nuanced differences in their capabilities. GPT-5.6 Sol demonstrates a slight edge in technical performance, recording a coding index of 78.3 compared to Grok 4.6’s 74.4. This trend continues across several specialized benchmarks, where GPT-5.6 Sol achieves higher scores in HLE (0.473 vs. 0.421), SciCode (0.56 vs. 0.546), and LCR (0.763 vs. 0.727).

While Grok 4.6 performs admirably, particularly with a GPQA score of 0.935—marginally higher than GPT-5.6 Sol’s 0.931—the latter offers a broader suite of validated metrics, including TerminalBench Hard and TAU2. For users requiring specialized reasoning in complex coding or scientific environments, GPT-5.6 Sol provides a more robust performance profile, whereas Grok 4.6 remains highly competitive in general-purpose intelligence tasks.

Speed and cost

The economic disparity between these two models is substantial. Grok 4.6 is priced at a blended rate of $3.00 per million tokens, with input costs at $2.00 and output at $6.00. In contrast, GPT-5.6 Sol carries a significantly higher price tag, with a blended rate of $11.25 per million tokens, driven by a $30.00 output cost. For organizations processing massive datasets, the cost-to-performance ratio of Grok 4.6 is objectively more favorable.

However, this cost difference is reflected in the operational speed of the models. GPT-5.6 Sol delivers a faster output speed of 70.021 tokens per second, compared to Grok 4.6’s 63.864 tokens per second. Furthermore, GPT-5.6 Sol exhibits a lower time-to-first-token latency of 25.458 seconds, versus 30.506 seconds for Grok 4.6. Users must decide if the premium paid for GPT-5.6 Sol is offset by the time saved during high-frequency interactions.

Which model fits which workflow

Selecting the appropriate model requires an assessment of the specific constraints of the project. Grok 4.6 is ideally suited for high-volume, long-running processes where token consumption is high and budget predictability is essential. Its performance is more than sufficient for a wide range of general tasks, and the lower cost structure allows for greater scalability without a proportional increase in expenditure.

GPT-5.6 Sol is better positioned for workflows where speed and coding accuracy are the primary bottlenecks. The model’s superior performance in coding and logic-heavy benchmarks makes it a more reliable partner for software engineering tasks or complex automated systems. While the higher output cost is a factor, the reduction in latency and the increased reliability in technical benchmarks provide a tangible advantage for developers who cannot afford the performance overhead of slower, less precise models.

Common questions about GPT-5.6 Sol xhigh and Grok 4.6 medium

Is Grok 4.6 medium better than GPT-5.6 Sol xhigh?

It depends on what you need: they are level on the intelligence index (59.0 and 59.0); Grok 4.6 medium is 73% cheaper on blended price; and GPT-5.6 Sol xhigh streams output 1.1 times as fast.

Which is newer, GPT-5.6 Sol xhigh or Grok 4.6 medium?

Grok 4.6 medium is newer. It was released on August 12, 2026, 34 days after GPT-5.6 Sol xhigh (July 9, 2026).

Which is better for coding, GPT-5.6 Sol xhigh or Grok 4.6 medium?

GPT-5.6 Sol xhigh has the higher coding index, 78.3 against 74.4.

Which is cheaper, GPT-5.6 Sol xhigh or Grok 4.6 medium?

Grok 4.6 medium is cheaper on a blended basis. GPT-5.6 Sol xhigh lists $5.00 per million input tokens and $30.00 per million output tokens; Grok 4.6 medium lists $2.00 and $6.00. For 1 million input and 200,000 output tokens that is $11.00 against $3.20.

Does GPT-5.6 Sol xhigh respond faster than Grok 4.6 medium?

GPT-5.6 Sol xhigh generates output faster, at 70 tokens per second against 64 tokens per second. GPT-5.6 Sol xhigh reaches its first token sooner (25 seconds against 31 seconds).

Final whistle

The choice between these models hinges on the balance between cost-efficiency and raw performance. Grok 4.6 is the clear choice for high-volume, cost-sensitive applications where budget management is paramount. Conversely, GPT-5.6 Sol justifies its higher price point through superior coding benchmarks and faster response times, making it the preferred tool for complex, time-sensitive development tasks. Users should prioritize GPT-5.6 Sol for precision-heavy workflows and Grok 4.6 for large-scale, budget-conscious deployments.

Where the numbers come from

The scores, speed and prices in this comparison come from independent third-party model evaluations that Franklin AI syncs each day, and the article was written from a snapshot of them. For the latest results, open the Grok 4.6 (medium) and GPT-5.6 Sol (xhigh) pages. The AI Benchmark methodology explains how that data is collected and shown.

Comments (0)

No comments yet

Be the first to share your thoughts!