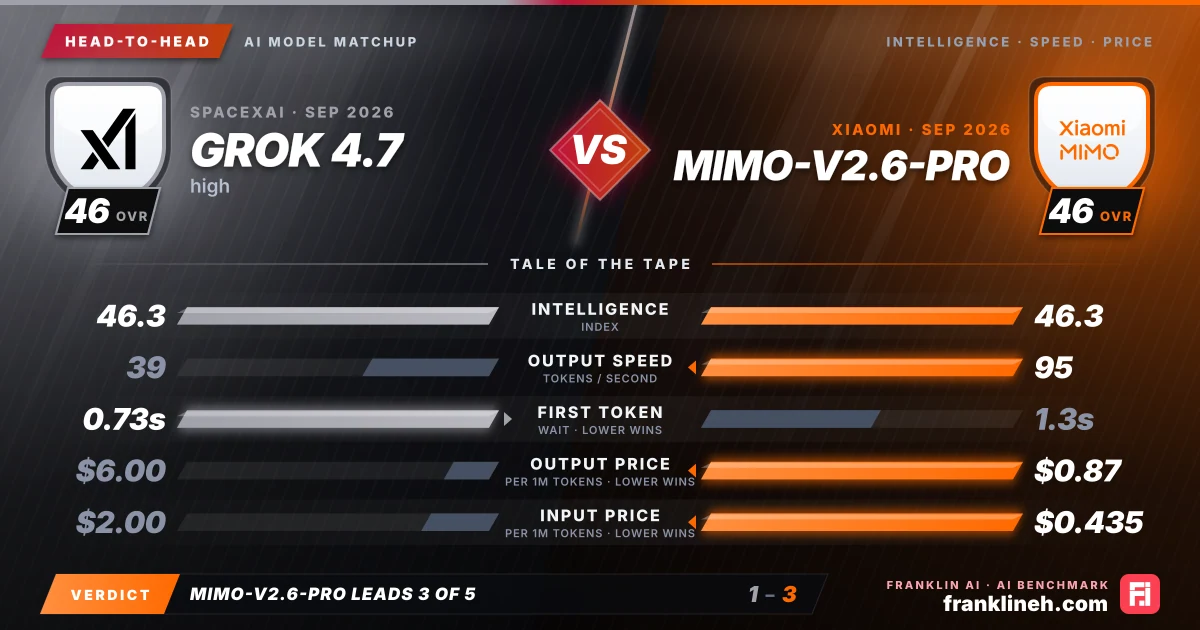
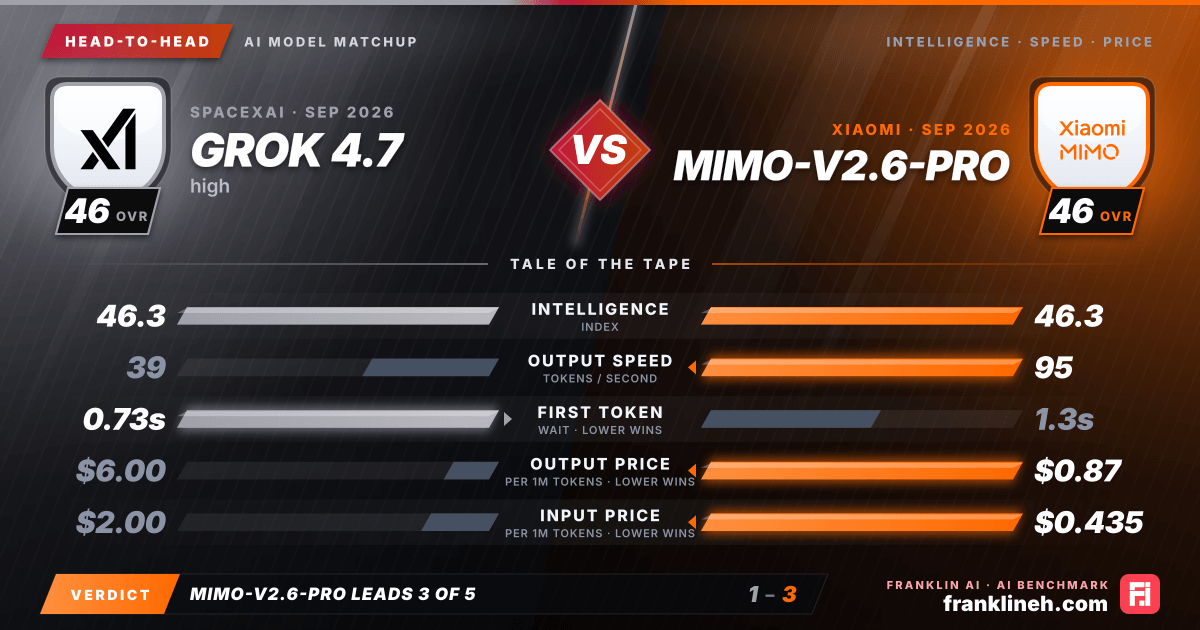
Head-to-head AI model comparison graphic: Grok 4.7 (SpaceXAI) vs MiMo-V2.6-Pro (Xiaomi). Intelligence index 46.3 vs 46.3; output speed 39 vs 95 tokens per second; time to first token 0.73s vs 1.3s; output price $6.00 vs $0.87 per million tokens; input price $2.00 vs $0.435 per million tokens. franklineh.com
Grok 4.7 vs MiMo-V2.6-Pro: head-to-head AI benchmark comparison. MiMo-V2.6-Pro leads on output speed, output price and input price; Grok 4.7 leads on time to first token; level on intelligence index.
Head to headUpdated

Grok 4.7 vs. MiMo-V2.6-Pro: A Comparative Analysis

Released on the same day, Grok 4.7 and MiMo-V2.6-Pro share an identical intelligence index. However, they diverge significantly in their operational profiles, with MiMo-V2.6-Pro offering superior benchmark performance and cost efficiency, while Grok 4.7 provides a faster initial response time for latency-sensitive applications.

Pick it for Grok 4.7 · High

  • Latency-sensitive chat, support, and interactive product flows
  • Teams already standardized on SpaceXAI
  • Use cases where its strongest benchmark rows map to the workload

Pick it for MiMo-V2.6-Pro

  • Longer responses where sustained output speed matters
  • Higher-volume workloads where blended token cost matters
  • Teams already standardized on Xiaomi

By the numbers

These figures describe the two model configurations shown here. A dash means the source snapshot had no usable figure for that metric. Scores, speed and API pricing may change as providers update models.

MetricGrok 4.7 (high)MiMo-V2.6-Pro
Intelligence Index46.346.3
Input price (per 1M tokens)$2.00$0.435
Output price (per 1M tokens)$6.00$0.87
Output speed (tokens/s)3995
Time to first token0.73s1.3s
Release date2026-09-212026-09-21

What the Benchmarks Show

Both Grok 4.7 and MiMo-V2.6-Pro, released on September 21, 2026, arrive with an identical intelligence index of 46.3. While this suggests a shared tier of general capability, their performance on specific benchmarks reveals distinct differences in technical aptitude. Across the HLE, SciCode, and LCR benchmarks, MiMo-V2.6-Pro consistently outperforms Grok 4.7. Specifically, MiMo-V2.6-Pro achieved an HLE score of 0.494 compared to Grok 4.7’s 0.423, and a SciCode score of 0.609 against Grok 4.7’s 0.578. The LCR benchmark further highlights this gap, with MiMo-V2.6-Pro scoring 0.863 compared to 0.77 for Grok 4.7. These results suggest that while the models may be equally "intelligent" in a general sense, MiMo-V2.6-Pro is better optimized for the specific tasks measured by these benchmarks.

Speed and Cost

The economic and performance profiles of these models present a clear trade-off for developers. MiMo-V2.6-Pro is significantly more affordable, with a blended pricing model of $0.54 per million tokens, compared to the $3.00 per million tokens charged for Grok 4.7. This represents a substantial cost advantage for high-volume users. However, Grok 4.7 compensates for its higher price with a faster time to first token, clocking in at 0.732 seconds compared to 1.344 seconds for MiMo-V2.6-Pro. If your application requires near-instantaneous feedback, the extra cost of Grok 4.7 may be justified. Conversely, for batch processing where total throughput is more critical than the latency of the first token, MiMo-V2.6-Pro’s output speed of 95.064 tokens per second—more than double the 38.606 tokens per second of Grok 4.7—makes it the more efficient choice.

Which Model Fits Which Workflow

Determining the right model requires an assessment of your project's specific constraints. Grok 4.7 is designed for scenarios where the speed of the initial interaction is paramount. Its lower time to first token makes it suitable for real-time conversational interfaces or interactive tools where user experience is tied to immediate responsiveness. The higher cost is a premium paid for this specific performance characteristic.

MiMo-V2.6-Pro is better suited for high-volume, compute-intensive tasks. Its superior benchmark scores across HLE, SciCode, and LCR indicate a higher level of proficiency in complex reasoning and technical tasks. When paired with its significantly lower cost and higher sustained output speed, it becomes the logical choice for data processing pipelines, automated research, or large-scale content generation where budget and throughput are the primary drivers of success.

Decision Takeaway

Ultimately, neither model is objectively superior in every category. The decision rests on whether your priority is minimizing the latency of the first response or maximizing the value and speed of the total output. By aligning these technical metrics with your specific use case, you can select the model that best fits your operational requirements.

Quick answers

Is Grok 4.7 high better than MiMo-V2.6-Pro?

Not across the board: they are level on the intelligence index (46.3 and 46.3); MiMo-V2.6-Pro is 82% cheaper on blended price; MiMo-V2.6-Pro streams output 2.5 times as fast; and Grok 4.7 high reaches its first token sooner.

Are Grok 4.7 high and MiMo-V2.6-Pro from the same company?

Grok 4.7 high is made by SpaceXAI and MiMo-V2.6-Pro by Xiaomi. Grok 4.7 high was released on September 21, 2026 and MiMo-V2.6-Pro on September 21, 2026.

Does Grok 4.7 high respond faster than MiMo-V2.6-Pro?

MiMo-V2.6-Pro generates output faster, at 95 tokens per second against 39 tokens per second. Grok 4.7 high reaches its first token sooner (0.73 seconds against 1.3 seconds). Counting the first-token wait, Grok 4.7 high finishes short replies first and MiMo-V2.6-Pro pulls ahead beyond about 50 tokens.

How much do Grok 4.7 high and MiMo-V2.6-Pro cost?

MiMo-V2.6-Pro is cheaper on a blended basis. Grok 4.7 high lists $2.00 per million input tokens and $6.00 per million output tokens; MiMo-V2.6-Pro lists $0.435 and $0.87. For 1 million input and 200,000 output tokens that is $3.20 against $0.61.

Final whistle

The choice between these models depends on your specific infrastructure requirements. If your workflow prioritizes cost-efficiency and high-throughput processing, MiMo-V2.6-Pro is the clear technical leader. Conversely, if your application requires the lowest possible latency for initial tokens, Grok 4.7 offers a more responsive experience. Both models provide the same baseline intelligence, meaning the decision should be driven by your budget and the importance of speed versus total throughput.

Where the numbers come from

The scores, speed and prices in this comparison come from independent third-party model evaluations that Franklin AI syncs each day, and the article was written from a snapshot of them. For the latest results, open the Grok 4.7 (high) and MiMo-V2.6-Pro pages. The AI Benchmark methodology explains how that data is collected and shown.

Comments (0)

No comments yet

Be the first to share your thoughts!