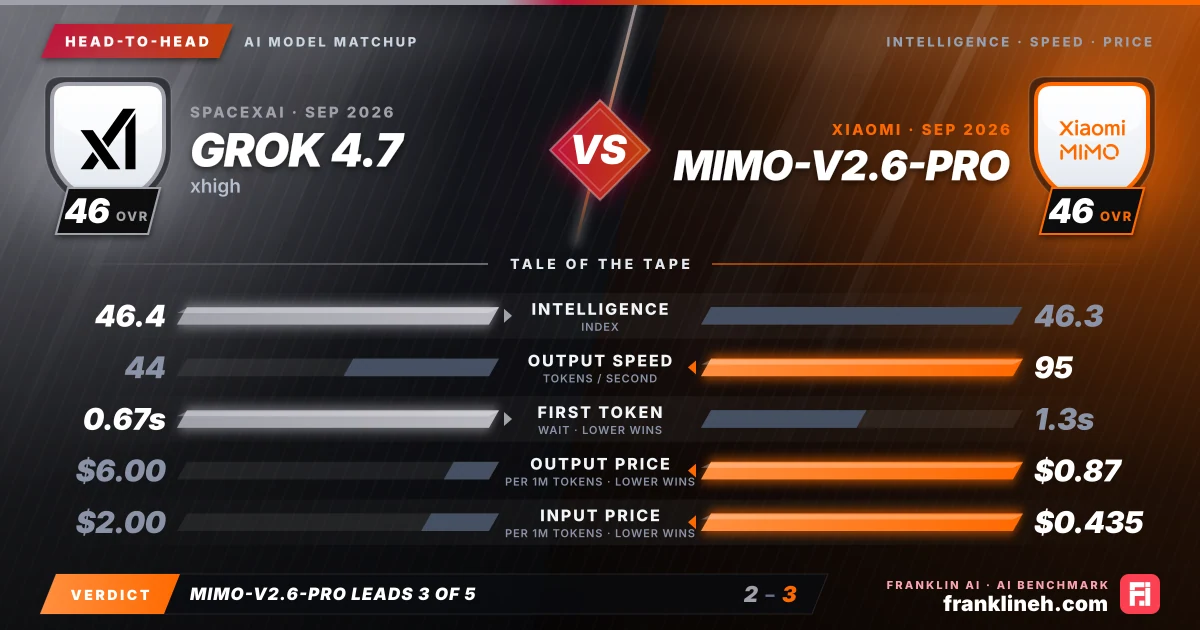
Head-to-head AI model comparison graphic: Grok 4.7 (SpaceXAI) vs MiMo-V2.6-Pro (Xiaomi). Intelligence index 46.4 vs 46.3; output speed 44 vs 95 tokens per second; time to first token 0.67s vs 1.3s; output price $6.00 vs $0.87 per million tokens; input price $2.00 vs $0.435 per million tokens. franklineh.com
Grok 4.7 vs MiMo-V2.6-Pro: head-to-head AI benchmark comparison. MiMo-V2.6-Pro leads on output speed, output price and input price; Grok 4.7 leads on intelligence index and time to first token.
Head to headUpdated

Grok 4.7 vs. MiMo-V2.6-Pro: A Comparative Analysis

Released simultaneously on September 21, 2026, SpaceXAI’s Grok 4.7 and Xiaomi’s MiMo-V2.6-Pro represent two distinct approaches to AI performance. While Grok 4.7 maintains a slight edge in general intelligence, MiMo-V2.6-Pro offers superior benchmark results and significantly lower operational costs, forcing users to weigh raw intelligence against efficiency and budget constraints.

Pick it for Grok 4.7 · Xhigh

  • Workloads that benefit from the stronger overall intelligence score
  • Latency-sensitive chat, support, and interactive product flows
  • Teams already standardized on SpaceXAI

Pick it for MiMo-V2.6-Pro

  • Longer responses where sustained output speed matters
  • Higher-volume workloads where blended token cost matters
  • Teams already standardized on Xiaomi

By the numbers

These figures describe the two model configurations shown here. A dash means the source snapshot had no usable figure for that metric. Scores, speed and API pricing may change as providers update models.

MetricGrok 4.7 (xhigh)MiMo-V2.6-Pro
Intelligence Index46.446.3
Input price (per 1M tokens)$2.00$0.435
Output price (per 1M tokens)$6.00$0.87
Output speed (tokens/s)4495
Time to first token0.67s1.3s
Release date2026-09-212026-09-21

What the benchmarks show

When evaluating the technical capabilities of Grok 4.7 and MiMo-V2.6-Pro, the data reveals a nuanced landscape. Grok 4.7 holds a marginal lead in the Intelligence Index, scoring 46.4 compared to MiMo-V2.6-Pro’s 46.3. This suggests that for tasks requiring high-level reasoning or general knowledge, Grok 4.7 may provide a slight advantage. However, this lead does not translate into broader performance metrics.

In standardized testing, MiMo-V2.6-Pro consistently outperforms Grok 4.7. Across the HLE, SciCode, and LCR benchmarks, the MiMo-V2.6-Pro model demonstrates higher proficiency. Specifically, its LCR score of 0.863 significantly eclipses the 0.767 score achieved by Grok 4.7. While the Intelligence Index provides a high-level overview, the benchmark data suggests that MiMo-V2.6-Pro is more capable when applied to specialized scientific and logical reasoning tasks, despite the near-identical intelligence ratings.

Speed and cost

The most striking divergence between these two models lies in their economic and operational profiles. MiMo-V2.6-Pro is positioned as a high-efficiency model, with a blended pricing structure of $0.54 per million tokens. In contrast, Grok 4.7 is significantly more expensive, costing $3.00 per million tokens—nearly six times the price of the Xiaomi offering. For organizations processing large datasets or maintaining high-frequency API calls, this price disparity will likely be the deciding factor.

Operational speed presents a different set of tradeoffs. MiMo-V2.6-Pro is faster in terms of raw output, delivering 95.064 tokens per second. However, it suffers from a higher time-to-first-token latency of 1.344 seconds. Grok 4.7 is slower in total output speed at 44.37 tokens per second, but it is more responsive at the start of a request, with a time-to-first-token of only 0.67 seconds. Users who prioritize immediate feedback in conversational interfaces may find Grok 4.7’s responsiveness preferable, while those prioritizing throughput will favor the speed of MiMo-V2.6-Pro.

Which model fits which workflow

Selecting the appropriate model requires an assessment of your specific operational priorities. Grok 4.7 is best suited for applications where the absolute highest intelligence index is required and where the initial response time is critical to the user experience. Its lower latency at the start of generation makes it a strong candidate for interactive, real-time chat applications where the user expects an immediate response.

Conversely, MiMo-V2.6-Pro is designed for high-volume, performance-heavy workflows. Its superior benchmark scores across scientific and logical domains make it better suited for complex data analysis, automated coding tasks, or research-heavy applications. Because it is substantially more cost-effective, it is the clear choice for scaling operations where token consumption is a primary driver of infrastructure costs. While it is slightly slower to begin generating text, its high sustained throughput makes it ideal for batch processing and large-scale document analysis.

FAQ

Is MiMo-V2.6-Pro better than Grok 4.7 xhigh?

Neither wins everywhere: they are level on the intelligence index (46.4 and 46.3); MiMo-V2.6-Pro is 82% cheaper on blended price; MiMo-V2.6-Pro streams output 2.1 times as fast; and Grok 4.7 xhigh reaches its first token sooner.

Which model has lower latency?

MiMo-V2.6-Pro generates output faster, at 95 tokens per second against 44 tokens per second. Grok 4.7 xhigh reaches its first token sooner (0.67 seconds against 1.3 seconds). Counting the first-token wait, Grok 4.7 xhigh finishes short replies first and MiMo-V2.6-Pro pulls ahead beyond about 50 tokens.

Are Grok 4.7 xhigh and MiMo-V2.6-Pro from the same company?

Grok 4.7 xhigh is made by SpaceXAI and MiMo-V2.6-Pro by Xiaomi. Grok 4.7 xhigh was released on September 21, 2026 and MiMo-V2.6-Pro on September 21, 2026.

Is MiMo-V2.6-Pro cheaper than Grok 4.7 xhigh?

MiMo-V2.6-Pro is cheaper on a blended basis. Grok 4.7 xhigh lists $2.00 per million input tokens and $6.00 per million output tokens; MiMo-V2.6-Pro lists $0.435 and $0.87. For 1 million input and 200,000 output tokens that is $3.20 against $0.61.

Final whistle

The choice between these models depends on your specific tolerance for latency and cost. If your workflow demands the highest possible intelligence index and you are less concerned with budget, Grok 4.7 is the logical choice. However, for most production environments, MiMo-V2.6-Pro is the superior option. It delivers higher benchmark performance across all measured categories at a fraction of the cost, making it the more pragmatic tool for high-volume, cost-sensitive AI applications.

Where the numbers come from

The scores, speed and prices in this comparison come from independent third-party model evaluations that Franklin AI syncs each day, and the article was written from a snapshot of them. For the latest results, open the Grok 4.7 (xhigh) and MiMo-V2.6-Pro pages. The AI Benchmark methodology explains how that data is collected and shown.

Comments (0)

No comments yet

Be the first to share your thoughts!