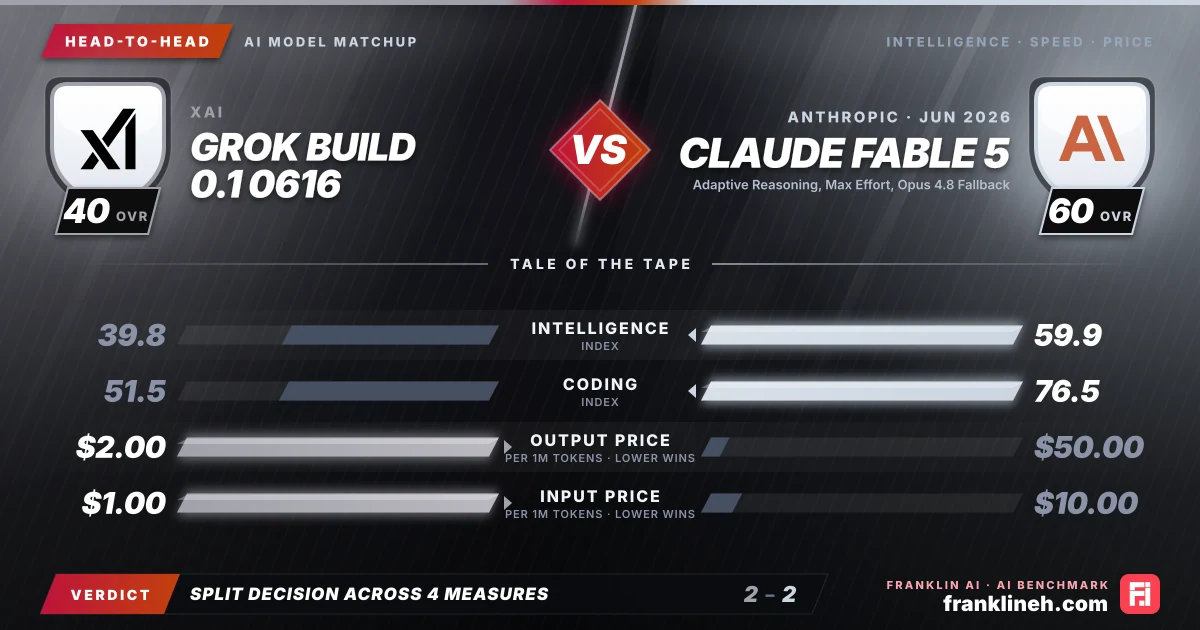
Head-to-head AI model comparison graphic: Grok Build 0.1 0616 (xAI) vs Claude Fable 5 (Anthropic). Intelligence index 39.8 vs 59.9; coding index 51.5 vs 76.5; output price $2.00 vs $50.00 per million tokens; input price $1.00 vs $10.00 per million tokens. franklineh.com
Grok Build 0.1 0616 vs Claude Fable 5: head-to-head AI benchmark comparison. Grok Build 0.1 0616 leads on output price and input price; Claude Fable 5 leads on intelligence index and coding index.
Head to headUpdated

Grok Build 0.1 0616 vs Claude Fable 5

Claude Fable 5 offers superior intelligence and coding capabilities compared to Grok Build 0.1 0616. While Grok provides significant cost savings and transparent performance metrics, Claude Fable 5 is the more powerful model for complex reasoning and technical tasks.

Pick it for Grok Build 0.1 0616

  • High-speed, low-latency applications
  • Cost-sensitive enterprise projects
  • High-volume token processing

Pick it for Claude Fable 5 · Adaptive Reasoning, Max Effort, Opus 4.8 Fallback

  • Complex reasoning and logic tasks
  • Advanced software development
  • High-accuracy research requirements

By the numbers

These figures describe the two model configurations shown here. A dash means the source snapshot had no usable figure for that metric. Scores, speed and API pricing may change as providers update models.

MetricGrok Build 0.1 0616Claude Fable 5 (Adaptive Reasoning, Max Effort, Opus 4.8 Fallback)
Intelligence Index39.859.9
Coding Index51.576.5
Input price (per 1M tokens)$1.00$10.00
Output price (per 1M tokens)$2.00$50.00
Output speed (tokens/s)70–
Time to first token0.41s–
Release date–2026-06-09

Quick Take

This comparison evaluates xAI’s Grok Build 0.1 0616 against Anthropic’s Claude Fable 5. Claude Fable 5, released on June 9, 2026, positions itself as a high-end reasoning model, while Grok Build 0.1 0616 offers a cost-effective alternative with documented latency metrics.

Benchmark Read

Claude Fable 5 demonstrates a clear lead in core intelligence and technical benchmarks. It holds an Intelligence index of 59.9 and a Coding index of 76.5, compared to Grok’s 39.8 and 51.5, respectively. In specific evaluation metrics, Claude Fable 5 consistently outperforms Grok:

  • GPQA: 0.926 (Claude) vs. 0.895 (Grok)
  • HLE: 0.533 (Claude) vs. 0.36 (Grok)
  • SciCode: 0.602 (Claude) vs. 0.502 (Grok)
  • LCR: 0.7 (Claude) vs. 0.646 (Grok)

Claude Fable 5 also excels in specialized benchmarks, achieving a 0.985 on TAU2 and 0.628 on TerminalBench Hard, showcasing its advanced reasoning capabilities.

Cost and Speed

There is a significant disparity in pricing models. Grok Build 0.1 0616 is highly affordable, with a blended cost of $1.25/1M tokens (Input $1.00, Output $2.00). In contrast, Claude Fable 5 carries a premium price, with a blended cost of $20.00/1M tokens (Input $10.00, Output $50.00).

Regarding performance, Grok provides transparent speed data, operating at 70.253 tokens per second with a time-to-first-token of 0.405s. Performance data for Claude Fable 5 is currently unknown.

Best Fit

Grok Build 0.1 0616 is best suited for developers and enterprises requiring high-throughput, cost-sensitive applications where speed is a priority. Claude Fable 5 is the optimal choice for complex research, advanced coding, and tasks requiring the highest level of reasoning accuracy, regardless of the higher cost.

Frequently asked questions

Is Claude Fable 5 Adaptive Reasoning better than Grok Build 0.1 0616?

It depends on what you need: Claude Fable 5 Adaptive Reasoning scores higher on the intelligence index, 59.9 to 39.8; and Grok Build 0.1 0616 is 94% cheaper on blended price.

Who makes Claude Fable 5 Adaptive Reasoning and Grok Build 0.1 0616?

Claude Fable 5 Adaptive Reasoning is made by Anthropic and Grok Build 0.1 0616 by xAI.

Is Claude Fable 5 Adaptive Reasoning or Grok Build 0.1 0616 better at coding?

Claude Fable 5 Adaptive Reasoning has the higher coding index, 76.5 against 51.5.

Is Grok Build 0.1 0616 cheaper than Claude Fable 5 Adaptive Reasoning?

Grok Build 0.1 0616 is cheaper on a blended basis. Claude Fable 5 Adaptive Reasoning lists $10.00 per million input tokens and $50.00 per million output tokens; Grok Build 0.1 0616 lists $1.00 and $2.00. For 1 million input and 200,000 output tokens that is $20.00 against $1.40.

Final whistle

Choose Claude Fable 5 if your priority is maximum intelligence and coding proficiency, as it outperforms Grok across all shared benchmarks. However, if you are operating on a strict budget or require high-speed, low-latency performance, Grok Build 0.1 0616 is the more economical and efficient choice for high-volume tasks.

Where the numbers come from

The scores, speed and prices in this comparison come from independent third-party model evaluations that Franklin AI syncs each day, and the article was written from a snapshot of them. For the latest results, open the Grok Build 0.1 0616 and Claude Fable 5 (Adaptive Reasoning, Max Effort, Opus 4.8 Fallback) pages. The AI Benchmark methodology explains how that data is collected and shown.

Comments (0)

No comments yet

Be the first to share your thoughts!