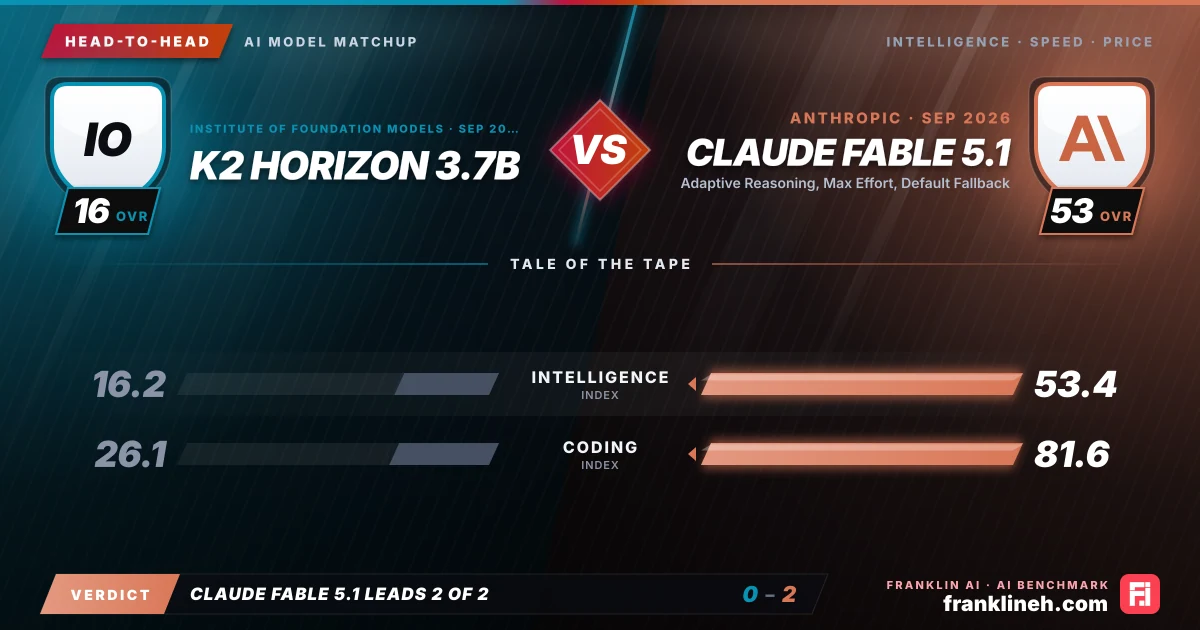
Head-to-head AI model comparison graphic: K2 Horizon 3.7B (Institute of Foundation Models) vs Claude Fable 5.1 (Anthropic). Intelligence index 16.2 vs 53.4; coding index 26.1 vs 81.6. franklineh.com
K2 Horizon 3.7B vs Claude Fable 5.1: head-to-head AI benchmark comparison. Claude Fable 5.1 leads on intelligence index and coding index.
Head to headUpdated

K2 Horizon 3.7B vs. Claude Fable 5.1: A Comparative Analysis

This comparison evaluates the K2 Horizon 3.7B and Claude Fable 5.1, contrasting the Institute of Foundation Models' zero-cost, lightweight approach against Anthropic’s high-performance, reasoning-focused architecture to help users determine the optimal model for their specific computational and budgetary requirements.

Pick it for K2 Horizon 3.7B

  • Latency-sensitive chat, support, and interactive product flows
  • Higher-volume workloads where blended token cost matters
  • Teams already standardized on Institute of Foundation Models

Pick it for Claude Fable 5.1 · Adaptive Reasoning, Max Effort, Default Fallback

  • Workloads that benefit from the stronger overall intelligence score
  • Coding and agentic tasks where the benchmark edge matters
  • Longer responses where sustained output speed matters

By the numbers

These figures describe the two model configurations shown here. A dash means the source snapshot had no usable figure for that metric. Scores, speed and API pricing may change as providers update models.

MetricK2 Horizon 3.7BClaude Fable 5.1 (Adaptive Reasoning, Max Effort, Default Fallback)
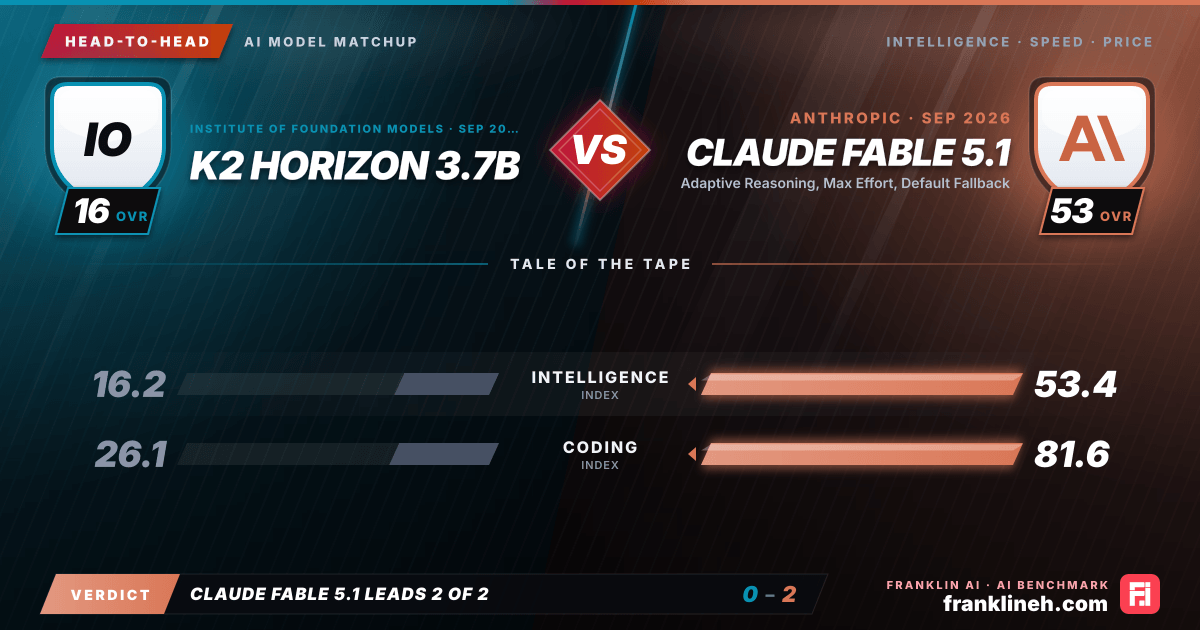
Intelligence Index16.253.4
Coding Index26.181.6
Input price (per 1M tokens)–$10.00
Output price (per 1M tokens)–$50.00
Output speed (tokens/s)–70
Time to first token–2.7 min
Release date2026-09-032026-09-01

Understanding the Performance Gap

The performance disparity between the K2 Horizon 3.7B and Claude Fable 5.1 is substantial, reflecting their distinct design philosophies. Claude Fable 5.1, released by Anthropic on September 1, 2026, demonstrates a clear advantage in cognitive tasks, boasting an intelligence index of 53.4 and a coding index of 81.6. In contrast, the K2 Horizon 3.7B, released two days later, records an intelligence index of 16.2 and a coding index of 26.1. These metrics suggest that while K2 Horizon is built for efficiency, it lacks the specialized reasoning depth found in Anthropic’s flagship model.

What the Benchmarks Show

Benchmark data reinforces the gap in capability. Claude Fable 5.1 consistently outperforms K2 Horizon across all measured categories. In the GPQA benchmark, Fable 5.1 achieves a score of 0.937 compared to K2 Horizon’s 0.692. The difference is even more pronounced in the HLE and SciCode benchmarks, where Fable 5.1 records scores of 0.591 and 0.631, respectively, while K2 Horizon trails at 0.139 and 0.22. The LCR benchmark follows a similar trend, with Fable 5.1 at 0.853 and K2 Horizon at 0.623. These results indicate that for tasks requiring complex scientific reasoning or high-level coding, Claude Fable 5.1 provides a significantly more robust foundation.

Speed and Cost Trade-offs

The economic and operational profiles of these models are polar opposites. K2 Horizon 3.7B is positioned as a zero-cost utility, with input and output pricing set at $0.00 per million tokens. This makes it an ideal candidate for high-volume, low-complexity tasks where cost-per-inference is the primary barrier to entry. However, this cost-efficiency comes with a lack of transparency regarding performance metrics, as both output speed and time-to-first-token remain unknown.

Claude Fable 5.1 operates on a premium pricing model, charging $10.00 per million input tokens and $50.00 per million output tokens, resulting in a blended cost of $20.00 per million tokens. While this is a significant financial commitment, it provides predictable performance, with an output speed of 69.665 tokens per second. Users must weigh the 161.953-second time-to-first-token latency against the model's superior reasoning capabilities, as the initial wait time is a notable factor for real-time applications.

Which Model Fits Your Workflow

Determining the right model requires an assessment of the specific demands of your project. K2 Horizon 3.7B is best suited for environments where the cost of inference must be minimized or where the model is integrated into large-scale, automated pipelines that do not require high-level reasoning. Its lightweight nature suggests it is designed for accessibility and broad deployment.

Claude Fable 5.1 is designed for high-stakes environments where accuracy, complex reasoning, and coding proficiency are non-negotiable. Despite the higher cost and latency, the performance gains in intelligence and coding make it the appropriate choice for research, advanced development, and complex problem-solving tasks that exceed the capabilities of smaller, more efficient models.

Common questions about Claude Fable 5.1 Adaptive Reasoning and K2 Horizon 3.7B

Is K2 Horizon 3.7B better than Claude Fable 5.1 Adaptive Reasoning?

Claude Fable 5.1 Adaptive Reasoning leads on every measure the catalogue separates: Claude Fable 5.1 Adaptive Reasoning scores higher on the intelligence index, 53.4 to 16.2.

When were Claude Fable 5.1 Adaptive Reasoning and K2 Horizon 3.7B released?

K2 Horizon 3.7B is newer. It was released on September 3, 2026, 2 days after Claude Fable 5.1 Adaptive Reasoning (September 1, 2026).

Who makes Claude Fable 5.1 Adaptive Reasoning and K2 Horizon 3.7B?

Claude Fable 5.1 Adaptive Reasoning is made by Anthropic and K2 Horizon 3.7B by Institute of Foundation Models. Claude Fable 5.1 Adaptive Reasoning was released on September 1, 2026 and K2 Horizon 3.7B on September 3, 2026.

Which is better for coding, Claude Fable 5.1 Adaptive Reasoning or K2 Horizon 3.7B?

Claude Fable 5.1 Adaptive Reasoning has the higher coding index, 81.6 against 26.1.

Final whistle

The choice between these models hinges on the trade-off between cost-efficiency and reasoning depth. K2 Horizon 3.7B is a compelling, zero-cost solution for lightweight tasks where budget is the primary constraint. Conversely, Claude Fable 5.1 offers significantly higher intelligence and coding proficiency, making it the necessary choice for complex, high-stakes workflows. Users requiring advanced reasoning must accept the higher operational costs and latency associated with the Fable 5.1 architecture.

Where the numbers come from

The scores, speed and prices in this comparison come from independent third-party model evaluations that Franklin AI syncs each day, and the article was written from a snapshot of them. For the latest results, open the K2 Horizon 3.7B and Claude Fable 5.1 (Adaptive Reasoning, Max Effort, Default Fallback) pages. The AI Benchmark methodology explains how that data is collected and shown.

Comments (0)

No comments yet

Be the first to share your thoughts!