
What the Benchmarks Show
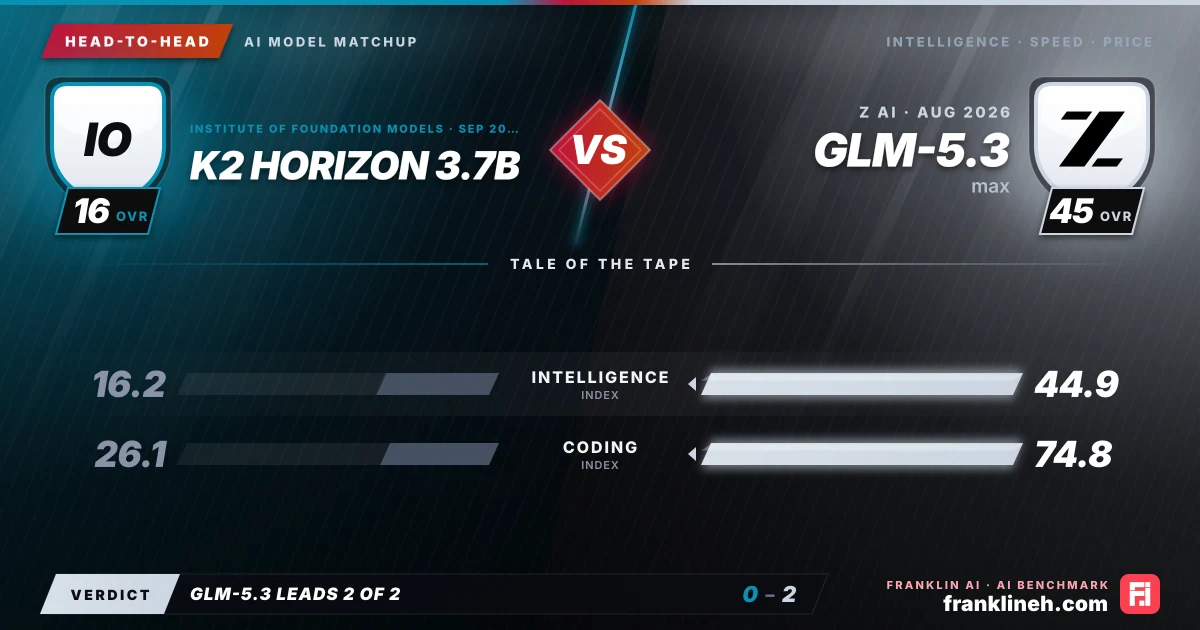
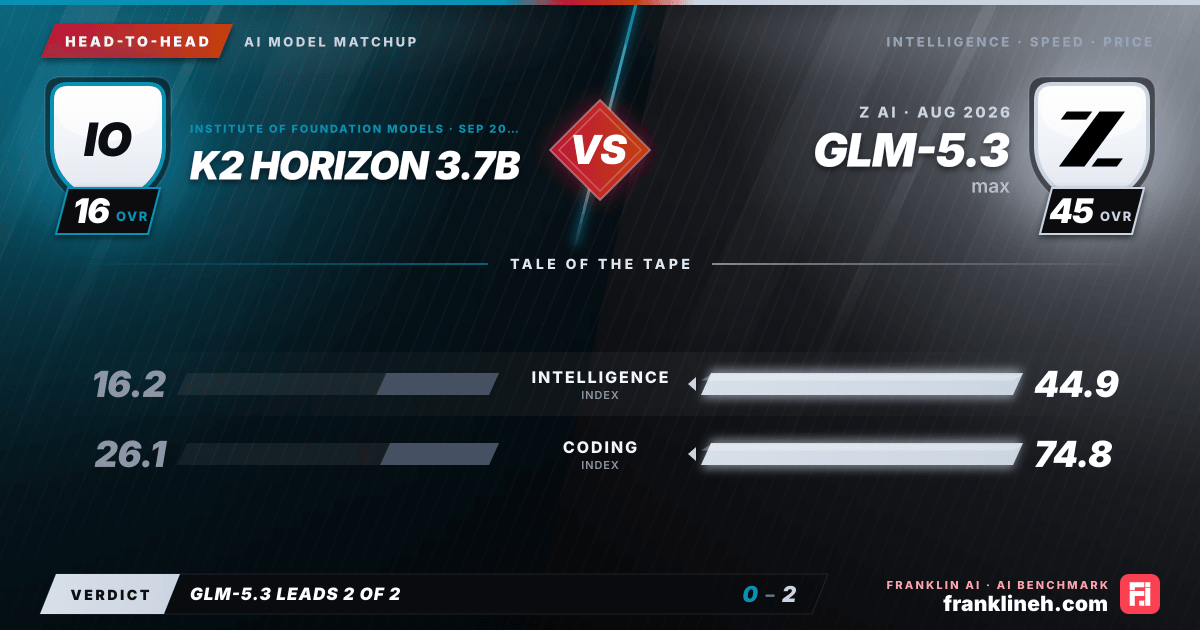
The performance gap between the K2 Horizon 3.7B and the GLM-5.3 (max) is significant across all measured metrics. The GLM-5.3 (max) consistently outperforms the K2 Horizon 3.7B, reflecting its higher intelligence and coding indices of 44.9 and 74.8, respectively, compared to the 16.2 and 26.1 scores of the K2 model. In standardized testing, the GLM-5.3 (max) achieves a GPQA score of 0.917 and an HLE score of 0.423, indicating a stronger grasp of complex reasoning and high-level evaluation tasks.
K2 Horizon 3.7B presents a more modest profile, with a GPQA score of 0.692 and an HLE score of 0.139. While the SciCode and LCR benchmarks also favor the GLM-5.3 (max), the K2 Horizon 3.7B remains a viable option for simpler tasks. It is important to note that both models lack publicly available data for math-specific benchmarks, which may be a consideration for users focused on advanced mathematical computation.
Speed and Cost
The economic and operational profiles of these two models are starkly different. K2 Horizon 3.7B is positioned as a zero-cost solution, with input, output, and blended pricing all set at $0.00 per million tokens. This makes it an exceptionally attractive option for developers looking to minimize infrastructure spend or those running high-frequency, low-complexity tasks. However, the model’s operational speed and time-to-first-token metrics remain unknown, which may introduce uncertainty regarding latency in real-time applications.
In contrast, GLM-5.3 (max) operates on a premium pricing model, with a blended cost of $2.15 per million tokens. While this represents a clear financial commitment, it is backed by transparent performance data. The model delivers an output speed of 53.172 tokens per second and a time-to-first-token of 2.992 seconds. For enterprise applications where latency consistency and predictable throughput are required, the GLM-5.3 (max) provides the necessary performance guarantees that the K2 Horizon 3.7B currently lacks.
Which Model Fits Which Workflow
Selecting the appropriate model requires balancing the necessity for high-level reasoning against the constraints of your budget. The GLM-5.3 (max) is designed for workflows that demand high accuracy, such as complex software engineering, advanced data analysis, or intricate reasoning tasks. Its higher intelligence index suggests that it is better equipped to handle nuanced instructions and multi-step problem solving.
K2 Horizon 3.7B is best utilized in scenarios where the cost of inference is a limiting factor. It is well-suited for high-volume, repetitive tasks that do not require the deep reasoning capabilities of a larger model. Because it is free to use, it serves as an excellent sandbox for prototyping or as a secondary model for filtering and routing tasks before escalating to a more expensive, high-intelligence model.
Decision Takeaway
Ultimately, the GLM-5.3 (max) is the superior choice for production environments requiring reliability and high-level cognitive performance. The K2 Horizon 3.7B is a specialized tool for developers who prioritize cost-efficiency above all else. By evaluating your specific latency requirements and the complexity of your prompts, you can determine whether the performance premium of the GLM-5.3 (max) justifies the investment over the zero-cost accessibility of the K2 Horizon 3.7B.
Comments (0)
to join the discussion
No comments yet
Be the first to share your thoughts!