
What the Benchmarks Show
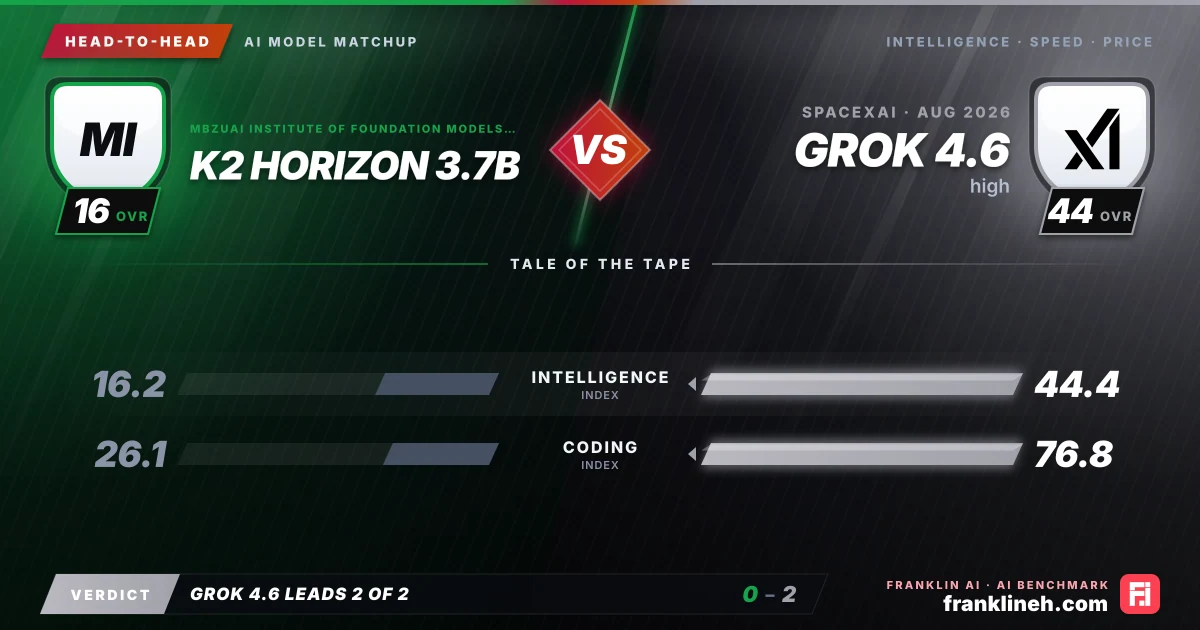
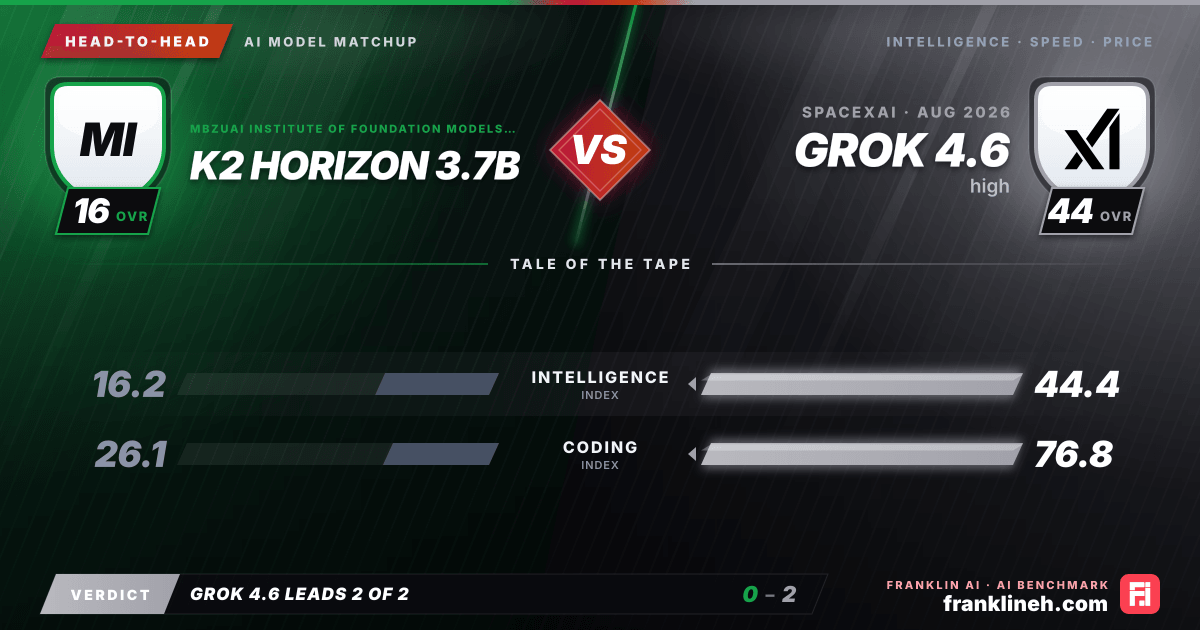
The performance disparity between K2 Horizon 3.7B and Grok 4.6 (high) is substantial across all measured metrics. Grok 4.6 (high) demonstrates a clear advantage in reasoning and technical proficiency, evidenced by its intelligence index of 44.4 compared to K2’s 16.2. This gap is even more pronounced in coding tasks, where Grok 4.6 (high) achieves a coding index of 76.8 against K2’s 26.1.
Looking at specific benchmarks, Grok 4.6 (high) consistently outperforms K2 Horizon 3.7B. On the GPQA benchmark, Grok scores 0.949 compared to K2’s 0.692. Similarly, in the LCR benchmark, Grok reaches 0.803, while K2 sits at 0.623. The HLE and SciCode benchmarks further reinforce this trend, with Grok showing a more robust capacity for handling complex, scientific, and logic-based queries. While math indices remain unknown for both models, the existing data suggests that Grok 4.6 (high) is better equipped for high-complexity technical workflows.
Speed and Cost
The economic and operational profiles of these models occupy opposite ends of the spectrum. K2 Horizon 3.7B is positioned as a zero-cost model, with input and output pricing set at $0.00 per million tokens. This makes it an accessible option for developers, researchers, or hobbyists who need to iterate without financial overhead. However, this accessibility comes with a lack of transparency regarding performance; output speed and time-to-first-token metrics for K2 are currently unknown.
In contrast, Grok 4.6 (high) operates on a clear, premium pricing model, with a blended cost of $3.00 per million tokens. Users pay $2.00 per million for input and $6.00 per million for output. This investment provides predictable performance, with an output speed of 71.327 tokens per second. While the time-to-first-token of 45.851 seconds suggests a potential delay during initial processing, the model provides a reliable throughput once generation begins, which is critical for time-sensitive enterprise applications.
Which Model Fits Which Workflow
Selecting the right model requires balancing the necessity of high-level reasoning against budgetary constraints. K2 Horizon 3.7B is best suited for low-stakes environments, such as initial prototyping, educational exploration, or tasks where the cost of failure is low and the budget is non-existent. Its lightweight nature and zero-cost structure allow for extensive experimentation without the risk of accumulating significant usage fees.
Conversely, Grok 4.6 (high) is designed for professional and enterprise workflows that demand high accuracy. Given its superior coding and intelligence indices, it is better suited for software development, complex data analysis, and technical research. While the cost is higher, the performance reliability makes it a more suitable candidate for production pipelines where the quality of the output directly impacts project success. The model’s ability to handle more complex logic suggests it can reduce the need for human intervention in technical tasks, potentially offsetting its higher per-token cost through increased efficiency.
Comments (0)
to join the discussion
No comments yet
Be the first to share your thoughts!