
What the benchmarks show
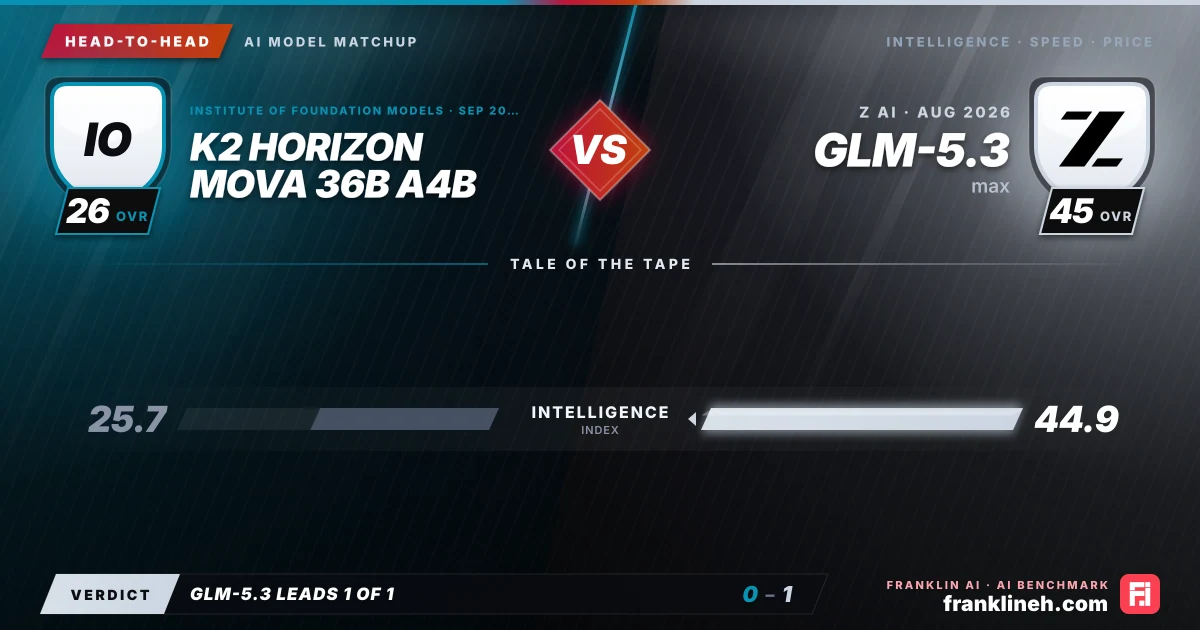
When evaluating the raw capabilities of these two models, the performance gap is significant. The GLM-5.3 (max) by Z AI consistently outperforms the K2 Horizon MoVA 36B A4B across all available metrics. In general intelligence, GLM-5.3 (max) holds an index of 44.9 compared to the K2 Horizon’s 25.7. This disparity is mirrored in the specific benchmarks: GLM-5.3 (max) achieves a GPQA score of 0.917 versus 0.822 for the K2 Horizon, and a SciCode score of 0.59 compared to 0.4.
The coding index further highlights the specialization of the GLM-5.3 (max), which registers at 74.8, while the K2 Horizon’s coding proficiency remains unknown. Similarly, the HLE benchmark shows GLM-5.3 (max) at 0.423, nearly doubling the 0.234 score of the K2 Horizon. While the K2 Horizon provides a respectable LCR score of 0.716, it falls short of the 0.796 achieved by the GLM-5.3 (max). These figures suggest that while the K2 Horizon is a functional model, it lacks the depth of reasoning and technical precision found in the GLM-5.3 (max).
Speed and cost
The economic and operational profiles of these models present a stark contrast. The K2 Horizon MoVA 36B A4B is positioned as a zero-cost utility, with both input and output pricing set at $0.00 per million tokens. This makes it an attractive option for developers looking to integrate AI without incurring operational expenses. However, this accessibility comes at the cost of transparency; the model’s output speed and time-to-first-token metrics are currently unknown, which may introduce uncertainty for time-sensitive applications.
In contrast, GLM-5.3 (max) operates on a transparent, albeit premium, pricing model. Users pay $1.40 per million input tokens and $4.40 per million output tokens, resulting in a blended cost of $2.15 per million tokens. While this represents a clear financial commitment, it is accompanied by defined performance metrics: an output speed of 53.172 tokens per second and a time-to-first-token of 2.992 seconds. For enterprise or production environments where latency predictability is as important as cost, the GLM-5.3 (max) provides the necessary data to plan infrastructure effectively.
Which model fits which workflow
Choosing between these models requires an assessment of project requirements. The K2 Horizon MoVA 36B A4B is best suited for non-critical, exploratory, or high-volume tasks where budget constraints are the primary concern. Its zero-cost structure allows for extensive testing and prototyping without financial risk. However, because its coding and mathematical capabilities are largely undefined, it is less suitable for complex software development or rigorous scientific analysis.
GLM-5.3 (max) is designed for high-performance workflows. Its strong coding index and superior intelligence scores make it the preferred candidate for complex software engineering, data analysis, and research-heavy tasks. The investment in its per-token cost is offset by the reliability of its performance metrics and its proven ability to handle more challenging reasoning tasks. Organizations that prioritize accuracy and speed over cost-minimization will find the GLM-5.3 (max) to be the more robust tool for their operational needs.
Comments (0)
to join the discussion
No comments yet
Be the first to share your thoughts!