
What the Benchmarks Show
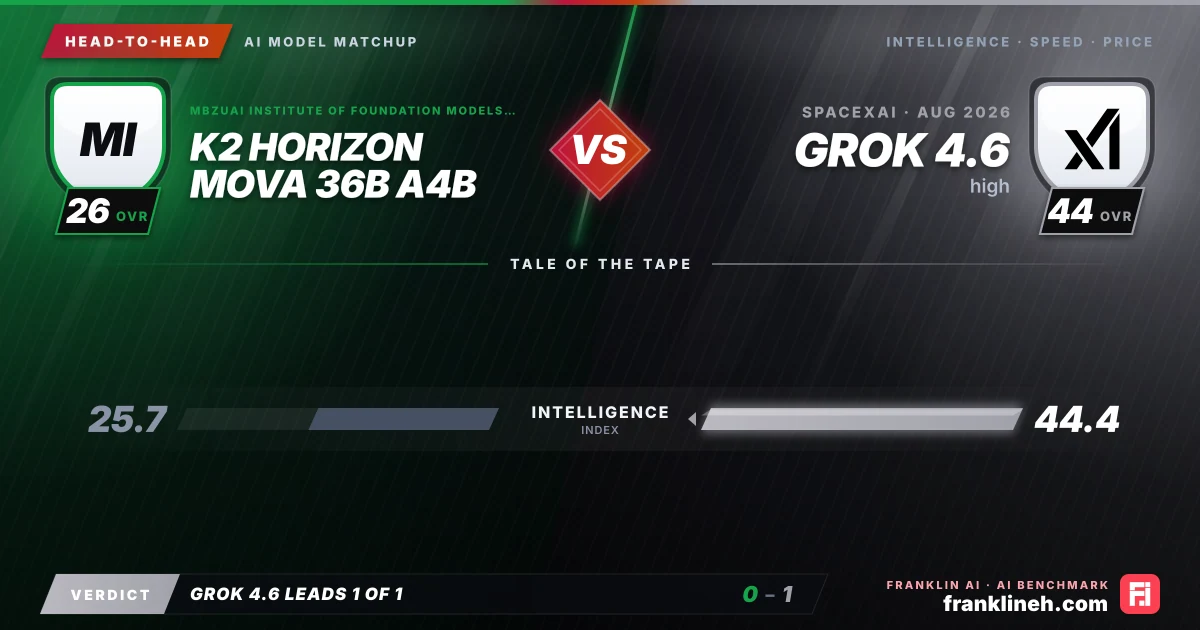
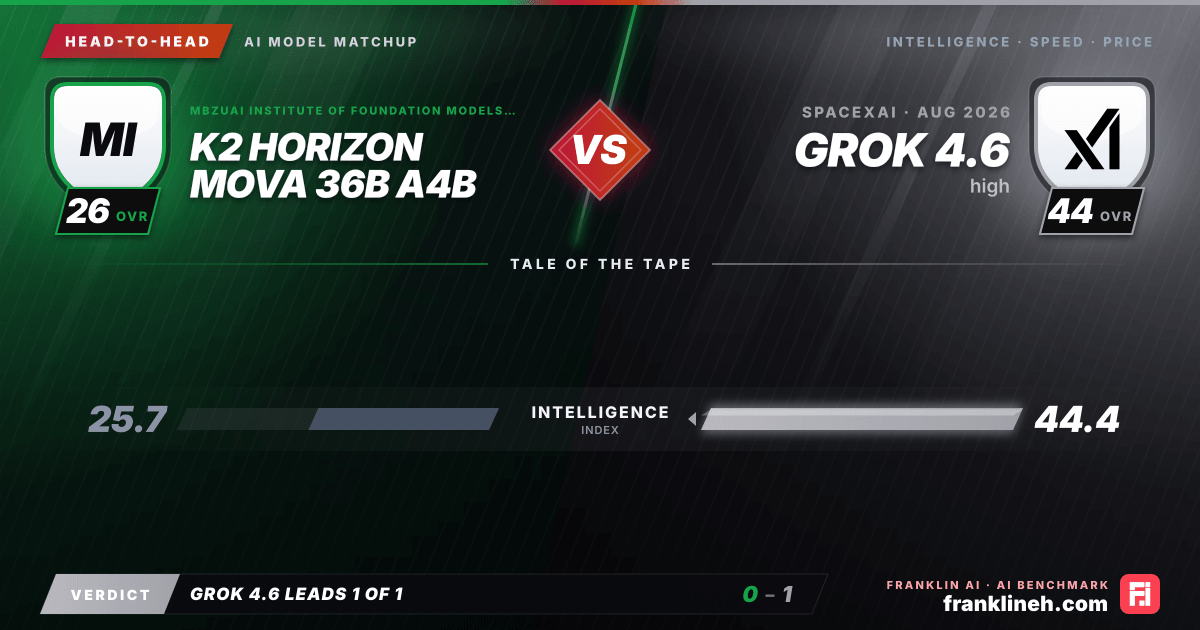
When evaluating the K2 Horizon MoVA 36B A4B and Grok 4.6 (high), the performance gap is significant across nearly all measured domains. Grok 4.6 (high) demonstrates a clear advantage in general intelligence, recording an index of 44.4 compared to the 25.7 reported for the K2 Horizon. This disparity is mirrored in the benchmark results: Grok 4.6 (high) achieves a GPQA score of 0.949 and an HLE score of 0.429, outperforming the K2 Horizon’s scores of 0.822 and 0.234, respectively.
In specialized tasks, the gap remains consistent. Grok 4.6 (high) shows a strong coding index of 76.8 and a SciCode score of 0.565, while the K2 Horizon MoVA 36B A4B trails with a SciCode score of 0.4. The LCR benchmark, which measures logical reasoning, also favors Grok 4.6 (high) at 0.803, compared to 0.717 for the K2 Horizon. While the K2 Horizon remains a capable model, the data suggests that Grok 4.6 (high) is better suited for tasks requiring deep reasoning and complex technical execution.
Speed and Cost
The most striking difference between these two models lies in their economic and operational profiles. The K2 Horizon MoVA 36B A4B is positioned as a zero-cost utility, with input and output pricing set at $0.00 per million tokens. This makes it an attractive option for high-volume research or exploratory tasks where budget constraints are the primary concern. However, this cost-efficiency comes with a lack of transparency regarding its performance metrics, as both output speed and time to first token remain unknown.
In contrast, Grok 4.6 (high) operates on a transparent, albeit premium, pricing model. Users can expect to pay $2.00 per million tokens for input and $6.00 per million for output, resulting in a blended cost of $3.00 per million tokens. For this investment, users gain predictable performance, with an output speed of 71.327 tokens per second and a time to first token of 45.851 seconds. This predictability is essential for enterprise applications where latency and throughput are critical to maintaining workflow stability.
Which Model Fits Which Workflow
Selecting the appropriate model requires balancing the need for high-performance reasoning against the constraints of your operational budget. Grok 4.6 (high) is clearly designed for demanding workflows. Its high coding index and strong performance on scientific and logical benchmarks make it an ideal candidate for software development, technical research, and complex problem-solving where accuracy is paramount. The model’s defined latency metrics further support its integration into production-grade applications that require consistent response times.
On the other hand, the K2 Horizon MoVA 36B A4B serves a different niche. Its zero-cost structure makes it an excellent tool for academic researchers, students, or developers who need to run large-scale experiments without incurring significant financial overhead. While it does not reach the same intelligence benchmarks as Grok 4.6 (high), its accessibility provides a low-barrier entry point for projects that may not require the highest tier of reasoning capability but benefit from the ability to process large datasets without cost.
Decision Takeaway
Ultimately, the decision rests on whether your project requires the high-fidelity reasoning and speed of Grok 4.6 (high) or the cost-free accessibility of the K2 Horizon MoVA 36B A4B. If your workflow involves critical coding or complex logical analysis, the performance premium of Grok 4.6 (high) is likely worth the investment. If you are operating in a cost-sensitive environment or conducting exploratory research, the K2 Horizon model provides a viable and efficient path forward.
Comments (0)
to join the discussion
No comments yet
Be the first to share your thoughts!