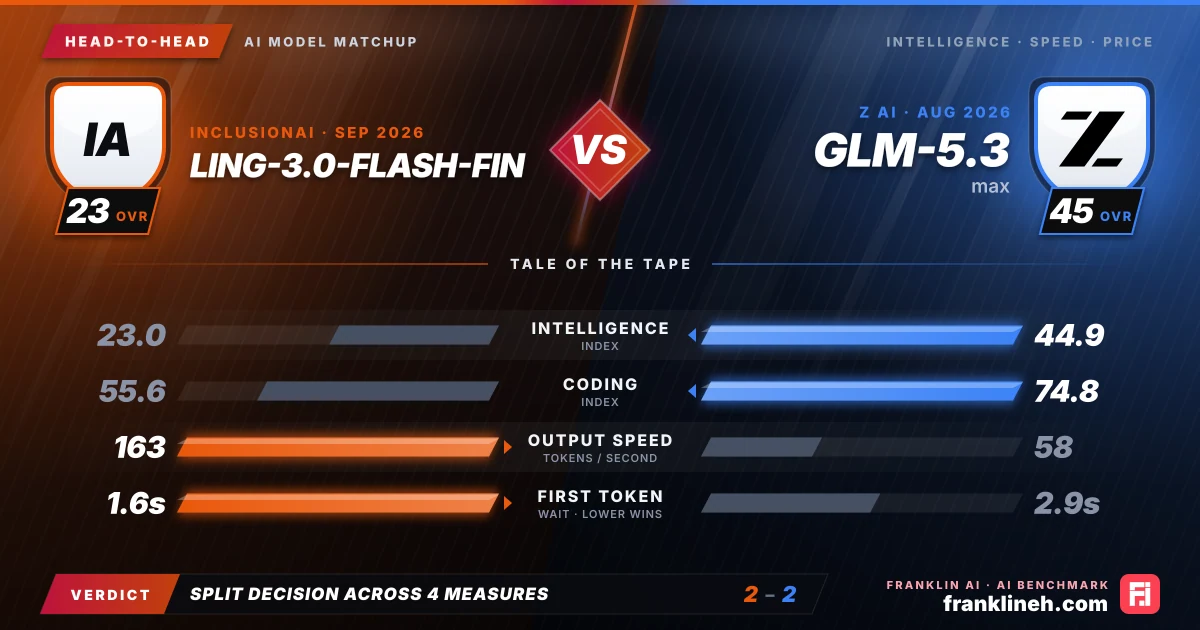
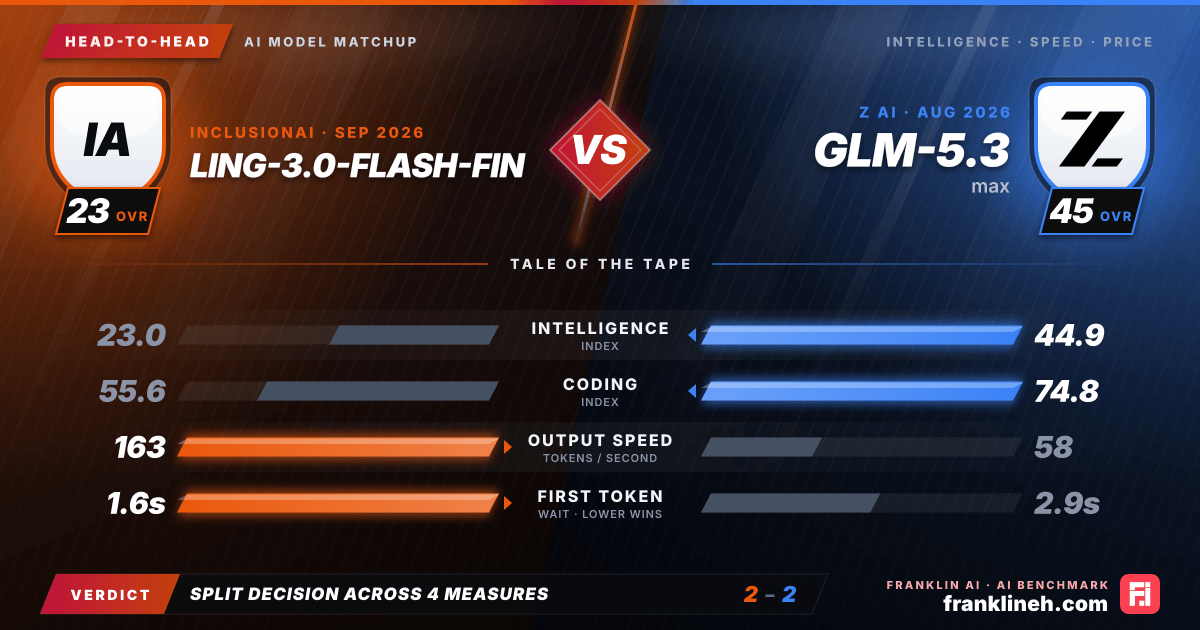
Head-to-head AI model comparison graphic: Ling-3.0-flash-Fin (InclusionAI) vs GLM-5.3 (Z AI). Intelligence index 23.0 vs 44.9; coding index 55.6 vs 74.8; output speed 163 vs 58 tokens per second; time to first token 1.6s vs 2.9s. franklineh.com
Ling-3.0-flash-Fin vs GLM-5.3: head-to-head AI benchmark comparison. Ling-3.0-flash-Fin leads on output speed and time to first token; GLM-5.3 leads on intelligence index and coding index.
Head to headUpdated

Ling-3.0-flash-Fin vs. GLM-5.3 (max): A Comparative Analysis

This analysis compares InclusionAI’s Ling-3.0-flash-Fin and Z AI’s GLM-5.3 (max), evaluating their distinct trade-offs in computational speed, cost-efficiency, and benchmark performance to help users determine the optimal model for their specific technical requirements.

Pick it for Ling-3.0-flash-Fin

  • Latency-sensitive chat, support, and interactive product flows
  • Longer responses where sustained output speed matters
  • Higher-volume workloads where blended token cost matters

Pick it for GLM-5.3 · Max

  • Workloads that benefit from the stronger overall intelligence score
  • Coding and agentic tasks where the benchmark edge matters
  • Teams already standardized on Z AI

By the numbers

These figures describe the two model configurations shown here. A dash means the source snapshot had no usable figure for that metric. Scores, speed and API pricing may change as providers update models.

MetricLing-3.0-flash-FinGLM-5.3 (max)
Intelligence Index23.044.9
Coding Index55.674.8
Input price (per 1M tokens)–$1.40
Output price (per 1M tokens)–$4.40
Output speed (tokens/s)16358
Time to first token1.6s2.9s
Release date2026-09-112026-08-18

Understanding Benchmark Performance

When evaluating the cognitive capabilities of these two models, the data reveals a clear divide in their intended applications. GLM-5.3 (max) demonstrates a significantly higher intelligence index of 44.9 compared to Ling-3.0-flash-Fin’s 23. This disparity is mirrored in their coding indices, where GLM-5.3 (max) scores 74.8 against Ling-3.0-flash-Fin’s 55.6. The benchmark data supports this trend; GLM-5.3 (max) outperforms its counterpart across all measured metrics, including HLE (0.423 vs 0.226), SciCode (0.59 vs 0.424), and LCR (0.797 vs 0.737). While neither model provides data for math-specific indices, the existing scores suggest that GLM-5.3 (max) is better suited for complex, logic-heavy workflows.

Speed and Cost Trade-offs

The operational profiles of these models present a stark contrast in resource management. Ling-3.0-flash-Fin, released on September 11, 2026, is optimized for extreme efficiency, offering a blended price of $0.00 per million tokens. This makes it a highly attractive option for developers looking to scale applications without incurring direct inference costs. Furthermore, its performance metrics are built for speed, delivering an output rate of 163.175 tokens per second with a time-to-first-token of 1.577 seconds.

In comparison, GLM-5.3 (max), released on August 18, 2026, operates at a premium. With a blended cost of $2.15 per million tokens, it requires a higher budget for large-scale implementations. Its performance is notably slower, with an output speed of 58.102 tokens per second and a time-to-first-token of 2.906 seconds. These figures indicate that while GLM-5.3 (max) provides deeper reasoning, it does so at the cost of both latency and financial overhead.

Aligning Models with Workflows

Selecting the right model requires balancing the need for intelligence against the constraints of the production environment. Ling-3.0-flash-Fin is best utilized in high-frequency, low-complexity environments where the primary goal is to minimize latency and eliminate cost. Its rapid response time makes it ideal for real-time data processing, simple classification tasks, or high-volume API interactions where the model's lower intelligence index is sufficient for the task at hand.

GLM-5.3 (max) is better suited for workflows that demand high accuracy and complex problem-solving. Its superior coding index and intelligence scores make it the appropriate choice for software development assistance, technical analysis, or nuanced content generation where the cost of a mistake outweighs the cost of inference. While it is slower and more expensive, the trade-off is a model capable of handling more sophisticated instructions and producing higher-quality outputs in technical domains.

Decision Takeaway

Ultimately, the decision rests on the specific demands of your project. If your architecture requires high throughput and zero-cost inference, Ling-3.0-flash-Fin is the clear winner. If your project involves complex reasoning, advanced coding, or tasks where accuracy is paramount, the investment in GLM-5.3 (max) is justified by its stronger benchmark performance.

Common questions about GLM-5.3 max and Ling-3.0-flash-Fin

Is Ling-3.0-flash-Fin better than GLM-5.3 max?

Not across the board: GLM-5.3 max scores higher on the intelligence index, 44.9 to 23.0; and Ling-3.0-flash-Fin streams output 2.8 times as fast.

Are GLM-5.3 max and Ling-3.0-flash-Fin from the same company?

GLM-5.3 max is made by Z AI and Ling-3.0-flash-Fin by InclusionAI. GLM-5.3 max was released on August 18, 2026 and Ling-3.0-flash-Fin on September 11, 2026.

When were GLM-5.3 max and Ling-3.0-flash-Fin released?

Ling-3.0-flash-Fin is newer. It was released on September 11, 2026, 24 days after GLM-5.3 max (August 18, 2026).

Which is better for coding, GLM-5.3 max or Ling-3.0-flash-Fin?

GLM-5.3 max has the higher coding index, 74.8 against 55.6.

Does GLM-5.3 max respond faster than Ling-3.0-flash-Fin?

Ling-3.0-flash-Fin generates output faster, at 163 tokens per second against 58 tokens per second. Ling-3.0-flash-Fin reaches its first token sooner (1.6 seconds against 2.9 seconds).

Final whistle

The choice between these models depends on your priority: Ling-3.0-flash-Fin is an exceptionally cost-effective, high-speed solution for high-volume tasks where latency is critical. Conversely, GLM-5.3 (max) is the superior choice for complex reasoning and coding tasks that demand higher intelligence, provided the user can accommodate the associated costs and slower token generation. Evaluate whether your project requires raw throughput or advanced cognitive capability to make the final selection.

Where the numbers come from

The scores, speed and prices in this comparison come from independent third-party model evaluations that Franklin AI syncs each day, and the article was written from a snapshot of them. For the latest results, open the Ling-3.0-flash-Fin and GLM-5.3 (max) pages. The AI Benchmark methodology explains how that data is collected and shown.

Comments (0)

No comments yet

Be the first to share your thoughts!