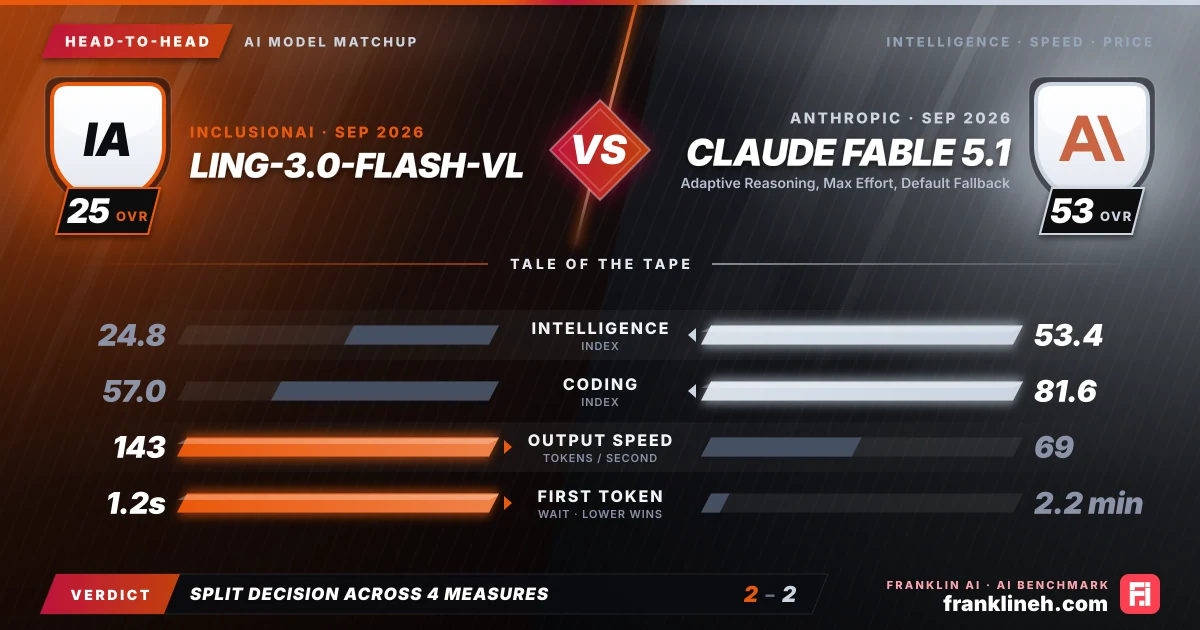
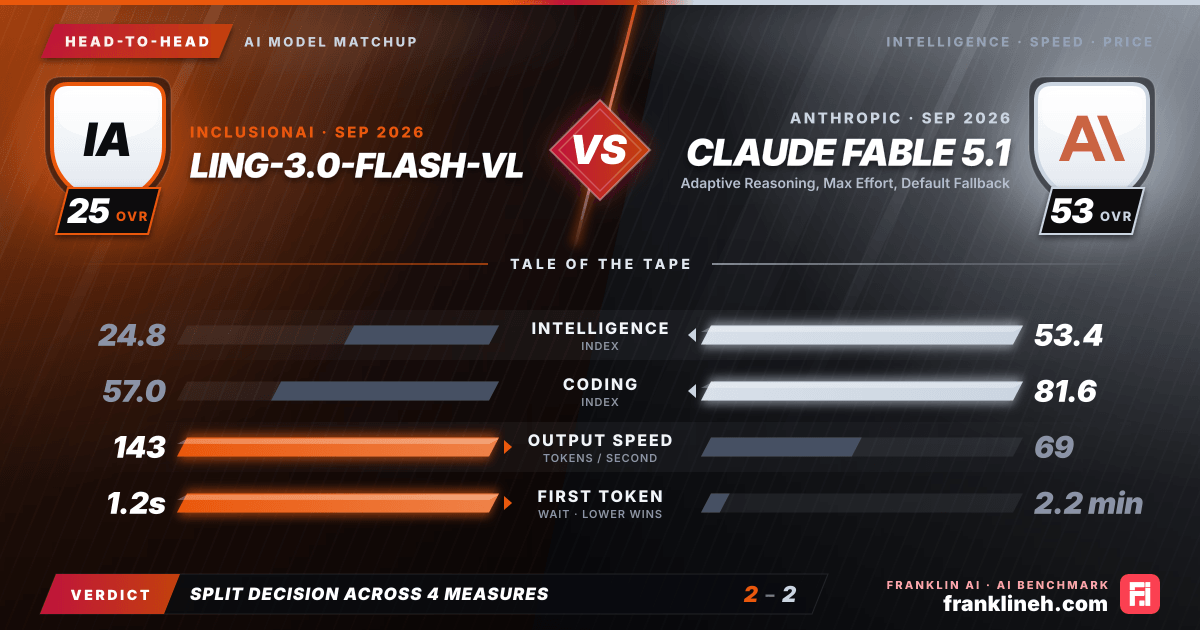
Head-to-head AI model comparison graphic: Ling-3.0-flash-VL (InclusionAI) vs Claude Fable 5.1 (Anthropic). Intelligence index 24.8 vs 53.4; coding index 57.0 vs 81.6; output speed 143 vs 69 tokens per second; time to first token 1.2s vs 2.2 min. franklineh.com
Ling-3.0-flash-VL vs Claude Fable 5.1: head-to-head AI benchmark comparison. Ling-3.0-flash-VL leads on output speed and time to first token; Claude Fable 5.1 leads on intelligence index and coding index.
Head to headUpdated

Ling-3.0-flash-VL vs. Claude Fable 5.1: A Comparative Analysis

This comparison evaluates InclusionAI’s Ling-3.0-flash-VL and Anthropic’s Claude Fable 5.1. While Ling-3.0-flash-VL offers unmatched cost-efficiency and rapid response times, Claude Fable 5.1 provides superior reasoning and coding capabilities for complex, high-stakes tasks.

Pick it for Ling-3.0-flash-VL

  • Latency-sensitive chat, support, and interactive product flows
  • Longer responses where sustained output speed matters
  • Higher-volume workloads where blended token cost matters

Pick it for Claude Fable 5.1 · Adaptive Reasoning, Max Effort, Default Fallback

  • Workloads that benefit from the stronger overall intelligence score
  • Coding and agentic tasks where the benchmark edge matters
  • Teams already standardized on Anthropic

By the numbers

These figures describe the two model configurations shown here. A dash means the source snapshot had no usable figure for that metric. Scores, speed and API pricing may change as providers update models.

MetricLing-3.0-flash-VLClaude Fable 5.1 (Adaptive Reasoning, Max Effort, Default Fallback)
Intelligence Index24.853.4
Coding Index57.081.6
Input price (per 1M tokens)–$10.00
Output price (per 1M tokens)–$50.00
Output speed (tokens/s)14369
Time to first token1.2s2.2 min
Release date2026-09-102026-09-01

What the benchmarks show

When evaluating the intelligence and technical proficiency of these two models, a clear performance gap emerges. Claude Fable 5.1, released on September 1, 2026, demonstrates a significant lead in core metrics, boasting an intelligence index of 53.4 and a coding index of 81.6. In contrast, InclusionAI’s Ling-3.0-flash-VL, released on September 10, 2026, records an intelligence index of 24.8 and a coding index of 57. The benchmark data reinforces this disparity; Claude Fable 5.1 outperforms Ling-3.0-flash-VL across all measured categories, including GPQA (0.937 vs 0.862), HLE (0.591 vs 0.22), SciCode (0.631 vs 0.442), and LCR (0.853 vs 0.783).

While Ling-3.0-flash-VL remains competitive in specific tasks, Claude Fable 5.1 is objectively more capable in complex reasoning and technical problem-solving. Users requiring high-level synthesis or intricate code generation will likely find the higher indices of the Claude model necessary for reliable results, whereas Ling-3.0-flash-VL is better suited for tasks where extreme precision is secondary to throughput.

Speed and cost

The most striking difference between these models lies in their operational economics and latency profiles. Ling-3.0-flash-VL is positioned as a zero-cost utility, with input and output pricing set at $0.00 per million tokens. This makes it an exceptionally attractive option for developers building high-volume applications where budget constraints are tight. Furthermore, its performance is optimized for speed, delivering an output rate of 142.927 tokens per second with a time-to-first-token of just 1.213 seconds.

Claude Fable 5.1 operates in a different tier, with a blended cost of $20.00 per million tokens. This cost reflects the model's intensive reasoning architecture. The trade-off for this capability is a slower response time, with an output speed of 69.039 tokens per second and a significant time-to-first-token of 131.814 seconds. While Ling-3.0-flash-VL is built for near-instantaneous interaction, Claude Fable 5.1 requires a more patient workflow, reflecting the computational load of its adaptive reasoning and max-effort settings.

Which model fits which workflow

Selecting the right model requires balancing the need for deep intelligence against the requirements for operational agility. Ling-3.0-flash-VL is an ideal candidate for high-frequency, low-complexity tasks such as real-time data extraction, simple classification, or large-scale automation where cost-per-request must be minimized. Its rapid time-to-first-token makes it highly responsive for user-facing applications where latency is the primary bottleneck.

Claude Fable 5.1 is better suited for workflows that demand high cognitive overhead. Its performance in coding and complex reasoning makes it the superior choice for software development, scientific research, and advanced analytical tasks. While the cost and latency are higher, the model’s ability to handle complex prompts with greater accuracy justifies the investment for mission-critical applications where the cost of an error outweighs the cost of the token usage.

Decision takeaway

The decision between these models is a classic trade-off between efficiency and capability. Ling-3.0-flash-VL offers a frictionless, high-speed experience that is virtually free to operate, making it a powerful tool for scaling simple tasks. Claude Fable 5.1, however, provides the depth and reasoning power required for advanced technical work. By aligning your project’s specific requirements for accuracy, budget, and latency against these profiles, you can determine which model provides the best value for your specific use case.

Common questions about Claude Fable 5.1 Adaptive Reasoning and Ling-3.0-flash-VL

Is Ling-3.0-flash-VL better than Claude Fable 5.1 Adaptive Reasoning?

It depends on what you need: Claude Fable 5.1 Adaptive Reasoning scores higher on the intelligence index, 53.4 to 24.8; and Ling-3.0-flash-VL streams output 2.1 times as fast.

When were Claude Fable 5.1 Adaptive Reasoning and Ling-3.0-flash-VL released?

Ling-3.0-flash-VL is newer. It was released on September 10, 2026, 9 days after Claude Fable 5.1 Adaptive Reasoning (September 1, 2026).

Who makes Claude Fable 5.1 Adaptive Reasoning and Ling-3.0-flash-VL?

Claude Fable 5.1 Adaptive Reasoning is made by Anthropic and Ling-3.0-flash-VL by InclusionAI. Claude Fable 5.1 Adaptive Reasoning was released on September 1, 2026 and Ling-3.0-flash-VL on September 10, 2026.

Is Claude Fable 5.1 Adaptive Reasoning or Ling-3.0-flash-VL better at coding?

Claude Fable 5.1 Adaptive Reasoning has the higher coding index, 81.6 against 57.0.

Which is faster, Claude Fable 5.1 Adaptive Reasoning or Ling-3.0-flash-VL?

Ling-3.0-flash-VL generates output faster, at 143 tokens per second against 69 tokens per second. Ling-3.0-flash-VL reaches its first token sooner (1.2 seconds against 2.2 minutes).

Final whistle

Choose Ling-3.0-flash-VL if your workflow prioritizes high-volume, low-latency tasks where cost-efficiency is paramount. Conversely, select Claude Fable 5.1 for complex reasoning, advanced coding, or research-intensive projects where accuracy and model intelligence are the primary drivers of success. The choice ultimately hinges on whether your application requires the raw speed of a flash model or the deep, nuanced performance of a high-effort reasoning engine.

Where the numbers come from

The scores, speed and prices in this comparison come from independent third-party model evaluations that Franklin AI syncs each day, and the article was written from a snapshot of them. For the latest results, open the Ling-3.0-flash-VL and Claude Fable 5.1 (Adaptive Reasoning, Max Effort, Default Fallback) pages. The AI Benchmark methodology explains how that data is collected and shown.

Comments (0)

No comments yet

Be the first to share your thoughts!