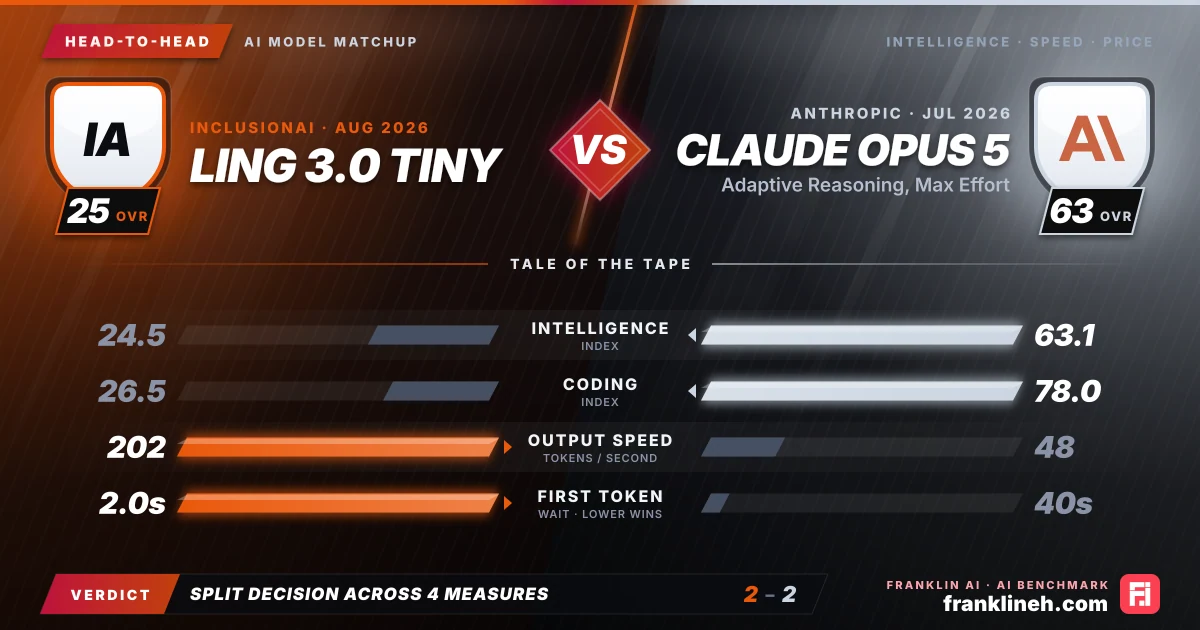
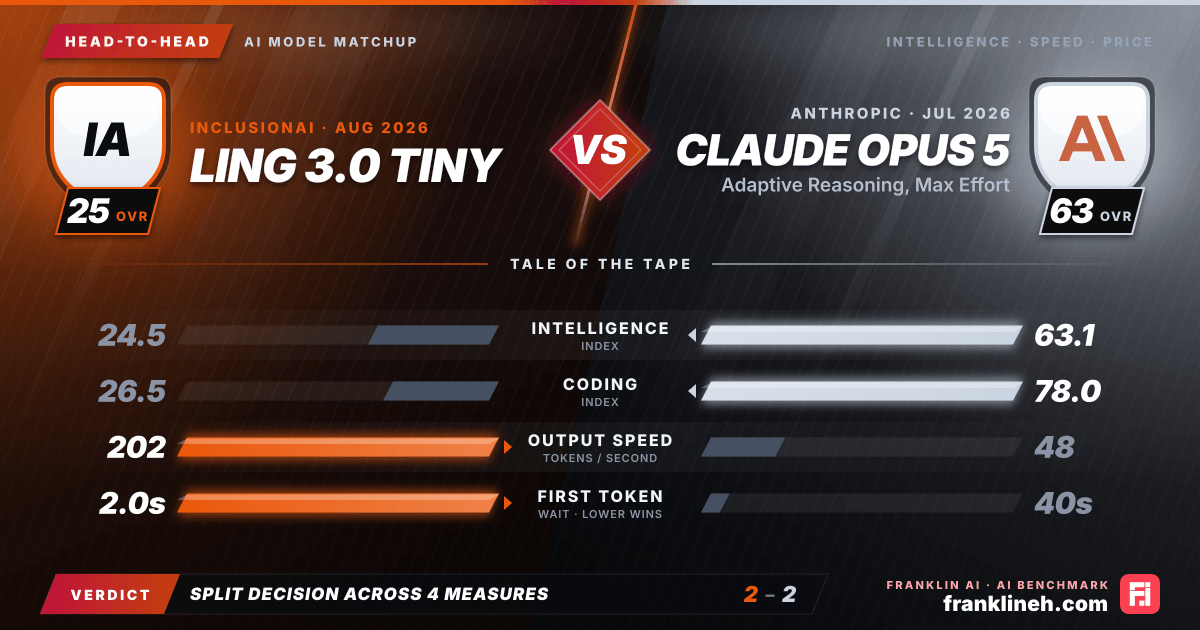
Head-to-head AI model comparison graphic: Ling 3.0 Tiny (InclusionAI) vs Claude Opus 5 (Anthropic). Intelligence index 24.5 vs 63.1; coding index 26.5 vs 78.0; output speed 202 vs 48 tokens per second; time to first token 2.0s vs 40s. franklineh.com
Ling 3.0 Tiny vs Claude Opus 5: head-to-head AI benchmark comparison. Ling 3.0 Tiny leads on output speed and time to first token; Claude Opus 5 leads on intelligence index and coding index.
Head to headUpdated

Ling 3.0 Tiny vs. Claude Opus 5: Balancing Efficiency and Reasoning Power

This comparison evaluates the performance, cost, and architectural trade-offs between InclusionAI’s Ling 3.0 Tiny and Anthropic’s Claude Opus 5, helping users determine which model best aligns with their specific computational and budgetary requirements.

Pick it for Ling 3.0 Tiny

  • Latency-sensitive chat, support, and interactive product flows
  • Longer responses where sustained output speed matters
  • Higher-volume workloads where blended token cost matters

Pick it for Claude Opus 5 · Adaptive Reasoning, Max Effort

  • Workloads that benefit from the stronger overall intelligence score
  • Coding and agentic tasks where the benchmark edge matters
  • Teams already standardized on Anthropic

By the numbers

These figures describe the two model configurations shown here. A dash means the source snapshot had no usable figure for that metric. Scores, speed and API pricing may change as providers update models.

MetricLing 3.0 TinyClaude Opus 5 (Adaptive Reasoning, Max Effort)
Intelligence Index24.563.1
Coding Index26.578.0
Input price (per 1M tokens)–$5.00
Output price (per 1M tokens)–$25.00
Output speed (tokens/s)20248
Time to first token2.0s40s
Release date2026-08-062026-07-24

What the Benchmarks Show

The performance gap between Ling 3.0 Tiny and Claude Opus 5 is significant, reflecting their distinct design goals. Claude Opus 5, released on July 24, 2026, demonstrates a high level of reasoning capability with an intelligence index of 63.1 and a coding index of 78. Its benchmark scores—0.932 on GPQA, 0.549 on HLE, and 0.557 on SciCode—position it as a robust model for complex, multi-step cognitive tasks.

In contrast, Ling 3.0 Tiny, released on August 6, 2026, prioritizes lightweight operation. With an intelligence index of 24.5 and a coding index of 26.5, it is not designed to compete with frontier-level reasoning. Its benchmark scores, such as 0.734 on GPQA and 0.242 on SciCode, indicate a model optimized for simpler, more predictable interactions rather than deep analytical synthesis. Users should view Ling 3.0 Tiny as a specialized utility rather than a general-purpose reasoning engine.

Speed and Cost

The economic and operational profiles of these models are polar opposites. Ling 3.0 Tiny is provided at no cost, with input and output pricing set at $0.00 per million tokens. This makes it an ideal candidate for developers building high-frequency applications or internal tools where token consumption would otherwise be prohibitive. Beyond its zero-cost structure, it is remarkably fast, boasting an output speed of 202.174 tokens per second and a time-to-first-token of just 2.02 seconds.

Claude Opus 5 follows a premium pricing model, with a blended cost of $10.00 per million tokens. Its performance reflects the computational intensity of its reasoning capabilities, delivering output at 48.066 tokens per second with a significant 40.419-second time-to-first-token. While the latency is substantially higher than Ling 3.0 Tiny, this is a trade-off for the depth of processing required for complex queries.

Which Model Fits Which Workflow

Selecting the right model requires an assessment of your project's constraints. Ling 3.0 Tiny is best suited for workflows that demand rapid, low-latency responses, such as real-time chat interfaces, basic data extraction, or high-volume automated processing where budget constraints are strict. Its speed allows for a fluid user experience in applications where immediate feedback is more valuable than deep logical reasoning.

Claude Opus 5 is designed for workflows that require high-fidelity output. It excels in environments where the model must navigate complex codebases, perform rigorous scientific analysis, or handle nuanced instructions that a smaller model might misinterpret. While the latency and cost are higher, the reduction in error rates and the increased depth of reasoning make it the superior choice for professional-grade development and research environments.

Decision Takeaway

Ultimately, the decision rests on whether your application prioritizes throughput or accuracy. If you are building a system that requires thousands of inferences per hour at zero cost, Ling 3.0 Tiny is the clear winner. However, if your application is the primary interface for complex problem-solving, the investment in Claude Opus 5 will provide the necessary intelligence to handle tasks that fall outside the scope of smaller, faster models.

Frequently asked questions

Is Ling 3.0 Tiny better than Claude Opus 5 Adaptive Reasoning?

It depends on what you need: Claude Opus 5 Adaptive Reasoning scores higher on the intelligence index, 63.1 to 24.5; and Ling 3.0 Tiny streams output 4.2 times as fast.

Does Claude Opus 5 Adaptive Reasoning respond faster than Ling 3.0 Tiny?

Ling 3.0 Tiny generates output faster, at 202 tokens per second against 48 tokens per second. Ling 3.0 Tiny reaches its first token sooner (2.0 seconds against 40 seconds).

Is Claude Opus 5 Adaptive Reasoning or Ling 3.0 Tiny better at coding?

Claude Opus 5 Adaptive Reasoning has the higher coding index, 78.0 against 26.5.

Are Claude Opus 5 Adaptive Reasoning and Ling 3.0 Tiny from the same company?

Claude Opus 5 Adaptive Reasoning is made by Anthropic and Ling 3.0 Tiny by InclusionAI. Claude Opus 5 Adaptive Reasoning was released on July 24, 2026 and Ling 3.0 Tiny on August 6, 2026.

Which is newer, Claude Opus 5 Adaptive Reasoning or Ling 3.0 Tiny?

Ling 3.0 Tiny is newer. It was released on August 6, 2026, 13 days after Claude Opus 5 Adaptive Reasoning (July 24, 2026).

Final whistle

The choice between these models depends on your tolerance for latency and cost. Ling 3.0 Tiny is an exceptional tool for high-volume, cost-sensitive tasks where speed is paramount. Conversely, Claude Opus 5 is the clear choice for complex, high-stakes reasoning tasks where accuracy is non-negotiable. If your workflow involves heavy coding or intricate problem-solving, the superior intelligence of Opus 5 justifies its higher cost and slower response times.

Where the numbers come from

The scores, speed and prices in this comparison come from independent third-party model evaluations that Franklin AI syncs each day, and the article was written from a snapshot of them. For the latest results, open the Ling 3.0 Tiny and Claude Opus 5 (Adaptive Reasoning, Max Effort) pages. The AI Benchmark methodology explains how that data is collected and shown.

Comments (0)

No comments yet

Be the first to share your thoughts!