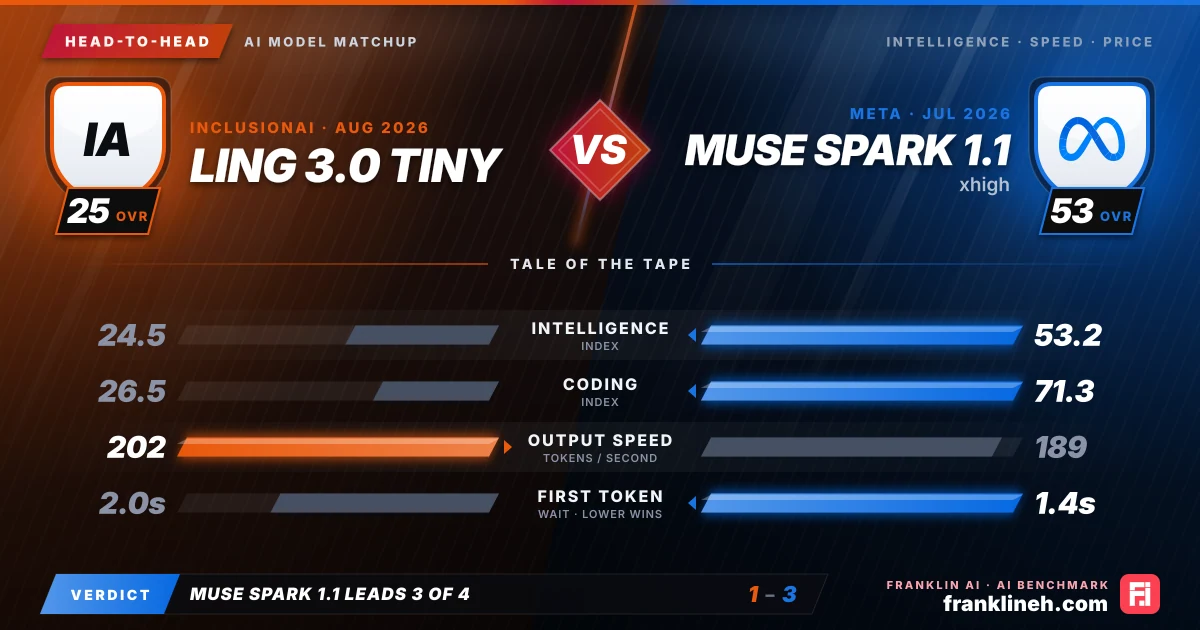
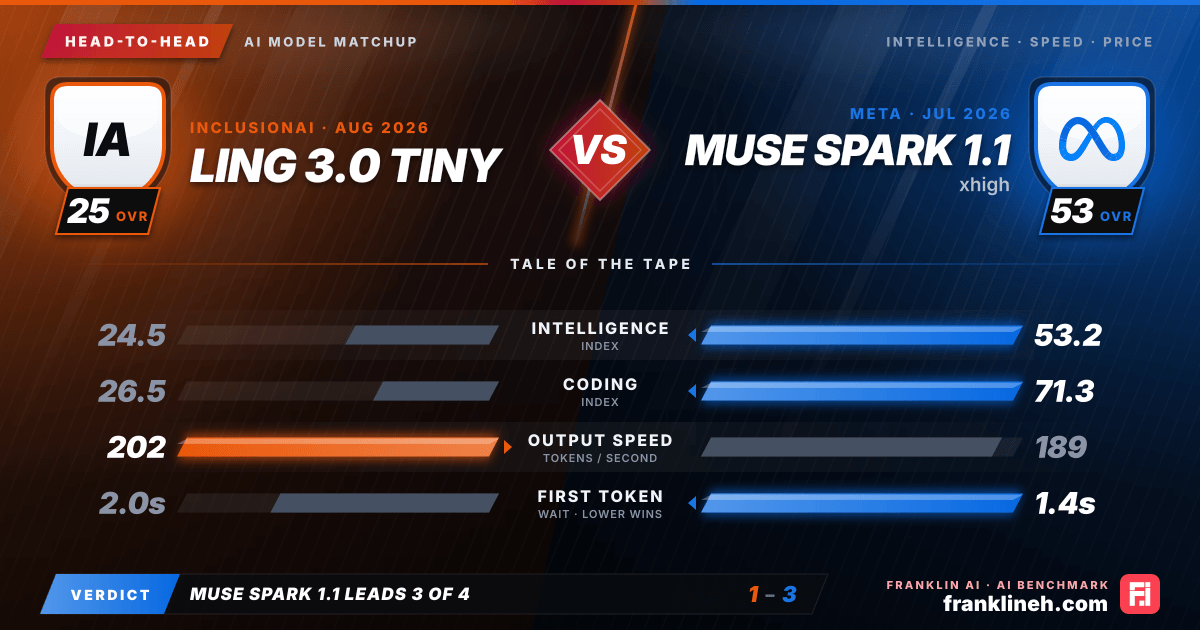
Head-to-head AI model comparison graphic: Ling 3.0 Tiny (InclusionAI) vs Muse Spark 1.1 (Meta). Intelligence index 24.5 vs 53.2; coding index 26.5 vs 71.3; output speed 202 vs 189 tokens per second; time to first token 2.0s vs 1.4s. franklineh.com
Ling 3.0 Tiny vs Muse Spark 1.1: head-to-head AI benchmark comparison. Muse Spark 1.1 leads on intelligence index, coding index and time to first token; Ling 3.0 Tiny leads on output speed.
Head to headUpdated

Ling 3.0 Tiny vs. Muse Spark 1.1 (xhigh): A Comparative Analysis

This analysis compares InclusionAI’s Ling 3.0 Tiny and Meta’s Muse Spark 1.1 (xhigh). While Ling 3.0 Tiny offers a cost-free entry point for high-speed tasks, Muse Spark 1.1 provides significantly higher reasoning capabilities and benchmark performance, catering to users who prioritize model intelligence over zero-cost infrastructure.

Pick it for Ling 3.0 Tiny

  • Longer responses where sustained output speed matters
  • Higher-volume workloads where blended token cost matters
  • Teams already standardized on InclusionAI

Pick it for Muse Spark 1.1 · Xhigh

  • Workloads that benefit from the stronger overall intelligence score
  • Coding and agentic tasks where the benchmark edge matters
  • Latency-sensitive chat, support, and interactive product flows

By the numbers

These figures describe the two model configurations shown here. A dash means the source snapshot had no usable figure for that metric. Scores, speed and API pricing may change as providers update models.

MetricLing 3.0 TinyMuse Spark 1.1 (xhigh)
Intelligence Index24.553.2
Coding Index26.571.3
Input price (per 1M tokens)–$1.25
Output price (per 1M tokens)–$4.25
Output speed (tokens/s)202189
Time to first token2.0s1.4s
Release date2026-08-062026-07-09

Understanding the Benchmark Landscape

When evaluating Ling 3.0 Tiny and Muse Spark 1.1 (xhigh), the disparity in intelligence and technical proficiency is immediately apparent. Muse Spark 1.1, released by Meta on July 9, 2026, demonstrates a significant lead in core reasoning benchmarks. With an intelligence index of 53.2 and a coding index of 71.3, it outperforms Ling 3.0 Tiny—which sits at 24.5 and 26.5 respectively—across almost every metric. Specifically, Muse Spark 1.1 achieves a GPQA score of 0.898 compared to Ling 3.0 Tiny’s 0.734, and shows a much stronger grasp of scientific code, scoring 0.582 against Ling’s 0.242. These figures suggest that Muse Spark 1.1 is better equipped for complex, multi-step agentic workflows where logical consistency is critical.

Speed and Cost Tradeoffs

InclusionAI’s Ling 3.0 Tiny, released on August 6, 2026, positions itself as an ultra-efficient, zero-cost utility. It offers a blended pricing model of $0.00 per million tokens, making it an attractive option for developers looking to scale without infrastructure overhead. In terms of raw speed, Ling 3.0 Tiny is slightly faster, outputting at 202.174 tokens per second compared to Muse Spark 1.1’s 188.527 tokens per second. However, Muse Spark 1.1 offers a faster time to first token at 1.415 seconds, compared to Ling’s 2.02 seconds. While Ling 3.0 Tiny is free, Muse Spark 1.1 carries a cost of $1.25 per million input tokens and $4.25 per million output tokens, reflecting its status as a paid frontier model designed for high-fidelity reasoning.

Aligning Models with Workflow Requirements

Selecting the right model requires balancing the need for raw intelligence against operational budget. Ling 3.0 Tiny is optimized for high-volume, low-complexity tasks where speed and cost-efficiency are the primary drivers. Its performance in benchmarks like LCR (0.586) suggests it is capable of handling standard, repetitive tasks effectively. Conversely, Meta’s Muse Spark 1.1 is engineered for sophisticated agentic tasks. Its higher HLE score (0.462 vs 0.093) indicates a superior ability to handle long-horizon reasoning and complex environments. If your workflow involves heavy coding or scientific reasoning, the higher cost of Muse Spark 1.1 is an investment in accuracy and reliability that Ling 3.0 Tiny cannot currently match.

Strategic Decision Takeaway

The decision between these two models is a classic trade-off between accessibility and capability. Ling 3.0 Tiny is an exceptional tool for rapid prototyping and high-throughput applications where budget constraints are rigid. It provides a functional baseline that is remarkably fast and entirely free. However, for enterprise-grade applications that demand high-fidelity reasoning and robust performance across diverse domains, Muse Spark 1.1 represents a more capable, albeit paid, solution. Users should assess whether the performance delta in intelligence and coding proficiency justifies the per-token cost associated with Meta’s frontier model.

Frequently asked questions

Is Ling 3.0 Tiny better than Muse Spark 1.1?

Muse Spark 1.1 leads on every measure the catalogue separates: Muse Spark 1.1 scores higher on the intelligence index, 53.2 to 24.5; and Muse Spark 1.1 reaches its first token sooner.

Does Ling 3.0 Tiny respond faster than Muse Spark 1.1?

Their output speeds are close: 202 tokens per second for Ling 3.0 Tiny and 189 tokens per second for Muse Spark 1.1. Muse Spark 1.1 reaches its first token sooner (1.4 seconds against 2.0 seconds).

Which is newer, Ling 3.0 Tiny or Muse Spark 1.1?

Ling 3.0 Tiny is newer. It was released on August 6, 2026, 28 days after Muse Spark 1.1 (July 9, 2026).

Is Ling 3.0 Tiny or Muse Spark 1.1 better at coding?

Muse Spark 1.1 has the higher coding index, 71.3 against 26.5.

Are Ling 3.0 Tiny and Muse Spark 1.1 from the same company?

Ling 3.0 Tiny is made by InclusionAI and Muse Spark 1.1 by Meta. Ling 3.0 Tiny was released on August 6, 2026 and Muse Spark 1.1 on July 9, 2026.

Final whistle

The choice between these models depends on your tolerance for cost versus your requirement for reasoning depth. If you are building high-volume applications where cost is the primary constraint, Ling 3.0 Tiny is the clear winner. However, for complex agentic tasks or high-stakes reasoning where accuracy is paramount, the performance gap in favor of Muse Spark 1.1 justifies its pricing. Most professional workflows requiring reliable, high-fidelity outputs will find the investment in Muse Spark 1.1 necessary.

Where the numbers come from

The scores, speed and prices in this comparison come from independent third-party model evaluations that Franklin AI syncs each day, and the article was written from a snapshot of them. For the latest results, open the Ling 3.0 Tiny and Muse Spark 1.1 (xhigh) pages. The AI Benchmark methodology explains how that data is collected and shown.

Comments (0)

No comments yet

Be the first to share your thoughts!