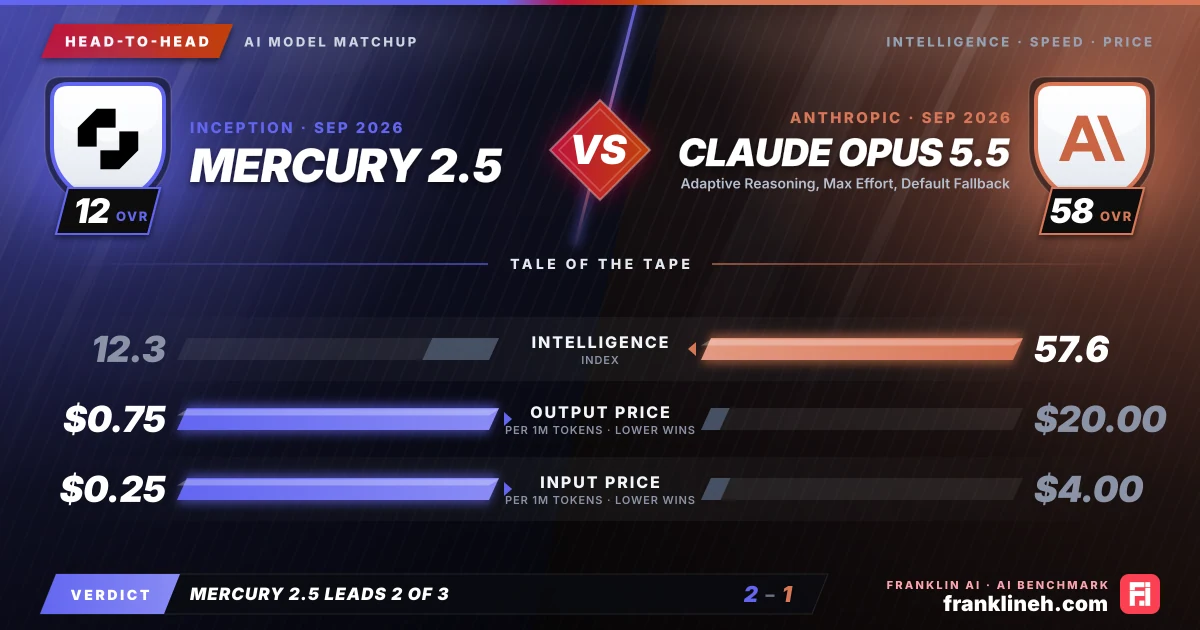
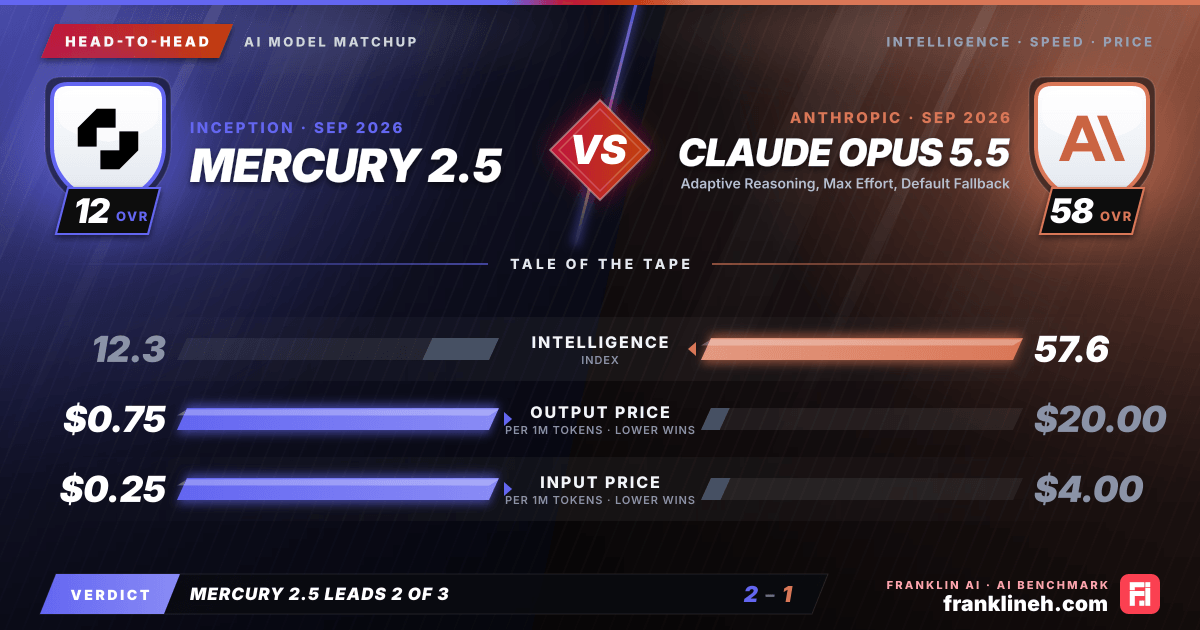
Head-to-head AI model comparison graphic: Mercury 2.5 (Inception) vs Claude Opus 5.5 (Anthropic). Intelligence index 12.3 vs 57.6; output price $0.75 vs $20.00 per million tokens; input price $0.25 vs $4.00 per million tokens. franklineh.com
Mercury 2.5 vs Claude Opus 5.5: head-to-head AI benchmark comparison. Mercury 2.5 leads on output price and input price; Claude Opus 5.5 leads on intelligence index.
Head to headUpdated

Mercury 2.5 vs. Claude Opus 5.5: A Comparative Analysis

This comparison evaluates the performance and economic trade-offs between Inception’s Mercury 2.5 and Anthropic’s Claude Opus 5.5. While Mercury 2.5 prioritizes extreme throughput and cost-efficiency, Claude Opus 5.5 offers significantly higher intelligence benchmarks, catering to distinct operational requirements in modern AI deployment.

Pick it for Mercury 2.5

  • Longer responses where sustained output speed matters
  • Higher-volume workloads where blended token cost matters
  • Teams already standardized on Inception

Pick it for Claude Opus 5.5 · Adaptive Reasoning, Max Effort, Default Fallback

  • Workloads that benefit from the stronger overall intelligence score
  • Latency-sensitive chat, support, and interactive product flows
  • Teams already standardized on Anthropic

By the numbers

These figures describe the two model configurations shown here. A dash means the source snapshot had no usable figure for that metric. Scores, speed and API pricing may change as providers update models.

MetricMercury 2.5Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback)
Intelligence Index12.357.6
Input price (per 1M tokens)$0.25$4.00
Output price (per 1M tokens)$0.75$20.00
Output speed (tokens/s)786–
Time to first token3.3s–
Release date2026-09-082026-09-22

Benchmarking Intelligence and Reasoning

When evaluating the raw performance metrics, Claude Opus 5.5 demonstrates a substantial lead over Mercury 2.5 across all provided benchmarks. With an intelligence index of 57.6 compared to Mercury’s 12.3, the disparity in reasoning capability is evident. This is further reflected in the HLE benchmark, where Opus 5.5 scores 0.614 against Mercury’s 0.118, and the SciCode benchmark, where Opus 5.5 achieves 0.669 compared to Mercury’s 0.385. The LCR benchmark follows this trend, with Opus 5.5 scoring 0.846 and Mercury 2.5 scoring 0.716. These figures suggest that Claude Opus 5.5 is better equipped for nuanced, multi-step reasoning tasks that require a higher degree of cognitive depth.

Speed and Cost Efficiency

The economic and operational profiles of these two models are starkly different. Mercury 2.5 is engineered for speed and affordability, boasting an output speed of 785.9 tokens per second and a time-to-first-token of 3.289 seconds. Its pricing is highly competitive, with a blended cost of $0.38 per million tokens. In contrast, Claude Opus 5.5 carries a significantly higher price tag, with a blended cost of $8.00 per million tokens. While specific performance speed metrics for Opus 5.5 are currently unknown, its positioning as a high-effort reasoning model suggests it is not intended to compete with Mercury 2.5 in high-throughput, low-latency environments.

Aligning Models with Workflows

Deciding between these models requires an assessment of the specific workflow demands. Mercury 2.5 is optimized for scale. Its low cost and high speed make it an ideal candidate for applications involving massive datasets, real-time data processing, or high-frequency API interactions where budget efficiency is the primary driver. It functions as a utility model, providing reliable performance for tasks that do not necessitate the highest tier of reasoning.

Claude Opus 5.5, released on September 22, 2026, is designed for complex problem-solving. Anthropic has emphasized that this model benefits from autonomous improvements in alignment failure mitigation, which may provide users with a higher degree of confidence in the model's output quality for sensitive or critical applications. While the cost is substantially higher, the investment is directed toward superior reasoning capabilities that Mercury 2.5 cannot match.

Decision Takeaway

Ultimately, the decision rests on the nature of the task. If your project requires rapid, inexpensive, and high-volume token generation, Mercury 2.5 offers a compelling value proposition. However, if your workflow involves complex logic, scientific coding, or tasks where the cost of an error outweighs the cost of computation, the intelligence and alignment advancements found in Claude Opus 5.5 make it the more appropriate, albeit expensive, choice.

Frequently asked questions

Is Mercury 2.5 better than Claude Opus 5.5 Adaptive Reasoning?

Not across the board: Claude Opus 5.5 Adaptive Reasoning scores higher on the intelligence index, 57.6 to 12.3; and Mercury 2.5 is 95% cheaper on blended price.

Are Claude Opus 5.5 Adaptive Reasoning and Mercury 2.5 from the same company?

Claude Opus 5.5 Adaptive Reasoning is made by Anthropic and Mercury 2.5 by Inception. Claude Opus 5.5 Adaptive Reasoning was released on September 22, 2026 and Mercury 2.5 on September 8, 2026.

Which is newer, Claude Opus 5.5 Adaptive Reasoning or Mercury 2.5?

Claude Opus 5.5 Adaptive Reasoning is newer. It was released on September 22, 2026, 14 days after Mercury 2.5 (September 8, 2026).

Which is cheaper, Claude Opus 5.5 Adaptive Reasoning or Mercury 2.5?

Mercury 2.5 is cheaper on a blended basis. Claude Opus 5.5 Adaptive Reasoning lists $4.00 per million input tokens and $20.00 per million output tokens; Mercury 2.5 lists $0.25 and $0.75. For 1 million input and 200,000 output tokens that is $8.00 against $0.40.

Final whistle

The choice between these models depends on the balance of cost versus reasoning depth. Mercury 2.5 is the clear choice for high-volume, latency-sensitive applications where budget is a primary constraint. Conversely, Claude Opus 5.5 is the superior tool for complex, high-stakes tasks where accuracy and reasoning capabilities are paramount. Users must decide if the performance gains of Opus justify a cost structure that is roughly 21 times higher than that of Mercury.

Where the numbers come from

The scores, speed and prices in this comparison come from independent third-party model evaluations that Franklin AI syncs each day, and the article was written from a snapshot of them. For the latest results, open the Mercury 2.5 and Claude Opus 5.5 (Adaptive Reasoning, Max Effort, Default Fallback) pages. The AI Benchmark methodology explains how that data is collected and shown.

Comments (0)

No comments yet

Be the first to share your thoughts!