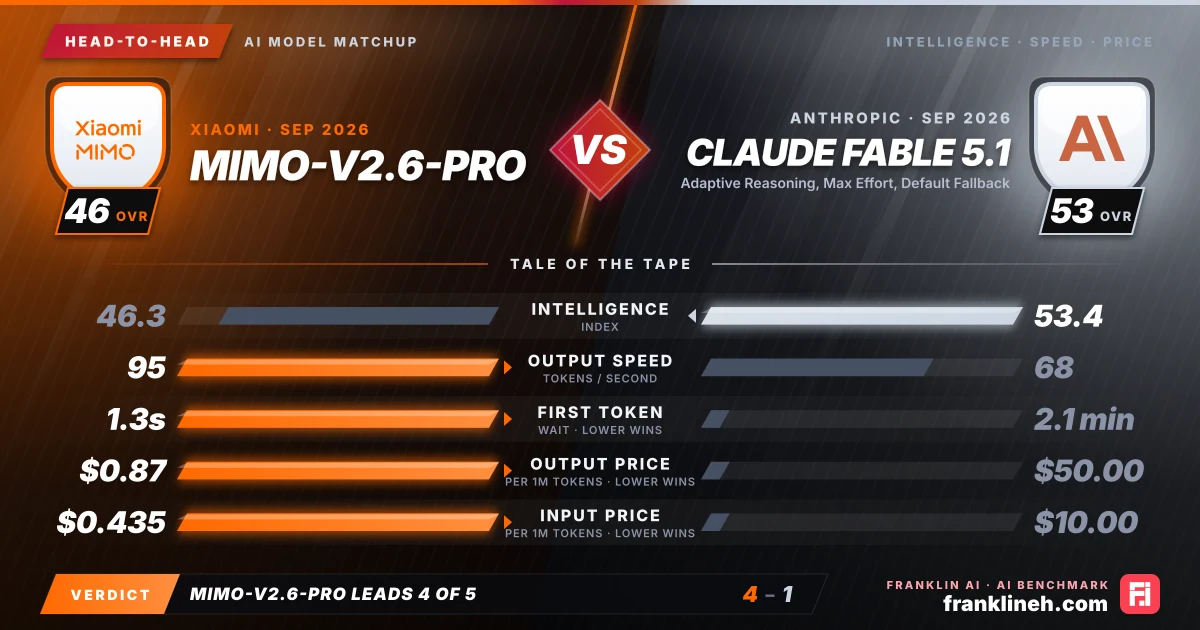
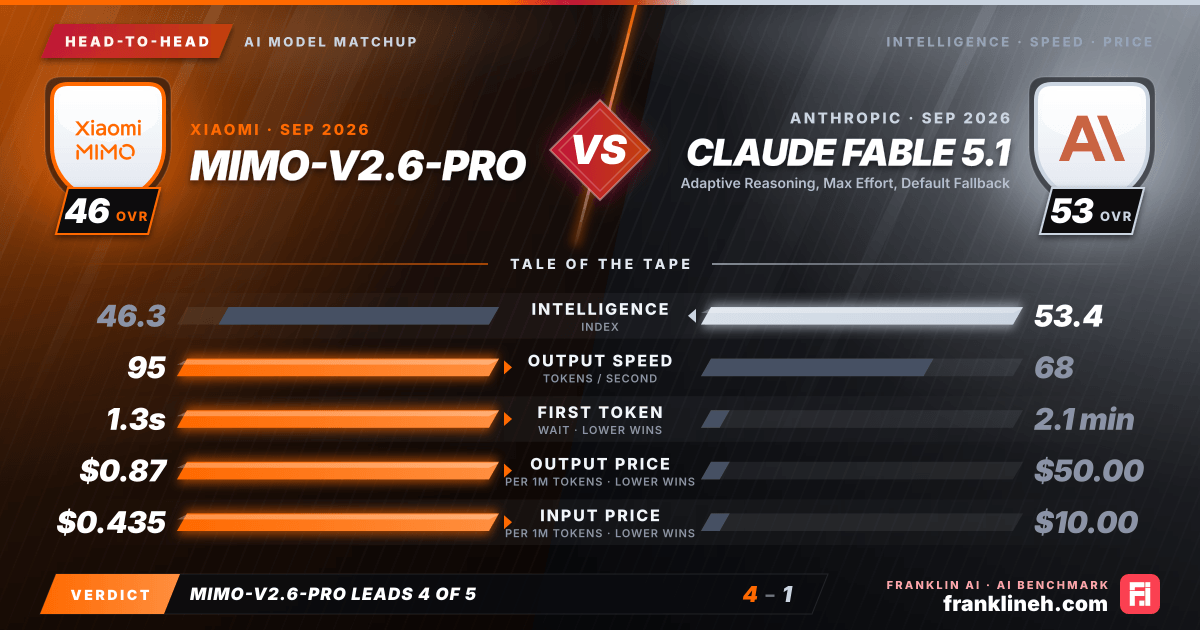
Head-to-head AI model comparison graphic: MiMo-V2.6-Pro (Xiaomi) vs Claude Fable 5.1 (Anthropic). Intelligence index 46.3 vs 53.4; output speed 95 vs 68 tokens per second; time to first token 1.3s vs 2.1 min; output price $0.87 vs $50.00 per million tokens; input price $0.435 vs $10.00 per million tokens. franklineh.com
MiMo-V2.6-Pro vs Claude Fable 5.1: head-to-head AI benchmark comparison. MiMo-V2.6-Pro leads on output speed, time to first token, output price and input price; Claude Fable 5.1 leads on intelligence index.
Head to headUpdated

Comparative Analysis: MiMo-V2.6-Pro vs. Claude Fable 5.1

This analysis evaluates the performance, cost, and architectural tradeoffs between Xiaomi’s MiMo-V2.6-Pro and Anthropic’s Claude Fable 5.1. While MiMo-V2.6-Pro offers superior speed and cost-efficiency, Claude Fable 5.1 provides higher intelligence benchmarks and advanced reasoning capabilities, creating a distinct choice based on specific project requirements.

Pick it for MiMo-V2.6-Pro

  • Latency-sensitive chat, support, and interactive product flows
  • Longer responses where sustained output speed matters
  • Higher-volume workloads where blended token cost matters

Pick it for Claude Fable 5.1 · Adaptive Reasoning, Max Effort, Default Fallback

  • Workloads that benefit from the stronger overall intelligence score
  • Coding and agentic tasks where the benchmark edge matters
  • Teams already standardized on Anthropic

By the numbers

These figures describe the two model configurations shown here. A dash means the source snapshot had no usable figure for that metric. Scores, speed and API pricing may change as providers update models.

MetricMiMo-V2.6-ProClaude Fable 5.1 (Adaptive Reasoning, Max Effort, Default Fallback)
Intelligence Index46.353.4
Coding Index–81.6
Input price (per 1M tokens)$0.435$10.00
Output price (per 1M tokens)$0.87$50.00
Output speed (tokens/s)9568
Time to first token1.3s2.1 min
Release date2026-09-212026-09-01

Understanding the Benchmark Landscape

When evaluating the intelligence of these two models, the data reveals a clear divergence in focus. Claude Fable 5.1 holds a significant lead in the Intelligence index at 53.4 compared to MiMo-V2.6-Pro’s 46.3. This gap is further reflected in the HLE and SciCode benchmarks, where Claude scores 0.591 and 0.631, respectively, outperforming MiMo’s 0.494 and 0.609. However, the LCR benchmark tells a more nuanced story, with MiMo-V2.6-Pro slightly edging out Claude at 0.863 compared to 0.853. While Claude offers higher raw intelligence and coding capabilities—boasting an 81.6 coding index—the competitive LCR score suggests that MiMo remains highly capable in specific logical or retrieval-based contexts despite its lower overall intelligence rating.

Speed and Cost Tradeoffs

Operational efficiency is where the two models diverge most sharply. MiMo-V2.6-Pro is designed for high-velocity environments, delivering an output speed of 95.064 tokens per second with a rapid time-to-first-token of 1.344 seconds. This makes it exceptionally responsive for real-time applications. In contrast, Claude Fable 5.1 prioritizes depth over speed, outputting at 67.799 tokens per second with a substantial 123.03-second time-to-first-token. This latency suggests that Claude performs significant internal processing before generating output.

These performance differences are mirrored in the pricing structure. MiMo-V2.6-Pro is highly economical, with a blended cost of $0.54 per million tokens. Claude Fable 5.1, reflecting its advanced reasoning architecture, carries a blended cost of $20.00 per million tokens. This represents a nearly 37-fold increase in cost, which must be weighed against the necessity of Claude’s higher intelligence index for a given task.

Aligning Models with Workflows

Choosing between these models requires an assessment of your specific operational constraints. MiMo-V2.6-Pro is an ideal candidate for high-throughput systems, such as customer-facing chatbots, real-time data processing, or large-scale content generation where cost-per-token is a primary concern. Its low latency ensures a seamless user experience, and its competitive LCR score indicates it can handle complex retrieval tasks effectively without the overhead of a more expensive model.

Claude Fable 5.1 is better positioned for intensive cognitive workflows. Given its high intelligence and coding indices, it is best utilized for complex software development, deep research, or reasoning-heavy tasks where accuracy is more critical than immediate response times. Anthropic’s recent advancements, including the model’s role in its own development and its autonomous improvements in alignment benchmarks, suggest that Fable 5.1 is built for reliability in high-stakes environments where the cost of an error outweighs the cost of the compute.

Decision Takeaway

Ultimately, the decision rests on whether your workflow is bottlenecked by latency and budget or by the depth of reasoning required. If your project demands rapid, cost-effective scaling, MiMo-V2.6-Pro provides the necessary performance profile. If your project requires advanced reasoning, high-level coding assistance, or the highest possible intelligence benchmarks, the investment in Claude Fable 5.1 is justified by its superior cognitive performance.

Frequently asked questions

Is Claude Fable 5.1 Adaptive Reasoning better than MiMo-V2.6-Pro?

Not across the board: Claude Fable 5.1 Adaptive Reasoning scores higher on the intelligence index, 53.4 to 46.3; MiMo-V2.6-Pro is 97% cheaper on blended price; and MiMo-V2.6-Pro streams output 1.4 times as fast.

How much do Claude Fable 5.1 Adaptive Reasoning and MiMo-V2.6-Pro cost?

MiMo-V2.6-Pro is cheaper on a blended basis. Claude Fable 5.1 Adaptive Reasoning lists $10.00 per million input tokens and $50.00 per million output tokens; MiMo-V2.6-Pro lists $0.435 and $0.87. For 1 million input and 200,000 output tokens that is $20.00 against $0.61.

Which is newer, Claude Fable 5.1 Adaptive Reasoning or MiMo-V2.6-Pro?

MiMo-V2.6-Pro is newer. It was released on September 21, 2026, 20 days after Claude Fable 5.1 Adaptive Reasoning (September 1, 2026).

Who makes Claude Fable 5.1 Adaptive Reasoning and MiMo-V2.6-Pro?

Claude Fable 5.1 Adaptive Reasoning is made by Anthropic and MiMo-V2.6-Pro by Xiaomi. Claude Fable 5.1 Adaptive Reasoning was released on September 1, 2026 and MiMo-V2.6-Pro on September 21, 2026.

Does Claude Fable 5.1 Adaptive Reasoning respond faster than MiMo-V2.6-Pro?

MiMo-V2.6-Pro generates output faster, at 95 tokens per second against 68 tokens per second. MiMo-V2.6-Pro reaches its first token sooner (1.3 seconds against 2.1 minutes).

Final whistle

The choice between these models depends on the balance of latency and reasoning depth. MiMo-V2.6-Pro is the optimal choice for high-volume, latency-sensitive applications where cost-efficiency is paramount. Conversely, Claude Fable 5.1 is better suited for complex, high-stakes tasks where intelligence and reasoning accuracy justify the significantly higher cost and slower initial response times. Users should prioritize MiMo for production-scale throughput and Claude for specialized, intensive cognitive workflows.

Where the numbers come from

The scores, speed and prices in this comparison come from independent third-party model evaluations that Franklin AI syncs each day, and the article was written from a snapshot of them. For the latest results, open the MiMo-V2.6-Pro and Claude Fable 5.1 (Adaptive Reasoning, Max Effort, Default Fallback) pages. The AI Benchmark methodology explains how that data is collected and shown.

Comments (0)

No comments yet

Be the first to share your thoughts!