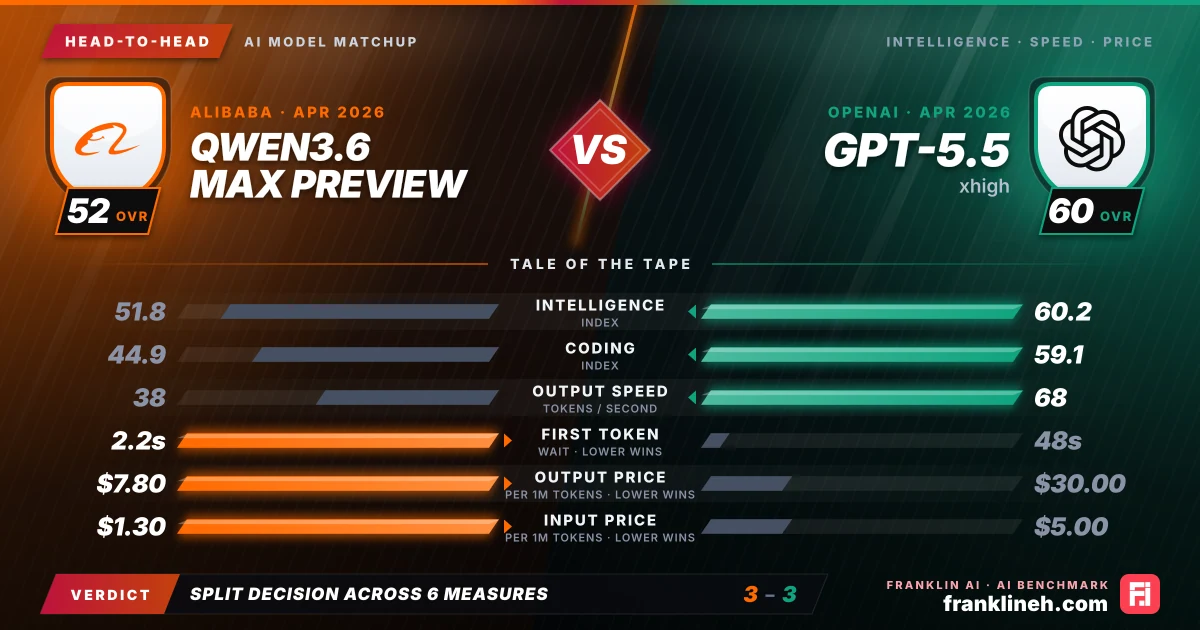
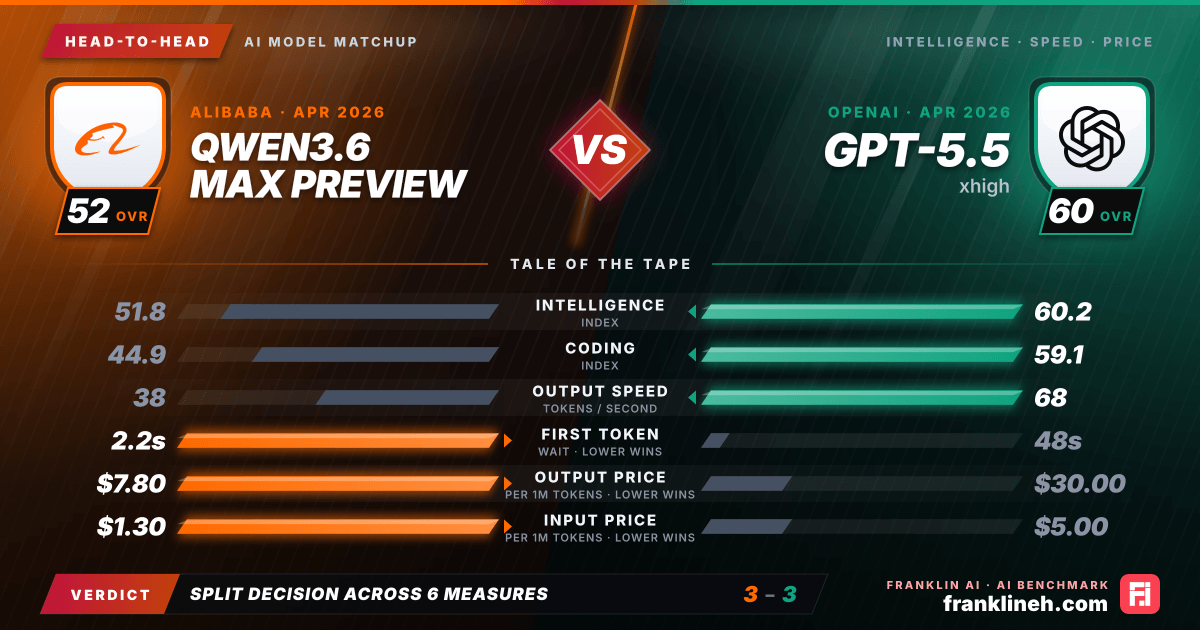
Head-to-head AI model comparison graphic: Qwen3.6 Max Preview (Alibaba) vs GPT-5.5 (OpenAI). Intelligence index 51.8 vs 60.2; coding index 44.9 vs 59.1; output speed 38 vs 68 tokens per second; time to first token 2.2s vs 48s; output price $7.80 vs $30.00 per million tokens; input price $1.30 vs $5.00 per million tokens. franklineh.com
Qwen3.6 Max Preview vs GPT-5.5: head-to-head AI benchmark comparison. Qwen3.6 Max Preview leads on time to first token, output price and input price; GPT-5.5 leads on intelligence index, coding index and output speed.
Head to headUpdated

Qwen3.6 Max Preview vs. GPT-5.5 (xhigh): A Comparative Analysis

Released within days of each other in April 2026, Alibaba’s Qwen3.6 Max Preview and OpenAI’s GPT-5.5 (xhigh) represent distinct approaches to high-performance AI. While GPT-5.5 (xhigh) offers superior reasoning and coding capabilities, Qwen3.6 Max Preview provides a significantly more cost-effective and responsive alternative for high-volume tasks.

Pick it for Qwen3.6 Max Preview

  • Latency-sensitive chat, support, and interactive product flows
  • Higher-volume workloads where blended token cost matters
  • Teams already standardized on Alibaba

Pick it for GPT-5.5 · Xhigh

  • Workloads that benefit from the stronger overall intelligence score
  • Coding and agentic tasks where the benchmark edge matters
  • Longer responses where sustained output speed matters

By the numbers

These figures describe the two model configurations shown here. A dash means the source snapshot had no usable figure for that metric. Scores, speed and API pricing may change as providers update models.

MetricQwen3.6 Max PreviewGPT-5.5 (xhigh)
Intelligence Index51.860.2
Coding Index44.959.1
Input price (per 1M tokens)$1.30$5.00
Output price (per 1M tokens)$7.80$30.00
Output speed (tokens/s)3868
Time to first token2.2s48s
Release date2026-04-202026-04-23

What the Benchmarks Show

The performance data reveals a clear hierarchy in raw capability. OpenAI’s GPT-5.5 (xhigh) leads in the Intelligence index with a score of 60.2, compared to the 51.8 achieved by Alibaba’s Qwen3.6 Max Preview. This trend continues in the Coding index, where GPT-5.5 (xhigh) scores 59.1 against Qwen3.6 Max Preview’s 44.9. Across specific benchmarks, GPT-5.5 (xhigh) demonstrates a notable advantage in complex reasoning and technical tasks, scoring 0.935 on GPQA and 0.606 on TerminalBench Hard, compared to Qwen’s 0.888 and 0.439, respectively.

However, the gap is not universal. Qwen3.6 Max Preview actually outperforms GPT-5.5 (xhigh) in the TAU2 benchmark (0.959 vs 0.938) and maintains a competitive edge in instruction following, scoring 0.766 on IFBench compared to GPT-5.5’s 0.759. These results suggest that while GPT-5.5 (xhigh) is more adept at deep technical problem-solving, Qwen3.6 Max Preview is highly optimized for following specific, structured instructions.

Speed and Cost

The economic and operational trade-offs between these two models are significant. GPT-5.5 (xhigh) carries a substantial price premium, with a blended cost of $11.25 per million tokens, nearly four times the $2.92 blended cost of Qwen3.6 Max Preview. For organizations processing millions of tokens, this difference will have a profound impact on the bottom line.

Operational latency further differentiates the two. Qwen3.6 Max Preview is designed for agility, boasting a time-to-first-token of just 2.154 seconds. In contrast, GPT-5.5 (xhigh) requires 47.763 seconds to generate the first token, which may be prohibitive for real-time or interactive applications. While GPT-5.5 (xhigh) does offer a higher output speed of 68.227 tokens per second compared to Qwen’s 37.954 tokens per second, the initial wait time for the OpenAI model remains a critical factor for developers to consider.

Which model fits which workflow

Selecting between these models depends on the specific demands of your application. GPT-5.5 (xhigh) is best suited for high-stakes, complex reasoning tasks where the absolute highest level of intelligence is required and the cost-per-request is secondary to the quality of the output. Its superior coding index makes it an ideal candidate for automated software engineering, complex data analysis, and research-heavy workflows where accuracy is paramount.

Conversely, Qwen3.6 Max Preview is built for high-throughput, latency-sensitive applications. Its lower cost and rapid initial response time make it an excellent choice for customer-facing chatbots, real-time data processing pipelines, and large-scale automated content generation. It offers a balance of performance and efficiency that is difficult to match for tasks that require frequent, rapid interactions.

Decision takeaway

Ultimately, the choice between these models is a decision between peak capability and operational utility. GPT-5.5 (xhigh) is the more powerful engine, but it requires a heavier investment in both capital and latency. Qwen3.6 Max Preview provides a highly capable, efficient alternative that excels in speed and cost-effectiveness. Developers should weigh the necessity of the extra reasoning power provided by GPT-5.5 (xhigh) against the practical advantages of Qwen3.6 Max Preview’s streamlined performance.

Quick answers

Is GPT-5.5 xhigh better than Qwen3.6 Max Preview?

Not across the board: GPT-5.5 xhigh scores higher on the intelligence index, 60.2 to 51.8; Qwen3.6 Max Preview is 74% cheaper on blended price; GPT-5.5 xhigh streams output 1.8 times as fast; and Qwen3.6 Max Preview reaches its first token sooner.

How much do GPT-5.5 xhigh and Qwen3.6 Max Preview cost?

Qwen3.6 Max Preview is cheaper on a blended basis. GPT-5.5 xhigh lists $5.00 per million input tokens and $30.00 per million output tokens; Qwen3.6 Max Preview lists $1.30 and $7.80. For 1 million input and 200,000 output tokens that is $11.00 against $2.86.

When were GPT-5.5 xhigh and Qwen3.6 Max Preview released?

GPT-5.5 xhigh is newer. It was released on April 23, 2026, 3 days after Qwen3.6 Max Preview (April 20, 2026).

Which is better for coding, GPT-5.5 xhigh or Qwen3.6 Max Preview?

GPT-5.5 xhigh has the higher coding index, 59.1 against 44.9.

Which model has lower latency?

GPT-5.5 xhigh generates output faster, at 68 tokens per second against 38 tokens per second. Qwen3.6 Max Preview reaches its first token sooner (2.2 seconds against 48 seconds). Counting the first-token wait, Qwen3.6 Max Preview finishes short replies first and GPT-5.5 xhigh pulls ahead beyond about 3,900 tokens.

Final whistle

Choose GPT-5.5 (xhigh) if your primary requirement is peak intelligence and coding performance, provided your workflow can tolerate higher costs and longer initial latency. If you prioritize operational efficiency, rapid response times, and budget management, Qwen3.6 Max Preview is the superior choice. The performance gap in reasoning is measurable, but the disparity in cost and latency makes Qwen3.6 Max Preview a more pragmatic solution for high-throughput production environments.

Where the numbers come from

The scores, speed and prices in this comparison come from independent third-party model evaluations that Franklin AI syncs each day, and the article was written from a snapshot of them. For the latest results, open the Qwen3.6 Max Preview and GPT-5.5 (xhigh) pages. The AI Benchmark methodology explains how that data is collected and shown.

Comments (0)

No comments yet

Be the first to share your thoughts!