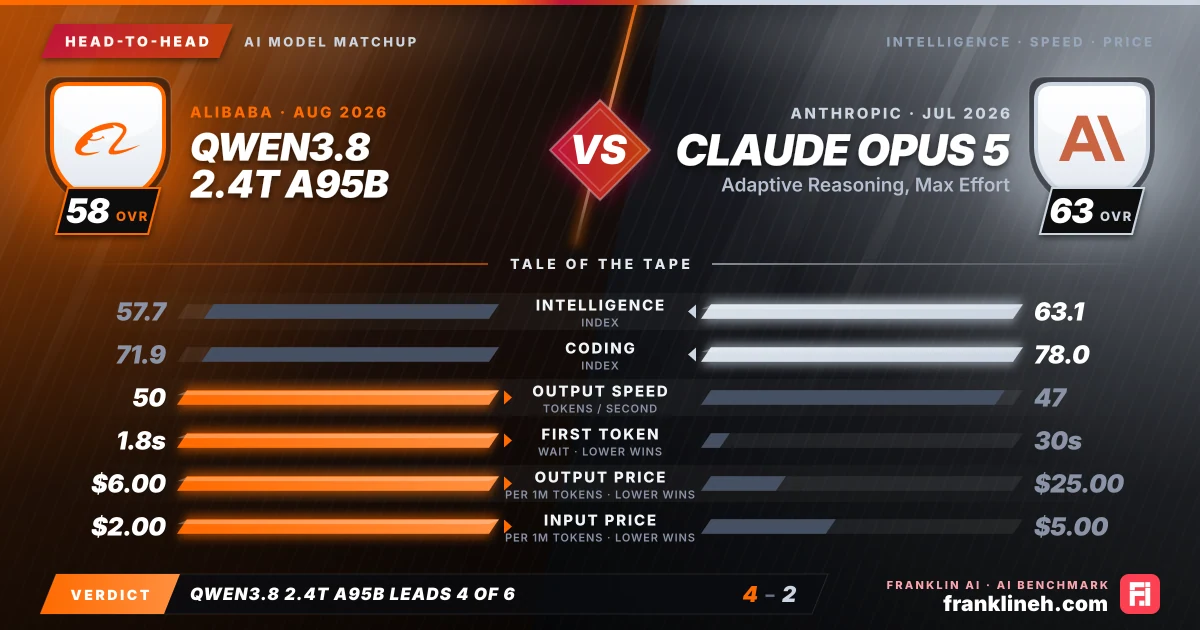
Head-to-head AI model comparison graphic: Qwen3.8 2.4T A95B (Alibaba) vs Claude Opus 5 (Anthropic). Intelligence index 57.7 vs 63.1; coding index 71.9 vs 78.0; output speed 50 vs 47 tokens per second; time to first token 1.8s vs 30s; output price $6.00 vs $25.00 per million tokens; input price $2.00 vs $5.00 per million tokens. franklineh.com
Qwen3.8 2.4T A95B vs Claude Opus 5: head-to-head AI benchmark comparison. Qwen3.8 2.4T A95B leads on output speed, time to first token, output price and input price; Claude Opus 5 leads on intelligence index and coding index.
Head to headUpdated

Qwen3.8 2.4T A95B vs. Claude Opus 5: A Comparative Analysis

This comparison evaluates the Qwen3.8 2.4T A95B and Claude Opus 5, focusing on their distinct performance profiles, benchmark results, and operational costs to help users determine the most efficient model for their specific computational needs.

Pick it for Qwen3.8 2.4T A95B

  • Latency-sensitive chat, support, and interactive product flows
  • Longer responses where sustained output speed matters
  • Higher-volume workloads where blended token cost matters

Pick it for Claude Opus 5 · Adaptive Reasoning, Max Effort

  • Workloads that benefit from the stronger overall intelligence score
  • Coding and agentic tasks where the benchmark edge matters
  • Teams already standardized on Anthropic

By the numbers

These figures describe the two model configurations shown here. A dash means the source snapshot had no usable figure for that metric. Scores, speed and API pricing may change as providers update models.

MetricQwen3.8 2.4T A95BClaude Opus 5 (Adaptive Reasoning, Max Effort)
Intelligence Index57.763.1
Coding Index71.978.0
Input price (per 1M tokens)$2.00$5.00
Output price (per 1M tokens)$6.00$25.00
Output speed (tokens/s)5047
Time to first token1.8s30s
Release date2026-08-122026-07-24

Understanding Benchmark Performance

The performance landscape between the Qwen3.8 2.4T A95B and Claude Opus 5 reveals a trade-off between raw intelligence and specialized capability. Claude Opus 5 holds a clear lead in the Intelligence index at 63.1 compared to Qwen’s 57.7, and it maintains a higher Coding index of 78 against Qwen’s 71.9. These metrics suggest that Claude Opus 5 is better suited for high-level reasoning and complex programming tasks.

However, the benchmark data provides a more nuanced picture. In the GPQA benchmark, the models are nearly identical, with Qwen3.8 scoring 0.935 and Claude Opus 5 scoring 0.932. Claude Opus 5 pulls ahead in the HLE and SciCode benchmarks, scoring 0.549 and 0.557 respectively, while Qwen trails at 0.424 and 0.516. Interestingly, the LCR benchmark shows them performing at a similar level, with Claude Opus 5 at 0.757 and Qwen at 0.753. While both models lack published data for Math indices, their performance across these diverse tests indicates that while Claude Opus 5 is generally more capable in complex reasoning, Qwen remains highly competitive in specific scientific and logic-based domains.

Speed and Cost Considerations

Operational efficiency is a major differentiator for these two models. Qwen3.8 2.4T A95B is significantly more economical, with a blended pricing of $3.00 per million tokens, compared to the $10.00 per million tokens required for Claude Opus 5. The cost disparity is most pronounced in output pricing, where Qwen charges $6.00 per million tokens against Claude’s $25.00. For organizations processing high volumes of data, these cost differences will accumulate rapidly.

Performance speed further highlights the operational differences. Qwen3.8 2.4T A95B delivers an output speed of 49.766 tokens per second with a time-to-first-token (TTFT) of 1.824 seconds. Claude Opus 5, while slightly slower in output speed at 46.871 tokens per second, suffers from a significantly higher TTFT of 30.258 seconds. This latency makes Claude Opus 5 less ideal for real-time, interactive applications, whereas Qwen’s rapid response time makes it well-suited for fluid, conversational interfaces.

Aligning Models with Workflows

Determining which model fits your workflow requires balancing the need for deep reasoning against the requirements for speed and budget. Qwen3.8 2.4T A95B is an excellent candidate for developers and businesses that prioritize rapid iteration and cost-efficiency. Its low latency and lower price point make it highly effective for large-scale API integrations, automated content generation, and high-frequency tasks where waiting 30 seconds for a response is not feasible.

Claude Opus 5, despite its higher cost and latency, is designed for tasks where the quality of reasoning is the primary constraint. Its superior scores in coding and scientific benchmarks suggest it is best utilized for high-stakes projects, such as complex architectural planning, advanced debugging, or research tasks where the model's higher intelligence index can provide more accurate and reliable outputs. Users should reserve Claude Opus 5 for tasks that demand its specific reasoning advantages rather than routine, high-volume operations.

Common questions about Claude Opus 5 Adaptive Reasoning and Qwen3.8 2.4T A95B

Is Qwen3.8 2.4T A95B better than Claude Opus 5 Adaptive Reasoning?

Neither wins everywhere: Claude Opus 5 Adaptive Reasoning scores higher on the intelligence index, 63.1 to 57.7; Qwen3.8 2.4T A95B is 70% cheaper on blended price; and Qwen3.8 2.4T A95B reaches its first token sooner.

Is Claude Opus 5 Adaptive Reasoning or Qwen3.8 2.4T A95B better at coding?

Claude Opus 5 Adaptive Reasoning has the higher coding index, 78.0 against 71.9.

Which is newer, Claude Opus 5 Adaptive Reasoning or Qwen3.8 2.4T A95B?

Qwen3.8 2.4T A95B is newer. It was released on August 12, 2026, 19 days after Claude Opus 5 Adaptive Reasoning (July 24, 2026).

Which model has lower latency?

Their output speeds are close: 47 tokens per second for Claude Opus 5 Adaptive Reasoning and 50 tokens per second for Qwen3.8 2.4T A95B. Qwen3.8 2.4T A95B reaches its first token sooner (1.8 seconds against 30 seconds).

Who makes Claude Opus 5 Adaptive Reasoning and Qwen3.8 2.4T A95B?

Claude Opus 5 Adaptive Reasoning is made by Anthropic and Qwen3.8 2.4T A95B by Alibaba. Claude Opus 5 Adaptive Reasoning was released on July 24, 2026 and Qwen3.8 2.4T A95B on August 12, 2026.

Final whistle

The choice between these models depends on your tolerance for latency and budget constraints. Qwen3.8 2.4T A95B is the superior choice for high-throughput, cost-sensitive applications where rapid response times are critical. Conversely, Claude Opus 5 offers a higher ceiling for complex reasoning and coding tasks, provided the user can accommodate significantly higher costs and a substantial delay in initial response generation.

Where the numbers come from

The scores, speed and prices in this comparison come from independent third-party model evaluations that Franklin AI syncs each day, and the article was written from a snapshot of them. For the latest results, open the Qwen3.8 2.4T A95B and Claude Opus 5 (Adaptive Reasoning, Max Effort) pages. The AI Benchmark methodology explains how that data is collected and shown.

Comments (0)

No comments yet

Be the first to share your thoughts!