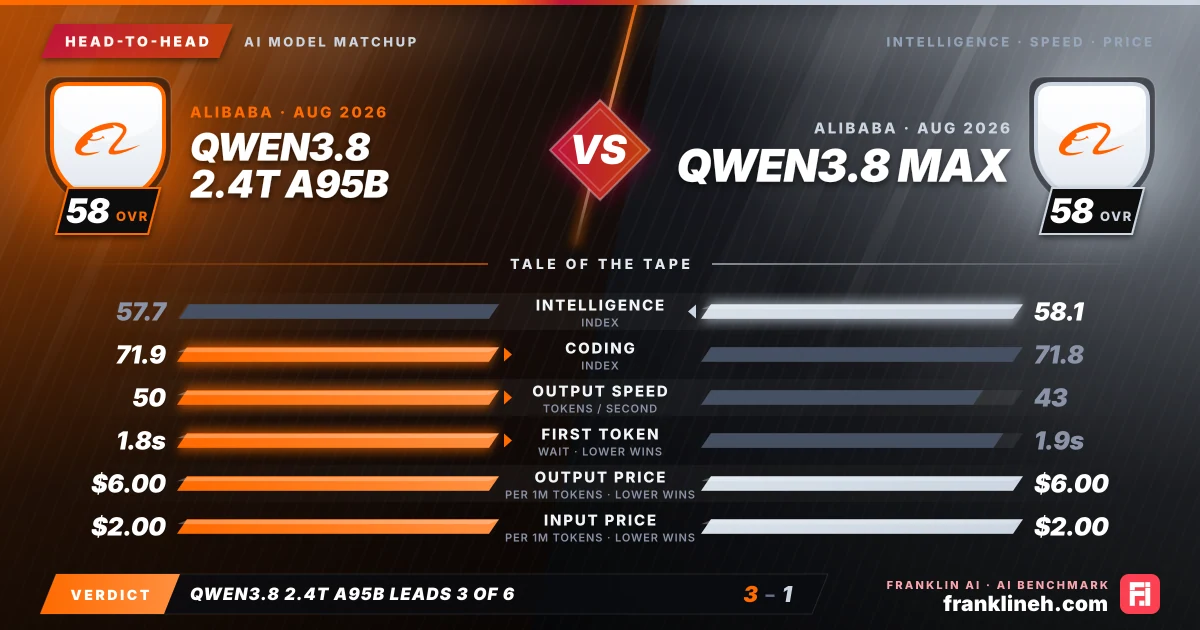
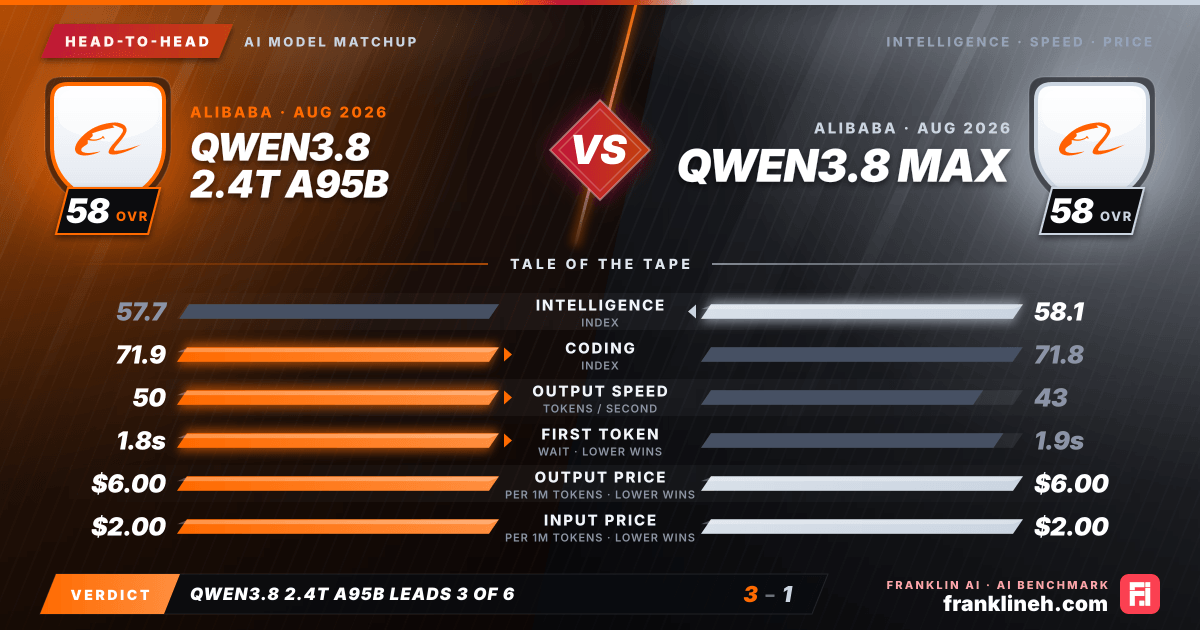
Head-to-head AI model comparison graphic: Qwen3.8 2.4T A95B (Alibaba) vs Qwen3.8 Max (Alibaba). Intelligence index 57.7 vs 58.1; coding index 71.9 vs 71.8; output speed 50 vs 43 tokens per second; time to first token 1.8s vs 1.9s; output price $6.00 vs $6.00 per million tokens; input price $2.00 vs $2.00 per million tokens. franklineh.com
Qwen3.8 2.4T A95B vs Qwen3.8 Max: head-to-head AI benchmark comparison. Qwen3.8 2.4T A95B leads on coding index, output speed and time to first token; Qwen3.8 Max leads on intelligence index; level on output price and input price.
Head to headUpdated

Comparative Analysis: Qwen3.8 2.4T A95B vs. Qwen3.8 Max

This analysis evaluates the performance, speed, and benchmark metrics of Alibaba's Qwen3.8 2.4T A95B and Qwen3.8 Max. While both models share identical pricing structures, they offer distinct trade-offs in latency and specialized intelligence, providing users with different advantages depending on their specific computational requirements.

Pick it for Qwen3.8 2.4T A95B

  • Coding and agentic tasks where the benchmark edge matters
  • Latency-sensitive chat, support, and interactive product flows
  • Longer responses where sustained output speed matters

Pick it for Qwen3.8 Max

  • Workloads that benefit from the stronger overall intelligence score
  • Teams already standardized on Alibaba
  • Use cases where its strongest benchmark rows map to the workload

By the numbers

These figures describe the two model configurations shown here. A dash means the source snapshot had no usable figure for that metric. Scores, speed and API pricing may change as providers update models.

MetricQwen3.8 2.4T A95BQwen3.8 Max
Intelligence Index57.758.1
Coding Index71.971.8
Input price (per 1M tokens)$2.00$2.00
Output price (per 1M tokens)$6.00$6.00
Output speed (tokens/s)5043
Time to first token1.8s1.9s
Release date2026-08-122026-08-03

What the Benchmarks Show

The Qwen3.8 series presents a nuanced picture of performance across various cognitive and technical domains. Qwen3.8 Max holds a slight edge in the overall Intelligence Index at 58.1, compared to the 57.7 recorded by the 2.4T A95B. However, this advantage is not uniform across all testing categories. In coding tasks, the 2.4T A95B actually edges out the Max variant with a score of 71.9 against 71.8, suggesting that the 2.4T A95B may be more finely tuned for software development workflows despite its lower general intelligence score.

Looking at specific academic benchmarks, the models show diverging strengths. The 2.4T A95B performs better on the GPQA benchmark (0.935 vs. 0.927) and the LCR benchmark (0.753 vs. 0.743). In contrast, Qwen3.8 Max demonstrates higher proficiency in the HLE (0.43 vs. 0.424) and SciCode (0.529 vs. 0.516) benchmarks. These results indicate that while the Max model is generally more capable in scientific and high-level reasoning tasks, the 2.4T A95B is more robust in specialized coding and complex logic scenarios.

Speed and Cost

For organizations managing high-volume AI integration, the cost structure is straightforward. Both models are priced identically, with an input cost of $2.00 per million tokens and an output cost of $6.00 per million tokens, resulting in a blended rate of $3.00 per million tokens. Because the financial investment is identical, the decision-making process shifts entirely to operational performance and latency metrics.

There is a notable difference in output speed and responsiveness. Qwen3.8 2.4T A95B is the faster model, delivering an output speed of 49.766 tokens per second, significantly outpacing the 43.408 tokens per second provided by Qwen3.8 Max. Additionally, the 2.4T A95B offers a faster time to first token at 1.824 seconds, compared to 1.946 seconds for the Max model. These differences, while measured in fractions of a second, can accumulate into significant efficiency gains in real-time agentic applications or high-concurrency environments.

Which Model Fits Which Workflow

Determining the right model requires an assessment of your latency tolerance versus your need for peak intelligence. The Qwen3.8 2.4T A95B is optimized for speed-sensitive environments. Its superior output speed and faster time to first token make it an ideal candidate for interactive applications, such as real-time chat interfaces or automated agents where user experience is tied to immediate response times. Its slight lead in coding benchmarks further cements its utility for developers who need rapid code generation and iteration.

Qwen3.8 Max is better suited for deep-reasoning tasks where the final output quality is more critical than the speed of delivery. Its higher intelligence index and superior performance in scientific and complex reasoning benchmarks suggest that it should be reserved for batch processing, research analysis, or complex document synthesis where the model has more time to process the request. While the performance gap is narrow, the Max model provides the extra cognitive headroom required for tasks that push the boundaries of current AI capabilities.

Frequently asked questions

Is Qwen3.8 2.4T A95B better than Qwen3.8 Max?

Qwen3.8 2.4T A95B leads on every measure the catalogue separates: they are level on the intelligence index (57.7 and 58.1); their blended prices are about the same; and Qwen3.8 2.4T A95B streams output 1.1 times as fast.

Which model has lower latency?

Qwen3.8 2.4T A95B generates output faster, at 50 tokens per second against 43 tokens per second. Time to first token is similar: 1.8 seconds and 1.9 seconds.

Which is better for coding, Qwen3.8 2.4T A95B or Qwen3.8 Max?

Their coding index scores are level at 71.9 and 71.8.

Are Qwen3.8 2.4T A95B and Qwen3.8 Max from the same company?

Both are Alibaba models, listed as separate models in the catalogue. Qwen3.8 2.4T A95B was released on August 12, 2026 and Qwen3.8 Max on August 3, 2026.

Which is newer, Qwen3.8 2.4T A95B or Qwen3.8 Max?

Qwen3.8 2.4T A95B is newer. It was released on August 12, 2026, 9 days after Qwen3.8 Max (August 3, 2026).

Final whistle

The choice between these models depends on your priority: raw speed or marginal intelligence gains. Qwen3.8 2.4T A95B is the superior choice for high-throughput applications where latency is critical. Conversely, if your workload demands the highest possible intelligence index and you can tolerate a slower output speed, Qwen3.8 Max is the more capable, albeit slightly slower, option. Both models are priced identically, making the decision purely a matter of performance optimization for your specific use case.

Where the numbers come from

The scores, speed and prices in this comparison come from independent third-party model evaluations that Franklin AI syncs each day, and the article was written from a snapshot of them. For the latest results, open the Qwen3.8 2.4T A95B and Qwen3.8 Max pages. The AI Benchmark methodology explains how that data is collected and shown.

Comments (0)

No comments yet

Be the first to share your thoughts!