
What the benchmarks show
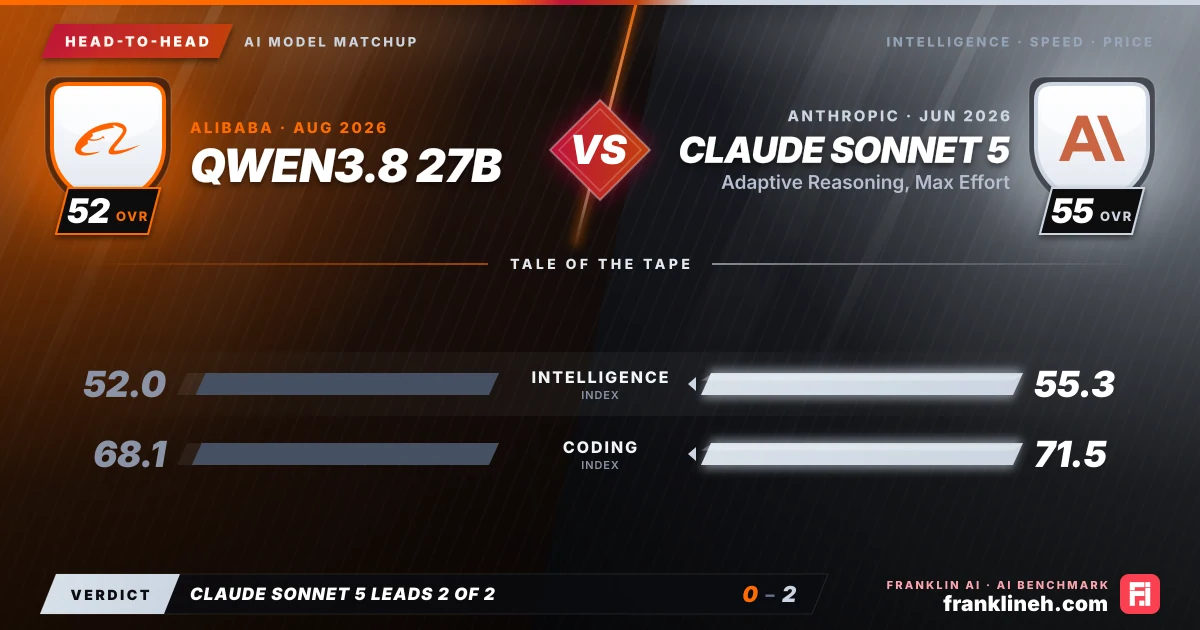
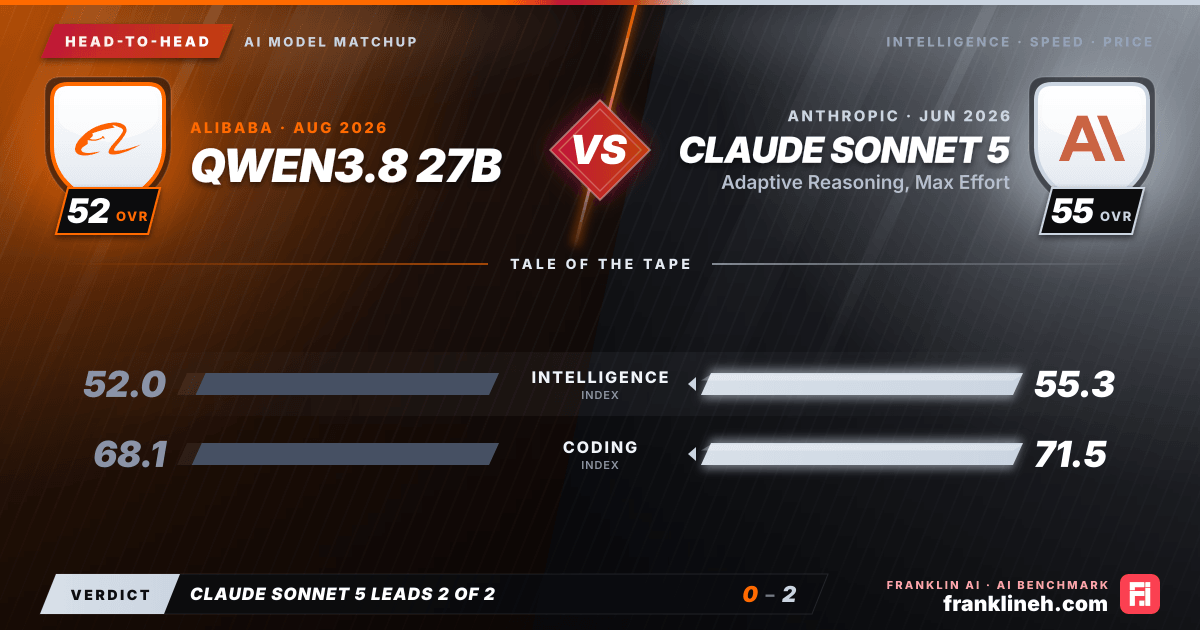
When evaluating the raw performance metrics of Qwen3.8 27B and Claude Sonnet 5, a clear distinction emerges in specialized reasoning tasks. Claude Sonnet 5 (Adaptive Reasoning, Max Effort) holds a lead in the Intelligence index at 55.3 compared to Qwen3.8’s 52. This advantage is mirrored in the Coding index, where Claude scores 71.5 against Qwen’s 68.1.
Looking at specific benchmarks, Claude Sonnet 5 consistently outperforms Qwen3.8 27B in HLE (0.413 vs. 0.339) and SciCode (0.536 vs. 0.447). These metrics suggest that Claude is better suited for complex, multi-step scientific and programming challenges. However, Qwen3.8 27B remains highly competitive in the LCR benchmark, scoring 0.773, which slightly edges out Claude’s 0.77. Both models show similar proficiency in GPQA, with Claude at 0.911 and Qwen at 0.905. While Claude holds the edge in depth, the narrow gap in general intelligence suggests that Qwen3.8 is a formidable model for tasks that do not require the absolute peak of specialized reasoning.
Speed and cost
The most striking difference between these two models lies in their economic profiles. Qwen3.8 27B is offered at no cost, with input and output pricing set at $0.00 per million tokens. This makes it an ideal candidate for high-volume applications where budget constraints are the primary concern. In contrast, Claude Sonnet 5 operates on a premium pricing model, charging $2.00 per million input tokens and $10.00 per million output tokens, resulting in a blended cost of $4.00 per million tokens.
Operational performance also differs significantly. Claude Sonnet 5 provides a documented output speed of 83.415 tokens per second, though it carries a substantial time-to-first-token latency of 135.72 seconds. Performance data for Qwen3.8 27B remains unknown, making it difficult to predict how it will handle real-time, low-latency requirements compared to the established, albeit slower-starting, Claude Sonnet 5.
Which model fits which workflow
Selecting the right model requires an assessment of your project's tolerance for cost and the necessity for high-end reasoning. Claude Sonnet 5 is designed for workflows where the cost of an error is high. Its superior scores in coding and scientific benchmarks indicate that it is better equipped to handle complex logic, debugging, and research-heavy tasks where precision is paramount. The "Adaptive Reasoning" capability suggests it is optimized for tasks that require deep, iterative processing.
Conversely, Qwen3.8 27B is an excellent fit for developers and organizations building at scale. Because it is free to use, it removes the financial barrier to entry, making it suitable for prototyping, large-scale data processing, or applications where the cost of API calls would otherwise be prohibitive. While it may lack the slight edge in scientific and coding benchmarks found in Claude, its performance is robust enough for a wide range of general-purpose AI tasks.
Decision takeaway
Ultimately, the decision rests on whether your use case demands the incremental gains in intelligence provided by Anthropic or the total cost-efficiency provided by Alibaba. If your project involves high-stakes software development or complex scientific analysis, the performance metrics favor Claude Sonnet 5. If you are operating under strict budget limitations or require a model for high-throughput, general-purpose tasks, Qwen3.8 27B provides a high-value alternative that does not sacrifice significant intelligence.
Comments (0)
to join the discussion
No comments yet
Be the first to share your thoughts!