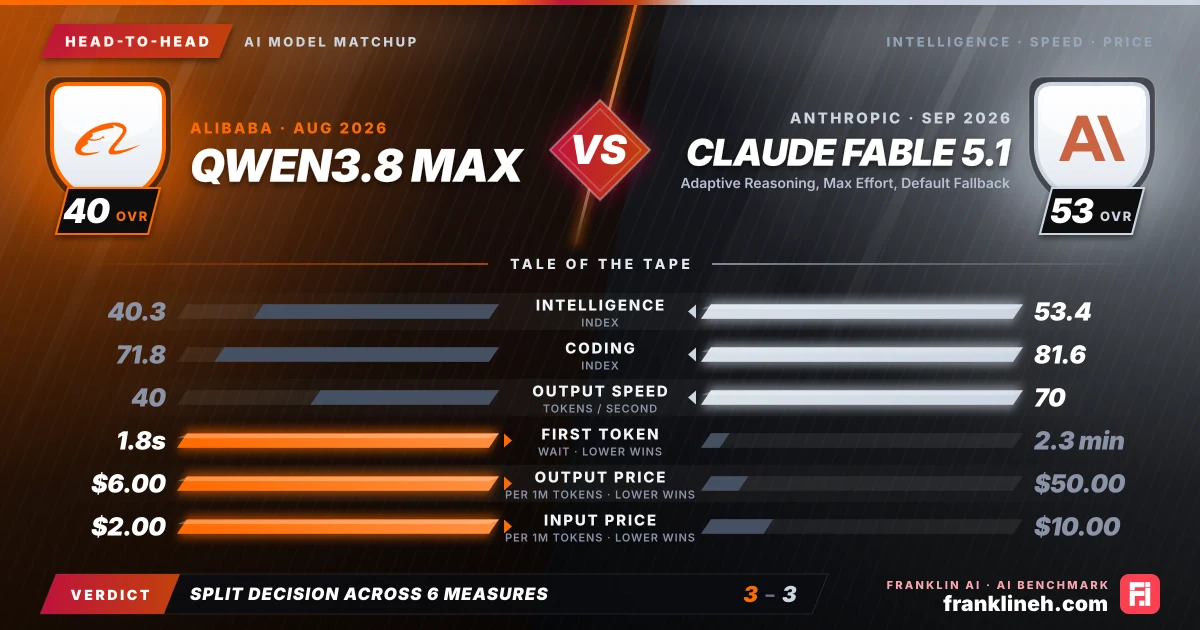
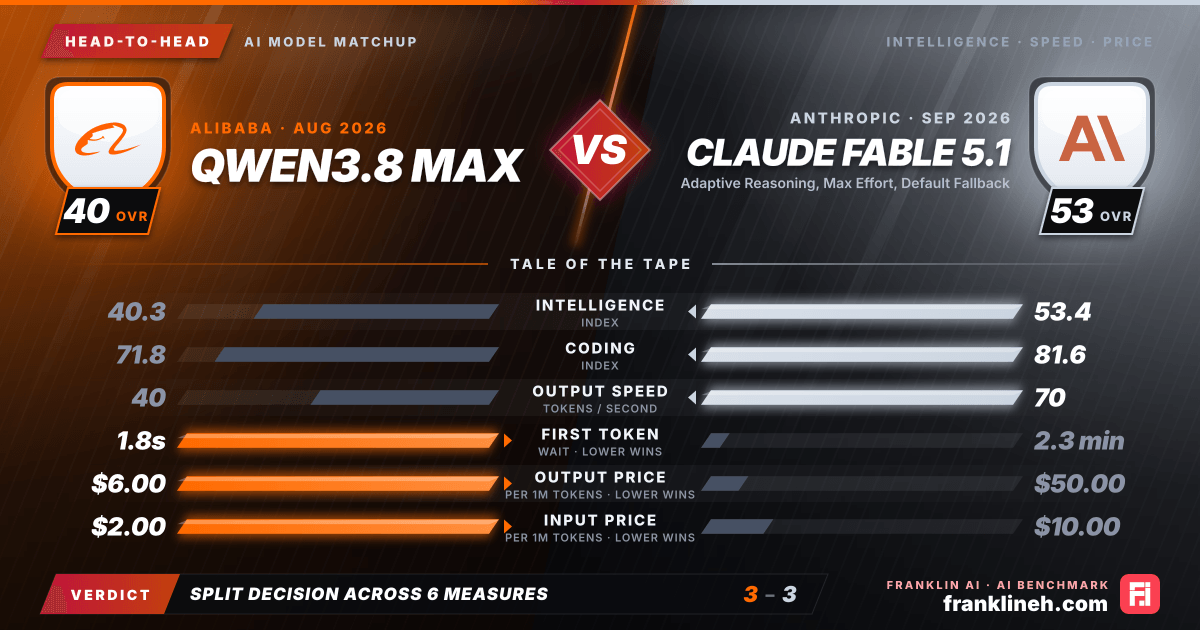
Head-to-head AI model comparison graphic: Qwen3.8 Max (Alibaba) vs Claude Fable 5.1 (Anthropic). Intelligence index 40.3 vs 53.4; coding index 71.8 vs 81.6; output speed 40 vs 70 tokens per second; time to first token 1.8s vs 2.3 min; output price $6.00 vs $50.00 per million tokens; input price $2.00 vs $10.00 per million tokens. franklineh.com
Qwen3.8 Max vs Claude Fable 5.1: head-to-head AI benchmark comparison. Qwen3.8 Max leads on time to first token, output price and input price; Claude Fable 5.1 leads on intelligence index, coding index and output speed.
Head to headUpdated

Qwen3.8 Max vs. Claude Fable 5.1: A Comparative Analysis

This analysis compares Alibaba’s Qwen3.8 Max and Anthropic’s Claude Fable 5.1. While Claude Fable 5.1 offers superior reasoning and coding capabilities, Qwen3.8 Max provides a significantly more cost-effective and responsive alternative for high-volume production environments.

Pick it for Qwen3.8 Max

  • Latency-sensitive chat, support, and interactive product flows
  • Higher-volume workloads where blended token cost matters
  • Teams already standardized on Alibaba

Pick it for Claude Fable 5.1 · Adaptive Reasoning, Max Effort, Default Fallback

  • Workloads that benefit from the stronger overall intelligence score
  • Coding and agentic tasks where the benchmark edge matters
  • Longer responses where sustained output speed matters

By the numbers

These figures describe the two model configurations shown here. A dash means the source snapshot had no usable figure for that metric. Scores, speed and API pricing may change as providers update models.

MetricQwen3.8 MaxClaude Fable 5.1 (Adaptive Reasoning, Max Effort, Default Fallback)
Intelligence Index40.353.4
Coding Index71.881.6
Input price (per 1M tokens)$2.00$10.00
Output price (per 1M tokens)$6.00$50.00
Output speed (tokens/s)4070
Time to first token1.8s2.3 min
Release date2026-08-032026-09-01

Benchmarking Intelligence and Capability

When evaluating the raw performance metrics of Qwen3.8 Max and Claude Fable 5.1, a clear performance gap emerges. Claude Fable 5.1, released on September 1, 2026, holds an intelligence index of 53.4 and a coding index of 81.6. In contrast, Qwen3.8 Max, released on August 3, 2026, registers an intelligence index of 40.3 and a coding index of 71.8. Across standardized benchmarks, Claude Fable 5.1 consistently outperforms Qwen3.8 Max, scoring 0.937 on GPQA compared to 0.927, and 0.591 on HLE compared to 0.43. The trend continues in SciCode and LCR metrics, where Claude maintains a lead. While both models lack publicly disclosed math index scores, the existing data suggests that Claude Fable 5.1 is better suited for tasks requiring deep logical synthesis and complex programming assistance.

Speed and Cost Tradeoffs

The economic and operational differences between these models are stark. Qwen3.8 Max is positioned as a high-efficiency model, with a blended pricing structure of $3.00 per million tokens. Claude Fable 5.1, by comparison, commands a premium, with a blended cost of $20.00 per million tokens. This represents a significant investment for large-scale deployments.

Operational latency further distinguishes the two. Qwen3.8 Max offers a time-to-first-token of 1.82 seconds and an output speed of 40.229 tokens per second, making it highly responsive for real-time applications. Claude Fable 5.1, while capable of a higher output speed at 70.306 tokens per second, suffers from a substantial time-to-first-token of 136.473 seconds. This high initial latency suggests that Claude Fable 5.1 is optimized for deep, batch-processed reasoning rather than interactive, low-latency user interfaces.

Workflow Suitability

Determining which model fits a specific workflow requires an assessment of the cost-to-performance ratio. Claude Fable 5.1 is designed for high-complexity environments where the cost of an error is high. Its performance on alignment and reasoning benchmarks makes it a robust tool for automated research and advanced coding tasks. However, the high cost and significant startup latency make it less ideal for high-frequency, lightweight API calls.

Qwen3.8 Max excels in scenarios where throughput and budget are the primary constraints. Its rapid time-to-first-token makes it a superior choice for chat-based applications or systems requiring immediate feedback. By sacrificing a degree of peak reasoning capability, users gain a model that is nearly seven times more cost-effective and significantly more responsive in initial interaction.

Decision Takeaway

Ultimately, the decision rests on whether your project requires the absolute ceiling of current AI reasoning or a reliable, high-speed workhorse. If your infrastructure can accommodate the latency and budget requirements of Claude Fable 5.1, the performance gains in coding and complex logic are measurable. Conversely, for developers building scalable, cost-sensitive applications, Qwen3.8 Max offers a more balanced profile that avoids the performance bottlenecks associated with the more intensive Claude model.

Common questions about Claude Fable 5.1 Adaptive Reasoning and Qwen3.8 Max

Is Claude Fable 5.1 Adaptive Reasoning better than Qwen3.8 Max?

It depends on what you need: Claude Fable 5.1 Adaptive Reasoning scores higher on the intelligence index, 53.4 to 40.3; Qwen3.8 Max is 85% cheaper on blended price; Claude Fable 5.1 Adaptive Reasoning streams output 1.7 times as fast; and Qwen3.8 Max reaches its first token sooner.

Which is faster, Claude Fable 5.1 Adaptive Reasoning or Qwen3.8 Max?

Claude Fable 5.1 Adaptive Reasoning generates output faster, at 70 tokens per second against 40 tokens per second. Qwen3.8 Max reaches its first token sooner (1.8 seconds against 2.3 minutes). Counting the first-token wait, Qwen3.8 Max finishes first for any reply shorter than about 13,000 tokens.

Which is better for coding, Claude Fable 5.1 Adaptive Reasoning or Qwen3.8 Max?

Claude Fable 5.1 Adaptive Reasoning has the higher coding index, 81.6 against 71.8.

Which is newer, Claude Fable 5.1 Adaptive Reasoning or Qwen3.8 Max?

Claude Fable 5.1 Adaptive Reasoning is newer. It was released on September 1, 2026, 29 days after Qwen3.8 Max (August 3, 2026).

Are Claude Fable 5.1 Adaptive Reasoning and Qwen3.8 Max from the same company?

Claude Fable 5.1 Adaptive Reasoning is made by Anthropic and Qwen3.8 Max by Alibaba. Claude Fable 5.1 Adaptive Reasoning was released on September 1, 2026 and Qwen3.8 Max on August 3, 2026.

Final whistle

The choice between these models depends on the priority of your specific application. Claude Fable 5.1 is the clear choice for complex, high-stakes reasoning tasks where accuracy is paramount. However, if your workflow requires rapid, high-volume processing at a fraction of the cost, Qwen3.8 Max is the more efficient engine. Organizations should balance the performance gains of Claude against the substantial pricing and latency advantages offered by Alibaba’s latest release.

Where the numbers come from

The scores, speed and prices in this comparison come from independent third-party model evaluations that Franklin AI syncs each day, and the article was written from a snapshot of them. For the latest results, open the Qwen3.8 Max and Claude Fable 5.1 (Adaptive Reasoning, Max Effort, Default Fallback) pages. The AI Benchmark methodology explains how that data is collected and shown.

Comments (0)

No comments yet

Be the first to share your thoughts!