
Solar Mini 4 and Claude Opus 5.5 were both released on September 22, 2026, but they occupy very different points in the cost-performance tradeoff. Upstage’s model is priced for economical, responsive use, while Anthropic’s Claude Opus 5.5 configuration—listed as Adaptive Reasoning, Max Effort, Default Fallback—delivers materially higher benchmark scores at a much higher price.
What the benchmarks show
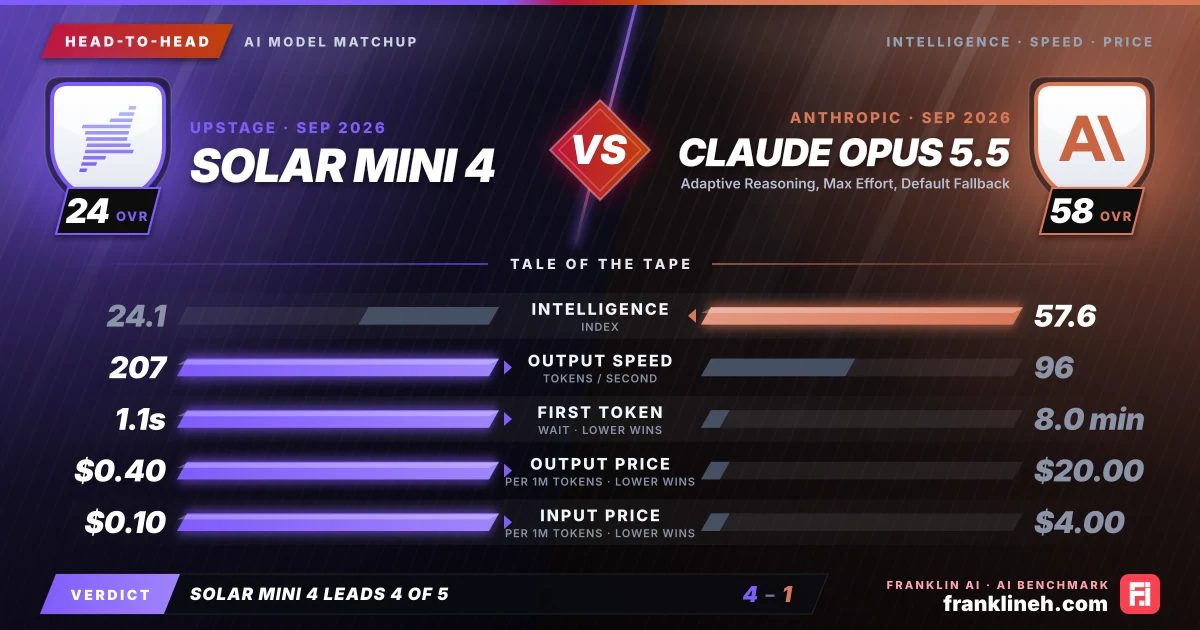
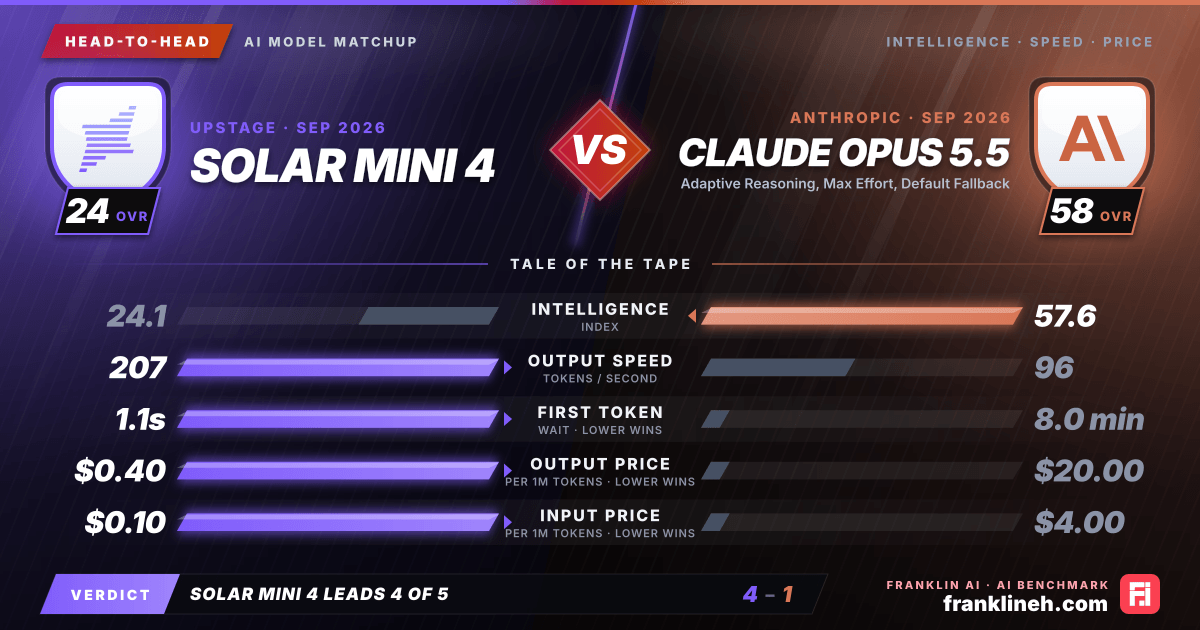
Claude Opus 5.5 leads on every reported capability measure. Its intelligence index is 57.6, compared with 24.1 for Solar Mini 4. On the Humanity’s Last Exam benchmark, Claude scores 0.614 versus Solar Mini 4 at 0.258. The gap is also visible on SciCode, where Claude reaches 0.669 compared with 0.476.
The long-context result is closer. Solar Mini 4 records an LCR score of 0.8333, while Claude Opus 5.5 reaches 0.8467. That difference suggests Claude has an edge on the reported long-context evaluation, but it is substantially narrower than the gaps on HLE, SciCode, and the overall intelligence index. For applications centered on retrieving or handling long inputs, Solar Mini 4’s lower price may therefore be more relevant than the relatively modest benchmark separation.
Coding and math index values are unknown for both models in the supplied data. The SciCode result provides one relevant comparison, but it should not be treated as a complete coding evaluation. Likewise, the intelligence index and HLE score indicate broad benchmark performance rather than guaranteed results for every production task.
Speed and cost
Solar Mini 4 has the clearer operational advantage. Its output speed is 207.104 tokens per second, more than twice Claude Opus 5.5’s 95.831 tokens per second. Solar Mini 4 also has a listed time to first token of 1.125 seconds. Claude’s listed time to first token is 479.922 seconds, making responsiveness a major concern for interactive use if that figure reflects the expected serving experience.
The pricing difference is equally pronounced. Solar Mini 4 costs $0.10 per million input tokens and $0.40 per million output tokens, with a blended price of $0.17 per million. Claude Opus 5.5 costs $4.00 per million input tokens and $20.00 per million output tokens, with a blended price of $8.00 per million. On the blended figure, Claude is about 47 times more expensive.
That premium can be justified when a higher-quality answer reduces downstream review, retries, or failed task execution. It is harder to justify for simple generation, routine transformations, or workloads that process large volumes of tokens without needing the strongest available benchmark performance.
Which model fits which workflow
Solar Mini 4 is the more practical choice for latency-sensitive applications, frequent API calls, and cost-controlled deployments. Its output rate supports faster completion, and its low input and output prices make experimentation and scaling less financially demanding. It may also suit long-context workflows where the LCR difference is not decisive and throughput matters more than a small benchmark lead.
Claude Opus 5.5 is better suited to tasks where difficult reasoning, research-style performance, or code-related capability is worth paying for. Its stronger HLE and SciCode scores, along with the higher intelligence index, indicate a meaningful advantage on the supplied evaluations. However, teams should account for both the cost premium and the unusually high listed time to first token. It may fit asynchronous or high-value workflows better than conversational systems requiring immediate responses.
Decision takeaway
The data supports a straightforward division. Solar Mini 4 offers speed and economy, with competitive long-context performance relative to its price. Claude Opus 5.5 offers stronger measured capability across all listed benchmarks, but at substantially higher token costs and much slower initial response.
For a default production model, Solar Mini 4 is the stronger efficiency choice when the task can tolerate lower benchmark performance. Claude Opus 5.5 is the stronger capability choice when answer quality on demanding evaluations matters more than throughput, latency, or budget. Since coding and math index scores are unavailable for both, those decisions should be validated with task-specific testing before deployment.
Comments (0)
to join the discussion
No comments yet
Be the first to share your thoughts!