
What the benchmarks show
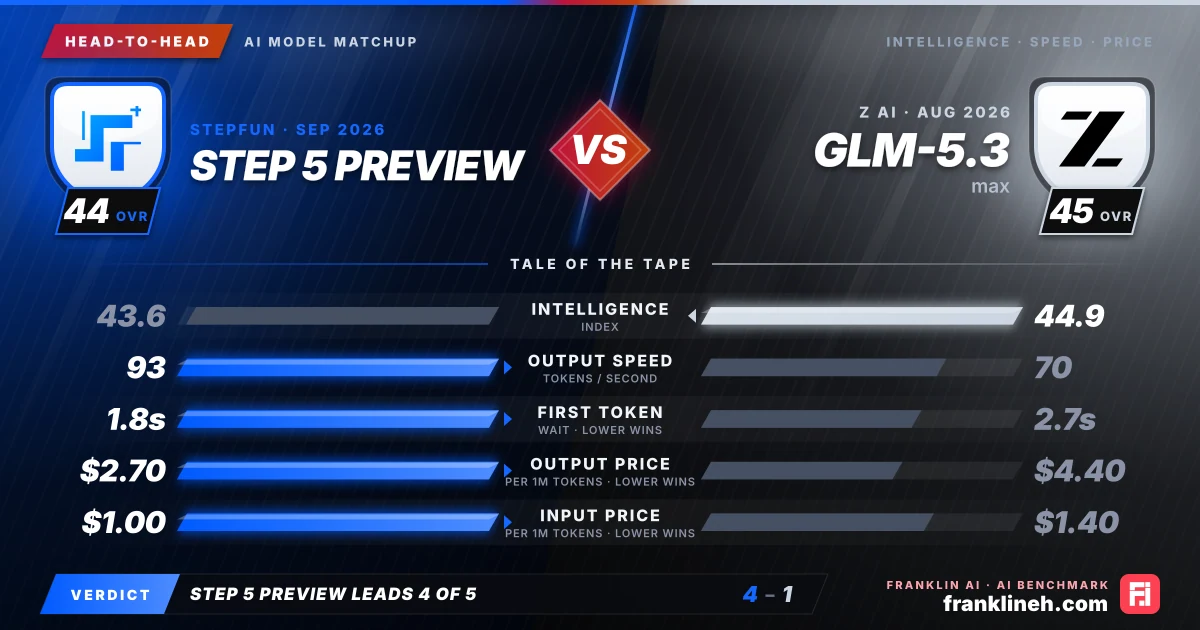
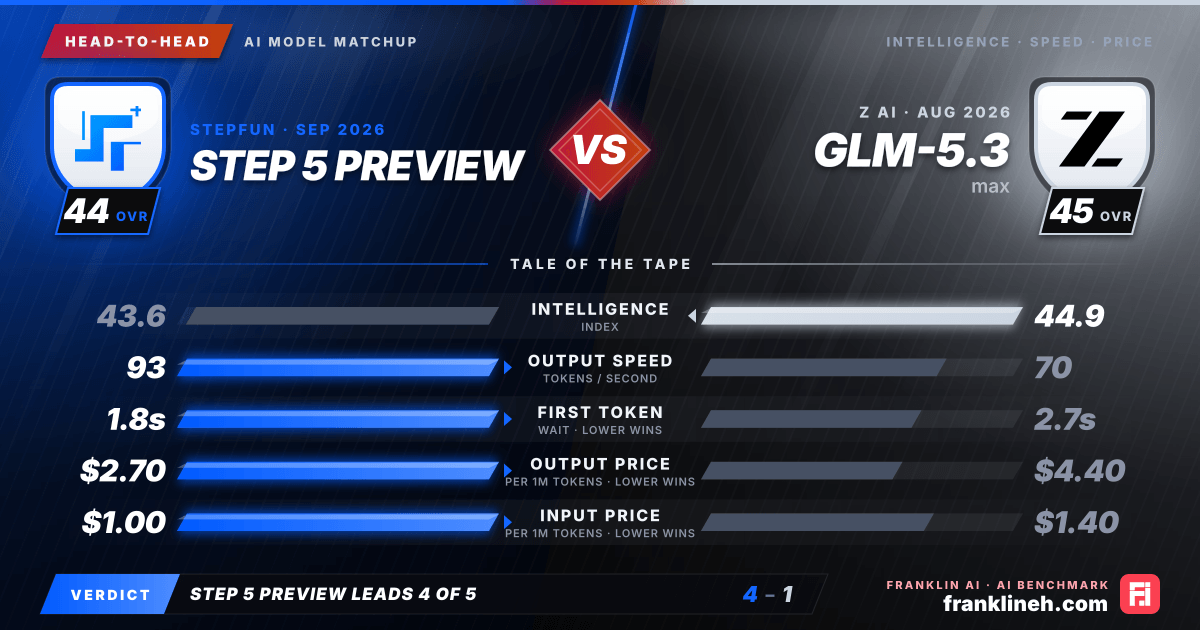
Evaluating the intelligence of Step 5 Preview and GLM-5.3 (max) reveals distinct strengths across different domains. GLM-5.3 (max) leads in general intelligence with an index of 44.9 compared to Step 5’s 43.6. This advantage is reflected in its GPQA benchmark score of 0.917, suggesting a higher aptitude for complex, expert-level reasoning. Furthermore, GLM-5.3 (max) demonstrates a clear proficiency in development tasks, boasting a coding index of 74.8.
Step 5 Preview, however, remains competitive in specific technical evaluations. While it trails slightly in the SciCode benchmark (0.589 vs. 0.590), it outperforms GLM-5.3 (max) in the HLE benchmark with a score of 0.465 against 0.423. Additionally, Step 5 shows a significant lead in the LCR benchmark, scoring 0.883 compared to 0.797 for GLM-5.3. These metrics suggest that while GLM-5.3 (max) is better suited for high-level reasoning and coding, Step 5 Preview offers more consistent performance in specific logic-based environments.
Speed and cost
Operational efficiency is a primary differentiator between these two models. Step 5 Preview is significantly more cost-effective, with a blended pricing rate of $1.43 per 1M tokens, compared to the $2.15 per 1M tokens required for GLM-5.3 (max). This represents a substantial cost saving for high-volume users. The pricing structure for Step 5 is also more granular, with output costs set at $2.70 per 1M tokens, whereas GLM-5.3 (max) charges $4.40 for the same output volume.
Beyond pricing, Step 5 Preview offers superior responsiveness. It achieves an output speed of 92.781 tokens per second, notably faster than the 70.058 tokens per second delivered by GLM-5.3 (max). Furthermore, the time to first token for Step 5 is 1.803 seconds, providing a snappier user experience compared to the 2.672 seconds required by GLM-5.3 (max). For applications where latency is critical, Step 5 is the clear technical winner.
Which model fits which workflow
Selecting the right model requires aligning these technical profiles with project goals. GLM-5.3 (max) is designed for workflows that demand high-level reasoning and complex coding assistance. Its higher intelligence index and specific coding index make it a reliable partner for software engineering tasks or research-oriented projects where accuracy in difficult, multi-step queries is paramount. Despite the higher cost and slower latency, the depth of its reasoning capabilities provides a safety net for mission-critical, high-complexity tasks.
Step 5 Preview is optimized for high-velocity, production-scale environments. Its speed and lower cost structure make it ideal for real-time applications, such as customer-facing chatbots or large-scale data processing pipelines where every millisecond and cent counts. The model’s performance in the LCR benchmark suggests it is particularly adept at handling structured logic tasks, making it a strong candidate for automated workflows that require rapid, consistent execution without the overhead of a more expensive, general-purpose model.
Comments (0)
to join the discussion
No comments yet
Be the first to share your thoughts!