

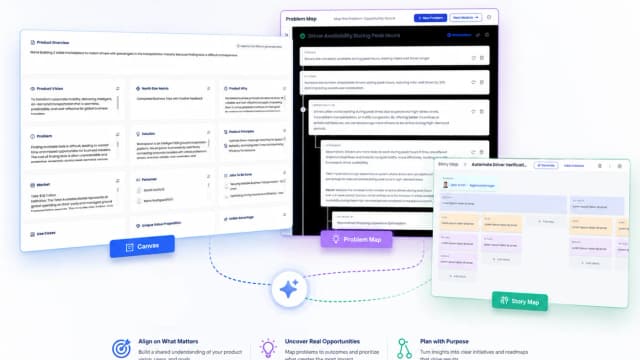
Velociti
Velociti connects product-discovery documents with initiatives and execution work, using Velo AI to generate and maintain that context.
Wafer provides an inference-serving platform that it says adapts the serving stack to a workload over time; evaluate performance on your own traffic.
Wafer describes an inference-serving platform that adapts to the behavior of a workload. Its public homepage focuses on improving the serving stack for performance, reliability and efficiency as inference continues.
The Wafer homepage says it learns how a workload behaves and optimizes serving over time. Its illustrative sequence shows an engine being tuned, kernels fused and traffic re-tuned. Those examples describe the product's approach; the displayed token rates are not a benchmark Franklin has reproduced.
A useful evaluation should use the model, request sizes and traffic pattern your application expects. Compare time to the first useful response with sustained throughput, rather than selecting a provider on one token-rate figure. Keep the input and output settings consistent so a speed difference is not caused by a shorter answer or a different task.
The page includes testimonials about low latency at higher request volumes and a case claim involving faster Kimi inference on AMD hardware. These are vendor-published accounts, not a promise that another model or deployment will achieve the same result.
Ask for the conditions behind any performance comparison: hardware, model configuration, concurrency and the baseline used. Check output quality alongside speed with examples representative of your application. A statement that a customer avoided an accuracy trade-off does not establish identical behavior for every workload or a guarantee for your own inputs.
Wafer provides actions to start building or open its app, as well as navigation for cases and a dedicated offering. The homepage does not list a complete price schedule, retention policy or service-level agreement. Obtain those details before sending private production traffic or making the platform a critical dependency.
Start with a bounded, non-sensitive evaluation and inspect error handling under the conditions you expect to run. Confirm which models and regions the account supports, how usage is metered and what a dedicated arrangement includes. The decision should rest on the actual configuration and contract you can use, with the homepage's performance claims serving as questions to test rather than assumed outcomes.
Before you try it
Wafer asks for the model, real traffic shape and service-level objective. It says those inputs drive an endpoint tuned to the workload, rather than selecting a configuration only from a generic benchmark.
Official sourceThe described search spans model choices, serving engines, kernels and hardware, including batching, decoding and quantisation. Wafer profiles latency and throughput bottlenecks across these interacting layers instead of presenting one universal speed setting.
Official sourceAccording to Wafer, a candidate must preserve correctness and meet the workload's reliability targets before deployment. It then measures again as traffic, models or hardware change; assess those claims against your own workload rather than assuming a benchmark improvement transfers unchanged.
Official sourceVelociti connects product-discovery documents with initiatives and execution work, using Velo AI to generate and maintain that context.
Sam3d2.com offers image-to-3D and text-to-3D drafts with browser previews and credit-based generation; review geometry and licensing before production use.

Leakless advertises monitoring for stolen creator content and automated takedown requests, with one subscription that includes reupload monitoring and search-delisting requests.

RenoAI generates room and space redesign concepts from photos, with controls for style, furniture, color and lighting.

BirthdayCardGenerator creates birthday cards, posters, and invitations from prompts and optional reference images, with subscription and permanent credit options.

Facefame uses an uploaded photo to create AI avatars, professional portraits, ID-style images, and animated photo or video content.