
AI Glossary
Inference server
What does “Inference server” mean?
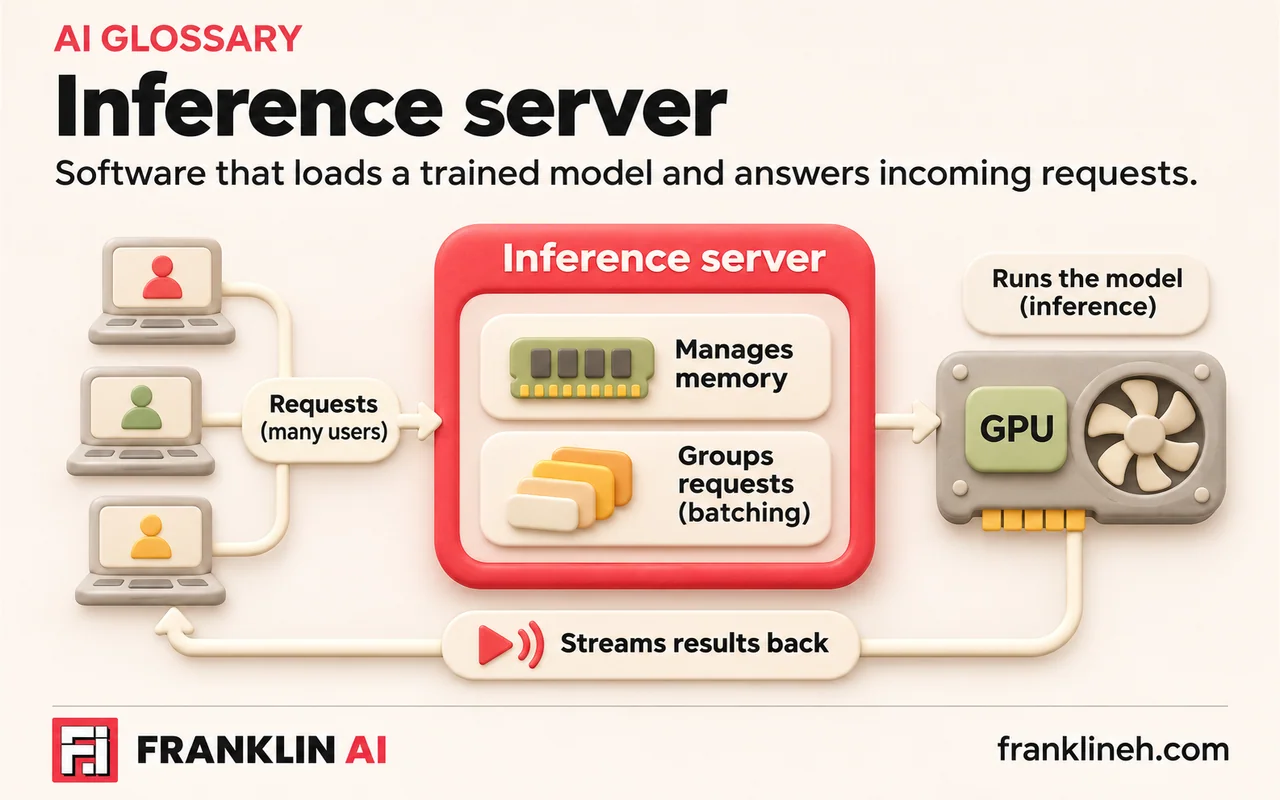
Inference server: Software that loads a trained model and answers incoming requests, often from many users at once. It manages memory, groups requests together and streams results back. Open-source options include vLLM and Nvidia's Triton Inference Server.
What is an example of “Inference server”?
When an app sends a prompt to a hosted chatbot, an inference server on a GPU machine is what actually generates the reply.